We did not pick one cache — we mapped each workload to CAP
On a live gaming platform, someone always asks: “Hazelcast or Redis?”
As if one logo must win the whole cluster.
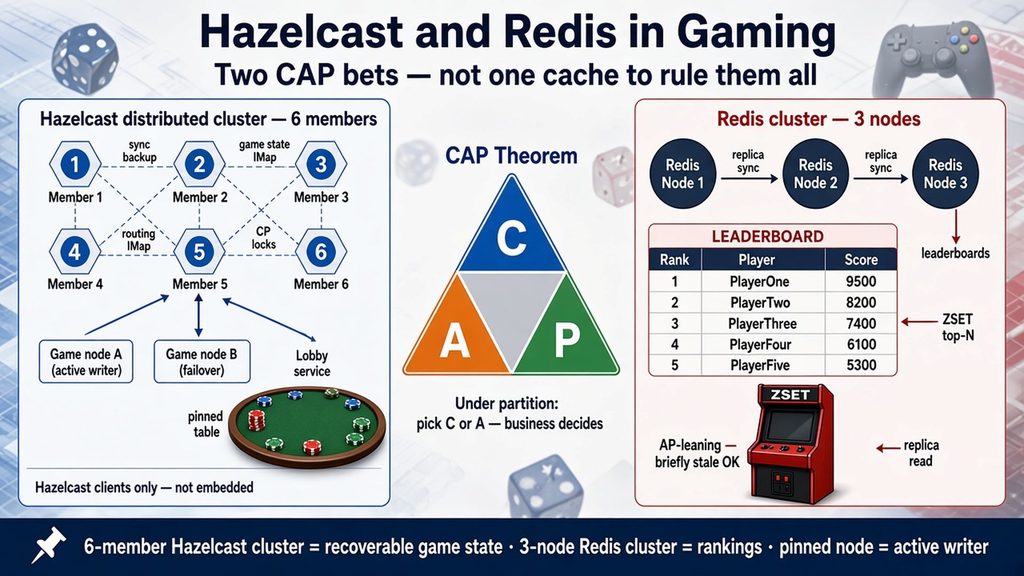
We did not choose that way. After modularizing game engines — lobby, game, transactions on their own paths — we needed recoverable game state when a node dies, coordination across JVM services, and high-volume leaderboard reads that could tolerate a little lag. Hazelcast and Redis each fit a different CAP shape.
This article is Hazelcast and Redis — not vs. How we use a remote Hazelcast distributed cluster for replicated table state and failover, and Redis for leaderboards. CAP is the lens; live tables, pinned game nodes, and money kept off the tick are the examples.
Architecture, to us, is not picking logos. It is design, prototypes, and naming tradeoffs out loud. Choose C or A because the business can live with the downside — CAP is a lens, not a bible.
CAP in one minute
Letter
Plain meaning
C — Consistency
Every read sees the latest write (or you get an error)
A — Availability
Non-failing nodes keep answering
P — Partition tolerance
System keeps running when the network splits
P is not optional at scale. Under partition you pick C (refuse stale / fence / error) or A (keep serving, maybe stale).
If the business says…
Lean toward
Gaming example
“Wrong money or double owner is unacceptable”
C (refuse / fence / error)
Table ownership, routing on failover
“Empty screen or long outage hurts more than slightly stale data”
A (keep serving)
Leaderboard top 100, presence hints
Workload
CAP lean
Tool
Live table state + failover
C when JVM or grid member fails
Hazelcast IMap + CP
Leaderboard top 100
A — empty board worse than stale rank
Redis ZSET
Wallet / payout
Durable C
DB + queue
Same company, same platform — different maps, different clusters, different backup settings.
Our model: pinned node + IMap replica
We pin one game to one game node. That node is the active writer — pot, seats, turn, timers — single owner, local memory, fast tick.
Every state-changing action (fold, call, raise, timer) also replicates a snapshot to Hazelcast `IMap` on a remote cluster with sync backup. If the pinned node dies, a new node loads that snapshot and resumes — same pot, same turn.
Layer
Role
Pinned game node (local)
Active writer during play — every fold/call/raise mutates local state first (fast tick)
Hazelcast IMap (sync backup)
Recovery copy — replicate snapshot on each state change; new node loads table if pinned node dies
CP lock + fencing
Only one game node may resume the table after failover
Table → node routing (IMap)
Where clients reconnect after failover
Queue + DB
Buy-in / payout — durable money truth, not per-action IMap
Normal action: local mutate → IMap.set(tableId, snapshot) → broadcast
Game node dies: CP lock → new node IMap.get → hydrate → clients reconnect
oney still flows queue + DB — not per-action cache ledger.
Dedicated six-member grid. Game / lobby / transaction services are clients only.
Model
What it means
What we did
Embedded
Each game JVM is also a Hazelcast member
No — different scale lifecycles
Client → remote cluster
Game services are HZ clients; grid is dedicated
Yes — our model
[ Game node A — active writer ]  ──client──┐
[ Game node B — failover target ] ──client──┼──►  [ Hazelcast cluster ]
[ Lobby service ]                ──client──┘         game state IMap (sync backup)
                                                    routing IMap, CP locks
Why remote cluster: scale game fleet independently; blast radius; tune sync backup on grid nodes; game JVM churn does not reshape partitions.
Jobs we gave Hazelcast
Job
Why Hazelcast (remote cluster)
Replicated game state (IMap)
Every state-changing action → snapshot to IMap with sync backup; new game node loads table if pinned node dies
Table → node routing
Central IMap; all services know where each table lives
Ownership on failover
CP subsystem + fencing — only one node may resume the table
Soft metadata
Presence, session hints — rebuildable; async OK
CAP justification: losing a live money table mid-hand, or two nodes serving different pots, is unacceptable → sync backup on game-state `IMap`, CP + fencing on failover.
What we did not do: two writers without fencing wallet ledger in HZ async-only zero-backup on game-state maps.
Redis: leaderboards (AP-leaning)
Job
Why Redis
Global / seasonal leaderboards
ZSET — score-ordered ranks, top-N in one structure
High read volume
Simple, fast, operationally familiar
Ranking display
Product tolerates seconds of staleness across replicas
Leaderboards are AP-friendly: show rank #6 when true rank just became #5 beats an empty board. Redis ZSET, high reads, replica lag OK for display.
What we did not do: Redis as sole payout source; linearizable global #1 on every read full match simulation in Redis.
Workload
CAP preference
Choice
Why
Live table / pot / turn
Strong C per match
Game node + HZ IMap
Local active writer; replicate snapshot to sync-backed IMap for failover
Table → node routing
C on failover
Hazelcast
Sync backup on dedicated HZ members; game nodes are clients
Ownership after node death
CP (no split-brain)
Hazelcast CP
One successor; fence old owner
Buy-in / payout handoff
Durable, ordered
Queue + DB
Not cache-as-ledger; gameplay stays off money path
Leaderboard / ranking
A over strict C
Redis
ZSET top-N; brief staleness OK; high read QPS
Presence / soft hints
Eventual OK
HZ async or TTL
Rebuildable; not money truth
When things fail
Game node goes down
1. Pinned node dies mid-match
2. One successor acquires CP lock (fences old node)
3. ‘IMap.get(tableId)` → rebuild local state
4. Routing updated → players reconnect
5. Resume or void by product rules
CAP: C on failover — we paid sync replication during play.
Hazelcast grid member goes down
1. HZ member loss → backup promotes → short rebalance
2. Game clients retry `get`/`set`
3. Replicated game state survives on promoted copy
Avoid: state living only in one JVM with no recoverable `IMap` copy.
Anti-patterns
One cache for everything — CAP differs by workload
Redis Redlock for table ownership — we used Hazelcast CP + pinned node
Hazelcast for every leaderboard — Redis ZSET won for AP serving
Async / zero-backup on game-state `IMap`
Strong consistency everywhere — unnecessary for presence and ranks
Wrapping-Up
Hazelcast and Redis — not vs.
Hazelcast — remote cluster: replicated game state in `IMap`(sync backup), routing, CP on failover. Active writer on pinned node; recoverable copy on the grid.
Redis — leaderboards: available top-N, briefly stale OK.
CAP: pick C or A per workload. Architecture: design, prototype, name tradeoffs. Sync backup costs latency — we paid it where failure consistency mattered. Replica lag costs perfect ranks — we paid it where availability mattered.
Draw the workload on CAP first. Then place Hazelcast, Redis, and the game server.
if your platform debates “Hazelcast or Redis” as one winner — what workload would you map first?
Mama, you work on games, right? How would you design Call of Duty and PUBG–kind of games?”
(In our family I am Mama— uncle.)
He expected a short answer — maps, guns, graphics, maybe a cool explosion.
I almost said “it’s complicated.” Then I realized he had asked the right question for an architect not how the game looks, but how the system is arranged so players can find a match, stay in sync, and not melt the servers when a whole country logs in after school.
So I answered him the way I wish more design conversations started — with a map.
Not Erangel. Not Verdansk.
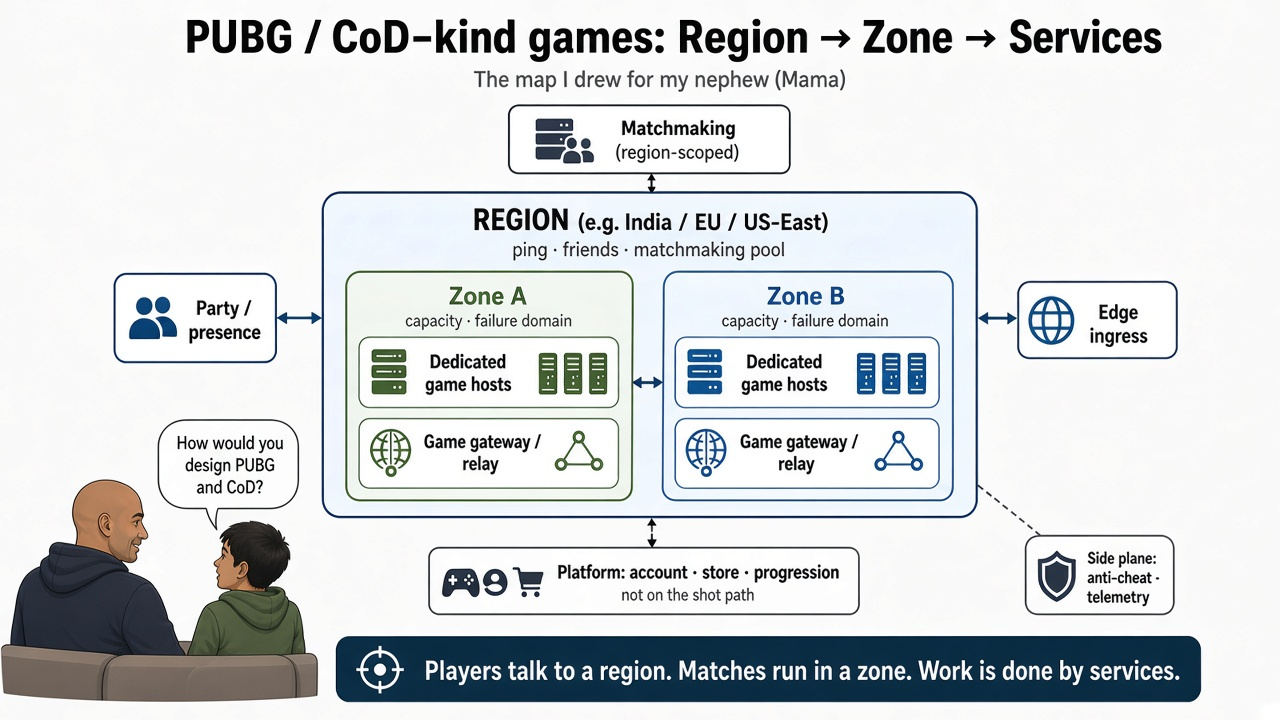
A map of regions, zones, and services.
This article is that answer. It is not a leak of PUBG’s or Activision’s private blueprints. Those backends are not fully public. It is how PUBG-like battle royale and Call of Duty–like multiplayer systems are typically shaped — the same vocabulary we use when we design high-scale live games: where the player lands, where the match runs, and which services do the work.
Draw the map before you name a tool.
Layer
Plain meaning
Design rule
Region
Geography for ping, friends, and often data rules (India, EU, US-East…)
Matchmaking pools and “who can play with whom” are usually region-scoped
Zone
Capacity and failure slice inside a region (AZ / cluster / pod group)
A zone can die without killing the whole region; matches drain carefully
Service
A job the software must do (matchmaking, dedicated game host, store, anti-cheat)
Put each job where latency and ownership demand — not where the slide looks busy
Mama’s rule: Players don’t talk to “PUBG” or “CoD.” They talk to a region. Matches run in a zone. Work is done by services.
If you cannot place a component on that map, you are not designing yet. You are collecting logos.
Naming trap — three different “zones”
Kids (and engineers) mix these up:
1. Cloud / infra zone — failure domain and capacity (this article’s “Zone”)
2. Map / safe zone — the shrinking circle in a battle royale
3. Interest / AOI zone — which other players and objects your client needs to know about right now
Same English word. Three layers. Keep them separate or the design review becomes comedy.
Walk one player from the sofa to the victory screen.
Here is the journey I walked with him — overlaid on the map.
1. Launch / login → hits platform services (identity, entitlement). Often multi-region capable, with a home region.
2. Lobby / party → region-aware presence: you queue with friends who share a sensible ping story.
3. Matchmaking → region-scoped queues (skill, playlist, fill rules). Output: “here is your match” + where to connect.
4. Connect to the match → client is steered to a dedicated game host (or relay path) sitting in a zone inside that region.
5. In match → authoritative simulation ticks; state replication; interest management; voice often match- or region-local.
6. Match end → results hand off to progression / inventory / battle pass (platform path — not on every bullet).
7. Side planes (always on) → anti-cheat signals, telemetry, crash reports — async, must not block the tick.
This is the same shape as systems I have lived with in live gaming
matchmaking as a door (ask and get placed), then a live channel / dedicated path as the room (stay connected for the session). Different genre. Same map logic.
What sits where — service placement.
Service
Typical place on the map
Why
Identity / account
Platform (multi-region or hub + cache)
Shared identity; not every shot
Store / battle pass / inventory
Platform
Money and catalog; after or beside the match
Friends / party / presence
Region-aware
Parties hate cross-ocean ping
Matchmaking
Region
Pool quality + latency
Dedicated game servers / match instances
Zone inside region
Blast radius; capacity; drain on failure
Real-time game gateway / relay
Edge / region
Low latency into the match
Voice
Match- or region-local
Latency and moderation scope
Anti-cheat (client + server signals)
Match-local collect → hub aggregate
Hot path light; intel can be global
Telemetry / analytics
Side plane → lake
Never block the tick
Content / config catalog
Hub + CDN
Versioned rules, maps, playlists
Hot path rule: bullets, movement, and tick authority stay near the player (region / zone). Store, heavy CRM, and batch analytics do not sit on the shot path — same lesson as handing wallet work off a live game loop.
Same map — different match shape (PUBG-like vs CoD-like)
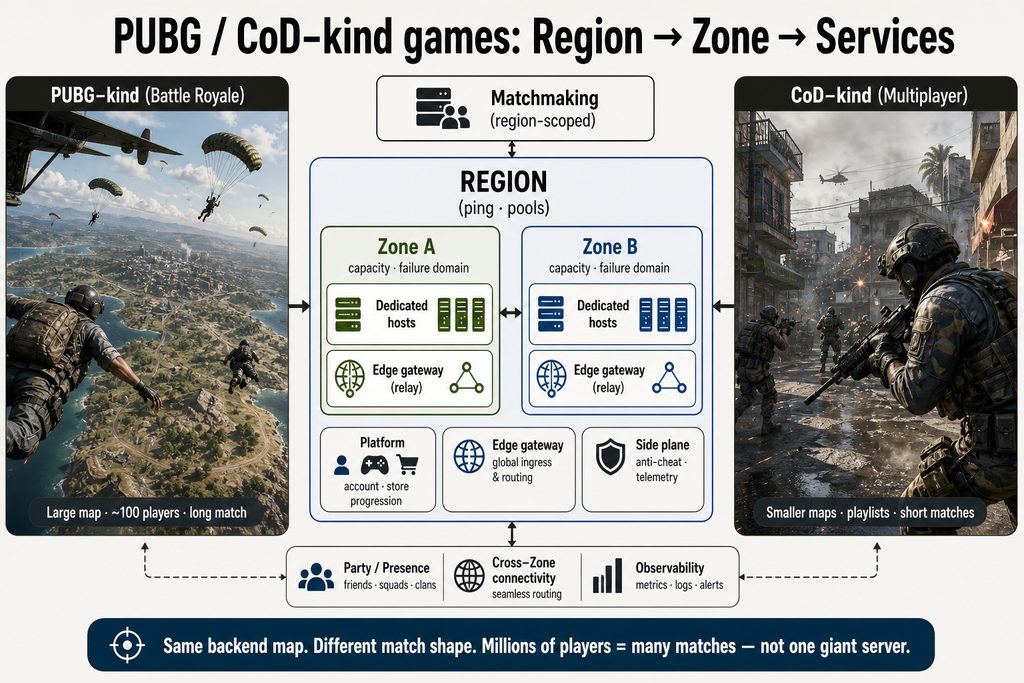
I did not crown a winner. Both sit on Region → Zone → Services. The match they host looks different, so the fleet math changes.
Concern
PUBG-like battle royale
CoD-like multiplayer modes
Match shape
Large map, many players, longer session
Smaller maps, shorter matches, many playlists
Dedicated fleet
Fewer, heavier matches per host
Higher match churn; faster spin-up / teardown
In-match pressure
Wide map + vehicles + loot; strong AOI needed
Tighter spaces; higher tick / precision pressure
Region pressure
Launch and country spikes; fill 80–100 seats
Playlist and seasonal spikes; many small rooms
What stays identical
Region routing, zone isolation, platform vs game split, async side planes
Same
And, not vs: PUBG-kind and CoD-kind games are not rival architectures. They are two workloads on one map.
Region design — what my nephew already understood as “ping”
Ping budget decides who can share a match comfortably.
Party constraints beat “perfect MMR” if the squad cannot hear each other in time.
Empty lobby risk — a region that is too fine-grained never fills; too coarse and someone plays on 180 ms.
Data and policy — some player data and commerce prefer staying in-region.
Spill / overflow— when a region is on fire, you need a written rule (queue, wait, or rare cross-region with honesty about ping).
Region is a product decision as much as a cloud dropdown.
Zone design — why we don’t put every match in one basket
Inside a region, zones exist so that:
Hardware or AZ failure takes some capacity, not all evening matches
You can drain live matches (finish or migrate carefully) instead of hard-killing everyone
You scale dedicated fleets in slices — warm pools, playlist packs, BR vs small-modes packing
If matchmaking returns a host, that host’s zone is part of the placement decision — not an afterthought for Ops.
In-match: who owns the truth
For both genres, the dedicated (or authoritative) simulation owns match truth: positions, damage, win conditions. Clients predict for feel; server corrects for fairness.
That is the same ownership lesson as a live game table :many concerns in flight (inputs, timers, broadcasts), but one clear writer of shared state beats “a thread per player mutating the pot.” Concurrency is required. Chaos is optional.
Interest management (AOI) decides what to send whom — critical on a big BR map, still important in tight CoD lanes. That is game zoning, not your cloud zone.
“One contest, a million players” — how scale actually works
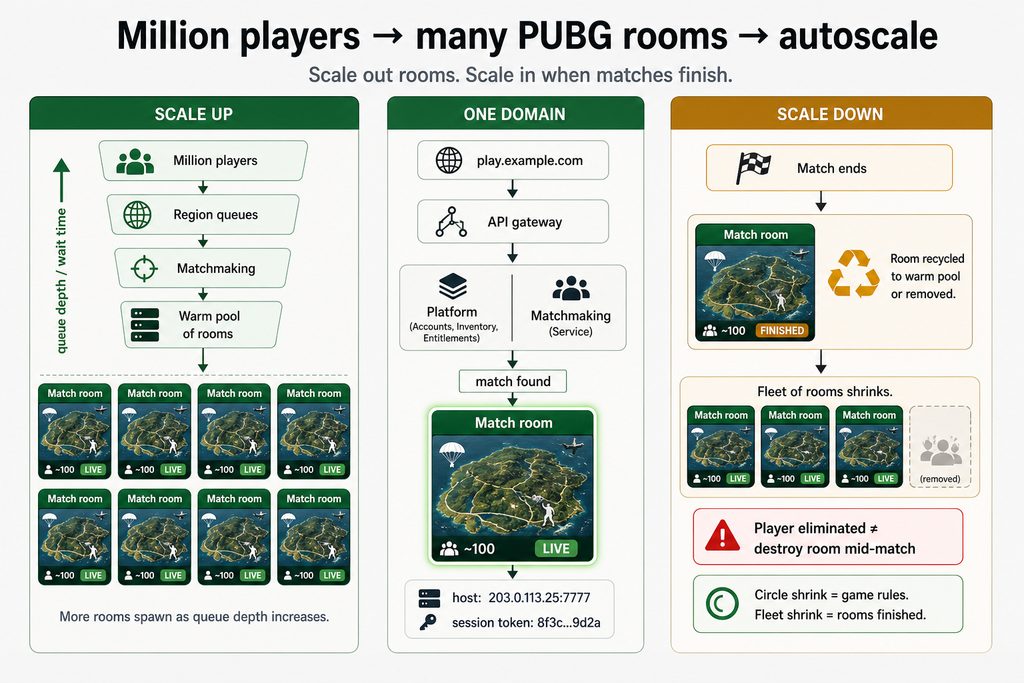
This is the question my nephew asked next: if a big contest has millions of players, do you build one giant server? When people die, do servers shrink? How does one website send everyone to the right place?
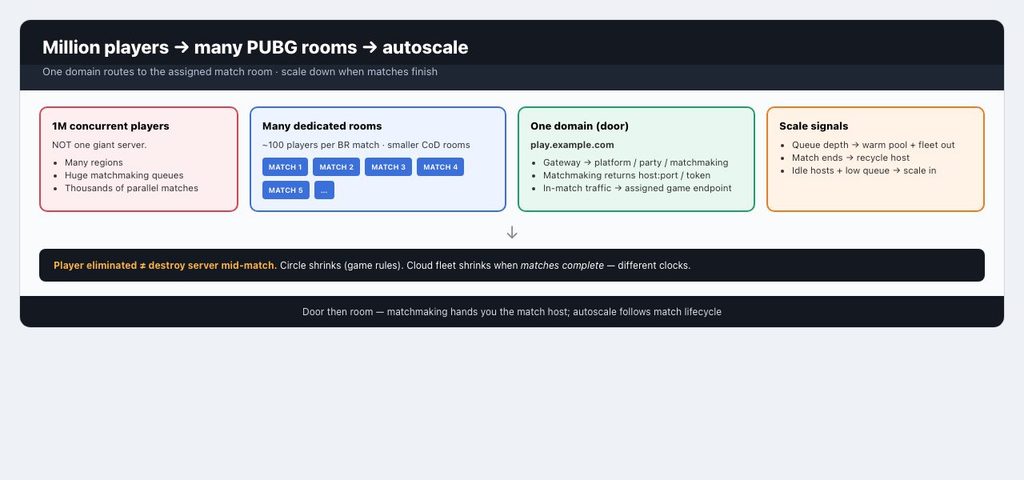
First correction — millions are not one match
A PUBG-like battle royale match is on the order of 100 players (squads fill seats). A CoD-like mode is often fewer per room.
A million concurrent players means roughly:
many regions taking traffic
huge matchmaking queues
thousands / tens of thousands of matches in parallel
each match on a dedicated host (or a packed host running N matches) inside a zone
So the platform scales by creating many small rooms, not by stuffing a million people into one simulation. One match still has one authoritative world. Parallelism across the system is many matches at once the same idea as many live tables running together.
Scale up — when the lobby catches fire
Autoscaling is driven by signals, not vibes:
Signal
What scales up
Login / store spike
Platform pods / gateway capacity
Queue depth / wait time
Matchmaking workers + dedicated game fleet
Assigned matches with no free host
Warm pool → cold start more game servers in the zone
Telemetry / anti-cheat volume
Side-plane consumers (async)
Typical dedicated-fleet pattern:
1. Keep a warm pool of ready game hosts per region/zone (already loaded build, waiting).
2. Matchmaking fills a lobby → allocates a host (or a match slot on a packed host) → returns connection info to clients.
3. If warm pool is empty and queue is deep → scale out more hosts (VM/container/bare metal — product choice).
4. Cap scale with max so a bug cannot bankrupt you; spill to “queue longer” rather than infinite machines.
Platform and matchmaking scale on HTTP/API metrics. The game fleet scales on matches needing a home.
Scale down — when the game finishes (not when one player dies)
When a match ends:
1. Dedicated host writes results → hands off to progression / rewards (platform).
2. Players disconnect from that match path.
3. Host is recycled (back to warm pool) or terminated if pool is fat.
4. Autoscaler watches idle hosts + queue depth → scale in slowly (hysteresis), so a two-minute lull does not thrash.
Important: when players are eliminated mid-match (“next circle, fewer alive”), you usually do not tear down or resize away the dedicated server. The match is still live until a winner (or draw) is declared. What can drop is work inside the match:
fewer clients to replicate to
lighter AOI / bandwidth
fewer voice peers
The map safe zone shrinks (game rules). The cloud zone fleet shrinks when matches complete and demand falls — different clocks.
Eliminated players often return to lobby / spectate / platform that traffic moves back to lobby and platform services, while the match host keeps serving survivors.
One domain — how everyone reaches the right service
Players remember one name: `play.example.com` or the game client’s embedded API host. Behind that single domain:
Client
  → DNS (often geo / latency aware) → regional edge
    → API gateway / load balancer
         ├─ /auth /store /profile     → Platform services
         ├─ /party /presence          → Region-aware social
         ├─ /matchmaking              → Matchmaking
         └─ after “match found”
              → dedicated host or game gateway
                 (host:port / token / session from matchmaking — not the store URL)
(host:port / token / session from matchmaking — not the store URL)
So:
One public front door (domain + gateway) for lobby and platform.
Matchmaking is the redirector in product terms— it tells the client which game service/host owns this match.
In-match traffic often goes straight to the assigned game endpoint (UDP/dedicated), not through the store cluster.
Sticky cookies / tokens / session tickets bind “this player → this match host” for the life of the session.
That is the same door then room idea: REST (or similar) to get placed; persistent/realtime path to play.
What “services change” as the match levels up
Moment
What changes
Queuing
Matchmaking + platform busy; game fleet warming
Match start
One host owns that match; clients leave matchmaking hot path
Players eliminated / circle shrinks
Game rules + AOI load change; dedicated host stays
Match over
Host frees; progression spikes briefly; fleet can scale down
Contest evening ends
Queue collapses → scale in matchmaking and game fleet toward baseline
Services do not randomly morph mid-bullet. Ownership moves along the journey: platform → matchmaking → dedicated match → platform again. Autoscaling follows which layer is busy, match by match, region by region.
What not to put on the map’s hot path
Charging a card on every elimination
Synchronous “call the data warehouse” mid-fight
Treating matchmaking REST polls as the game loop
One global region “because simpler”
One mega-zone “because Kubernetes”
Draw the map. Then pick UDP, dedicated hosts, queues, and stores into the boxes — not instead of the boxes.
Wrapping-Up
My nephew wanted guns and maps. I gave him regions, zones, and services.
Region— where the player belongs for ping and pools.
Zone — where this match’s capacity and failure story live.
Services— the jobs: platform, matchmaking, dedicated simulation, edge, side planes.
PUBG-kind and Call of Duty–kind games share that map. They differ in match shape and fleet churn, not in inventing a different physics of distributed systems.
Mama’s rule: draw the map before you name the tool.
Mama’s second rule: a million players means many matches and an autoscaler with a warm pool — not one infinite server that shrinks every time someone is eliminated.
When someone asks how you would “design PUBG or CoD,” start with: Which region? Which zone? Which service owns this moment in the player’s journey? Then ask: What signal scales that service up — and what event lets it scale down?
One honest caveat: this design is my assumption — a teaching map from how large multiplayer backends are typically shaped, and from patterns I have used in live gaming. It may not be the exact architecture the owners of PUBG or Call of Duty run in production. Their real systems will differ in topology, naming, vendors, and secrets we do not see. Use the map to think; do not treat it as a reverse-engineered blueprint.
How our game server evolved from a monolith to micro game servers
When I started my career at an Indian gaming startup called a23.com, I had no idea I was about to get a front-row seat to one of the hardest problems in online gaming: scale.
I joined a small team – just me, my CEO, and a mentor who doubled as my manager – and I was handed the backend. My job was to build the game server – the piece that keeps everyone in a match synchronized, fair, and connected. In the early days, “scale” meant something modest. We were happy to serve 20 to 100 concurrent players without things falling over.
In the beginning: one socket server to do everything
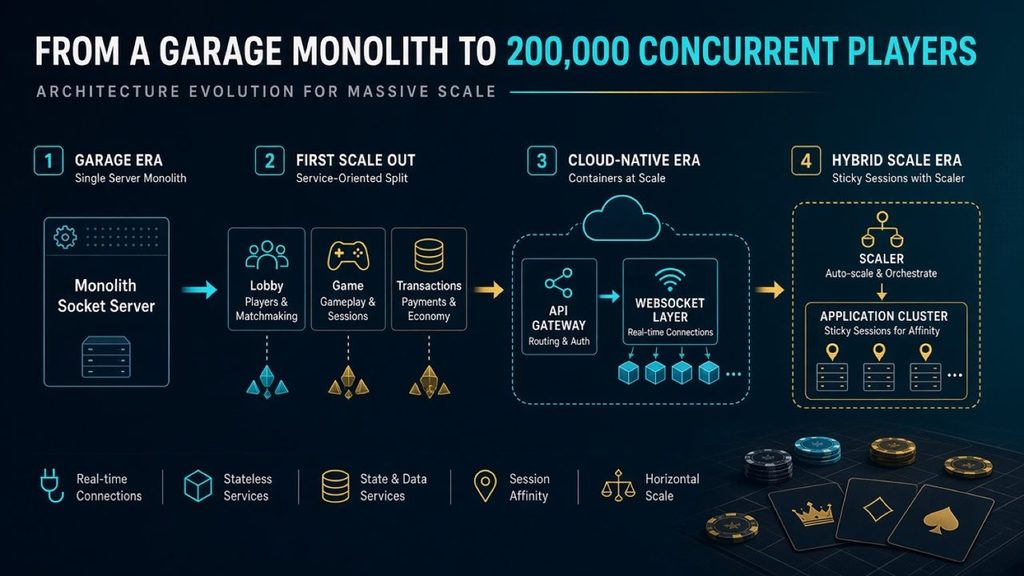
We started simple. The whole backend was a single socket server, and it did almost everything.
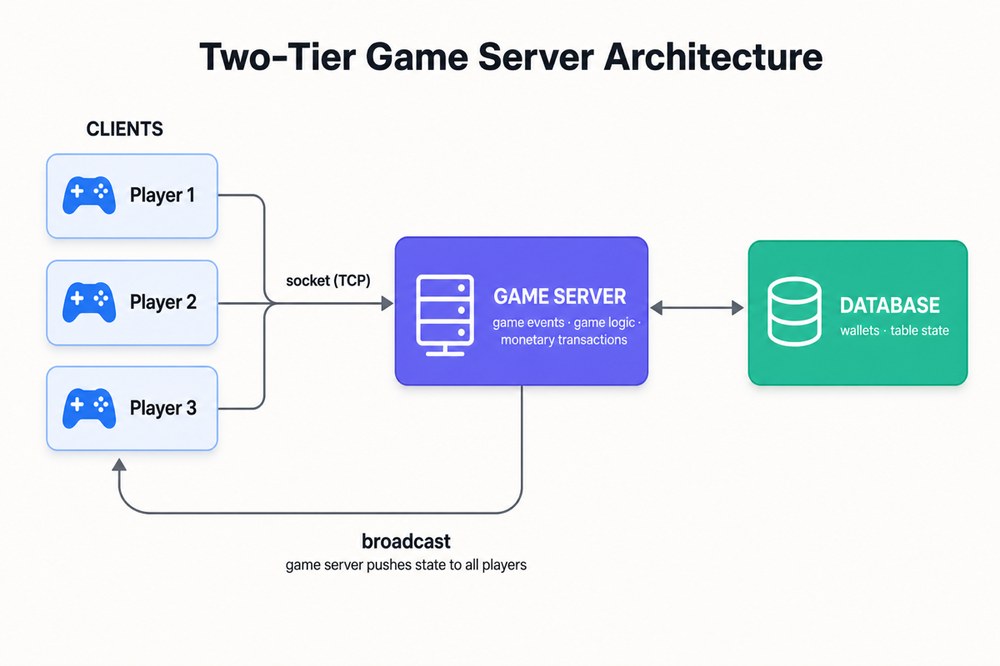
Clients didn’t talk to a web API or a queue — they opened a persistent socket connection straight to the game server and stayed connected for the life of the session. That one server carried the entire weight of the game:
Game events — every move, deal, and turn at the table.
Monetary transactions — wallets, buy-ins, and payouts, all real money.
State and broadcasting— keeping every player at a table in sync.
The loop was beautifully straightforward. A client would send an input over its socket. The server would receive it, process the game logic, update the table state, and broadcast the result to every player seated at that table. Take input, compute, fan out — that was the heartbeat of the whole game.
It was a classic two-tier architecture — clients on one side, a single game server (with its database) on the other
For 20 to 100 players, this was perfect. One process, one connection per player, one place to reason about everything. We could hold the entire system in our heads.
That simplicity was exactly what would later break.
The smartphone wave: when traffic stopped being polite
Around 2010, the ground shifted under us.
Smartphones were suddenly everywhere, and cheap, fast mobile internet — 3G, then 4G — put a gaming client in everyone’s pocket. People who’d never owned a PC were now playing on the bus, in queues, on their lunch break. For the business, this was a dream. For our backend, it was a flood.
Traffic didn’t grow politely. It surged. And our single monolithic server, the one we used to hold entirely in our heads, started to strain. It could still work — but “perfectly” was off the table. One process trying to do game events, money, and broadcasting for an ever-growing crowd was a bottleneck waiting to happen.
We weren’t just trying to survive today’s load. We were getting ready for 10x the traffic.
Step 1: Split the monolith by responsibility
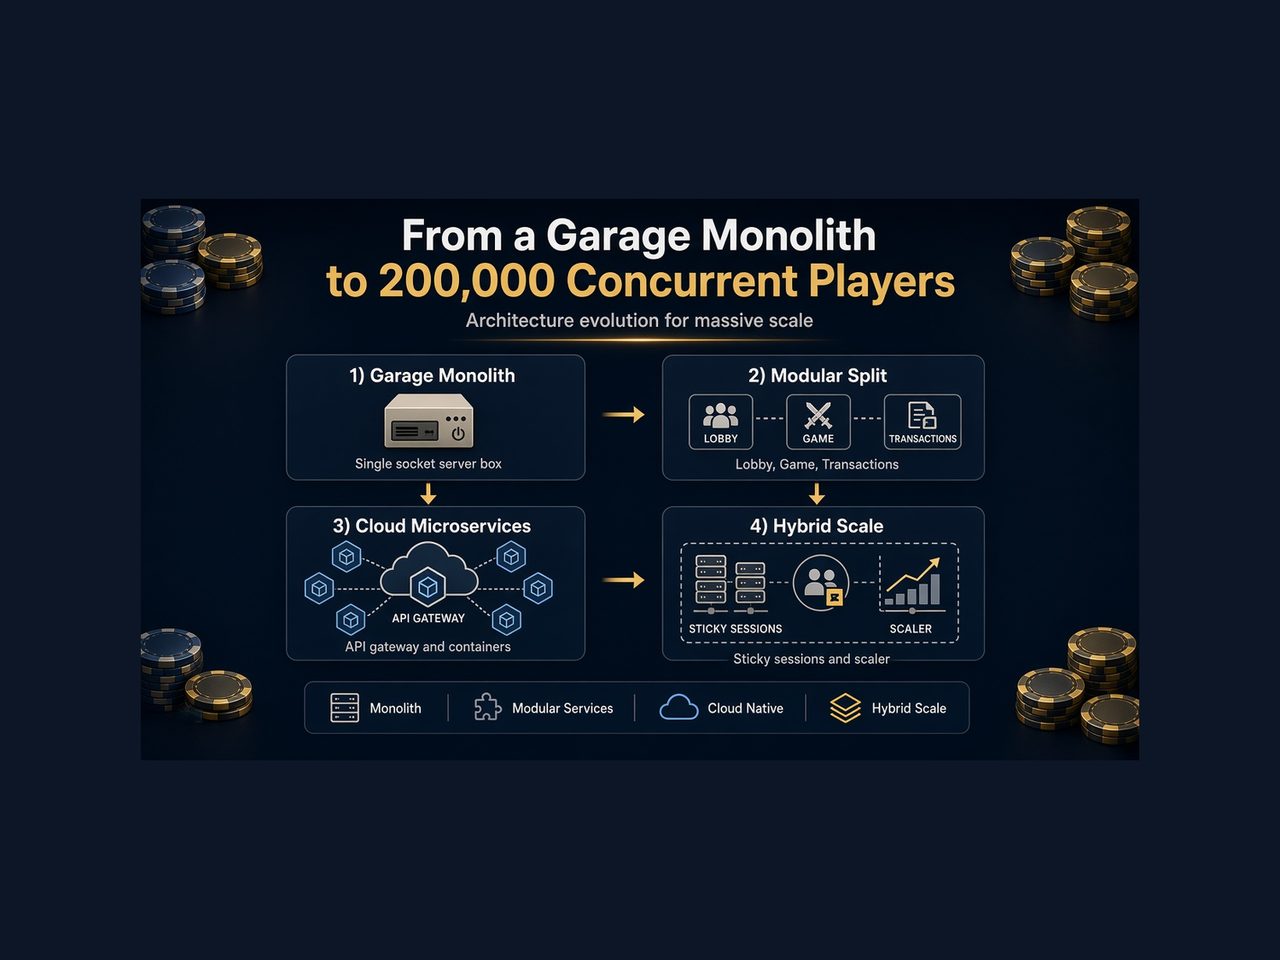
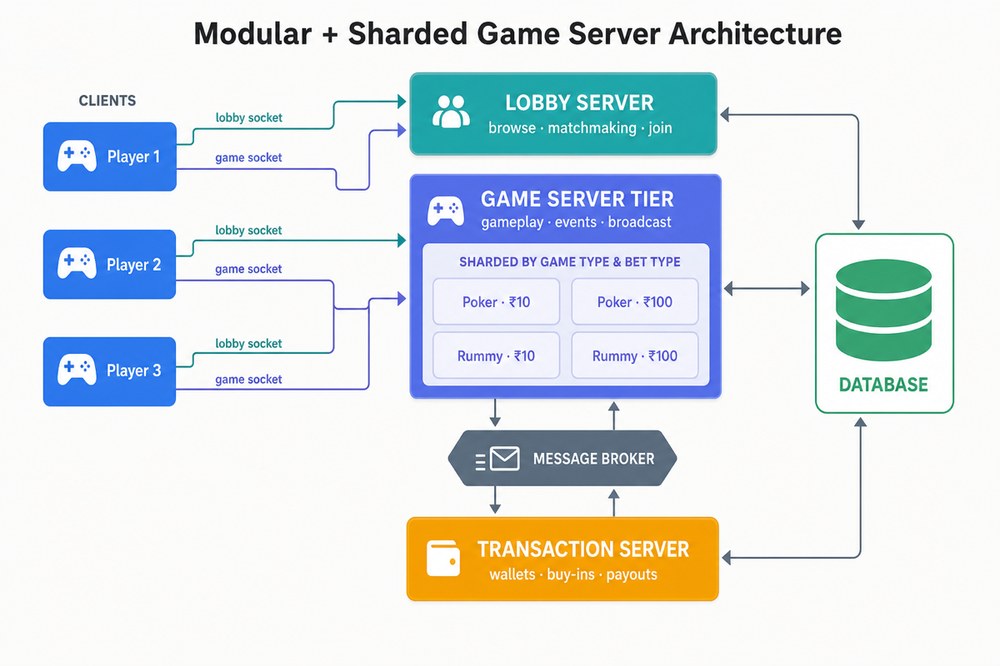
The first move was to stop making one server do everything. We broke the monolith into modular servers, separated by domain— each one owning a clear slice of the system:
Lobby server — players browsing, joining, and matchmaking into tables.
Game server — the actual gameplay: events, table state, broadcasting.
Transaction server— wallets, buy-ins, payouts, and everything money.
Crucially, there was no single gateway in front of these. The client connected to each service directly: one socket to the lobby server for browsing and matchmaking, and a separate socket to the game server once it sat down at a table. Two independent connections, each to the service that owned that part of the experience.
The transaction server sat slightly apart. Instead of talking to it over a direct socket, the game server and transaction server communicated through a message broker. When money needed to move — a buy-in, a payout — the game server published a message and let the broker carry it to the transaction server, rather than blocking gameplay on a synchronous call. This kept the money path decoupled and reliable even if transactions queued up under load, the game kept running.
Now a spike in people browsing the lobby couldn’t drag down a live game, and a heavy moment in gameplay didn’t put financial transactions at risk. Each concern could scale — and fail — on its own.
Step 2: Shard the game servers
Splitting by responsibility bought us room, but a single game-server tier still couldn’t hold all the live tables at scale. So we sharded it.
Instead of one game server for everything, we ran many — and assigned each shard by game type and bet type. A specific game at a specific stake had its own dedicated game servers. Players were routed to the right shard for the table they wanted to play.
Sharding gave us two things we badly needed: horizontal scale (just add more game servers for the hottest game/bet combinations) and isolation (a problem on one shard didn’t ripple across the whole platform).
From garage startup to enterprise: the move to microservices
By 2020, the company I’d joined in a garage wasn’t a startup anymore. It had grown into a full enterprise gaming company. We’d added game after game, and the player base had exploded to 80 million registered players, with up to 200,000 (2 lakh) concurrent players at peak.
Our modular, sharded setup had carried us a long way but the rules of the game had changed again, and this time the pressure came from two directions at once:
Management wanted to optimize infrastructure cost. Running fleets of always-on servers sized for peak traffic meant paying for capacity we didn’t use most of the day.
The business wanted on-demand scaling without manual intervention. When a tournament or a festival spike hit at midnight, no one should have to wake up and spin up servers by hand.
Meanwhile, cloud computing had matured. What used to mean racking our own machines could now be rented, automated, and scaled by API. The timing was right to rethink the foundation.
So we made the leap: containerization with Docker, on a major cloud provider, and a full move to microservice architecture.
Each piece of the system lobby, game shards, transactions, and everything that had grown around them — became an independent, containerized service. That shift gave us the three properties an enterprise platform at this scale can’t live without:
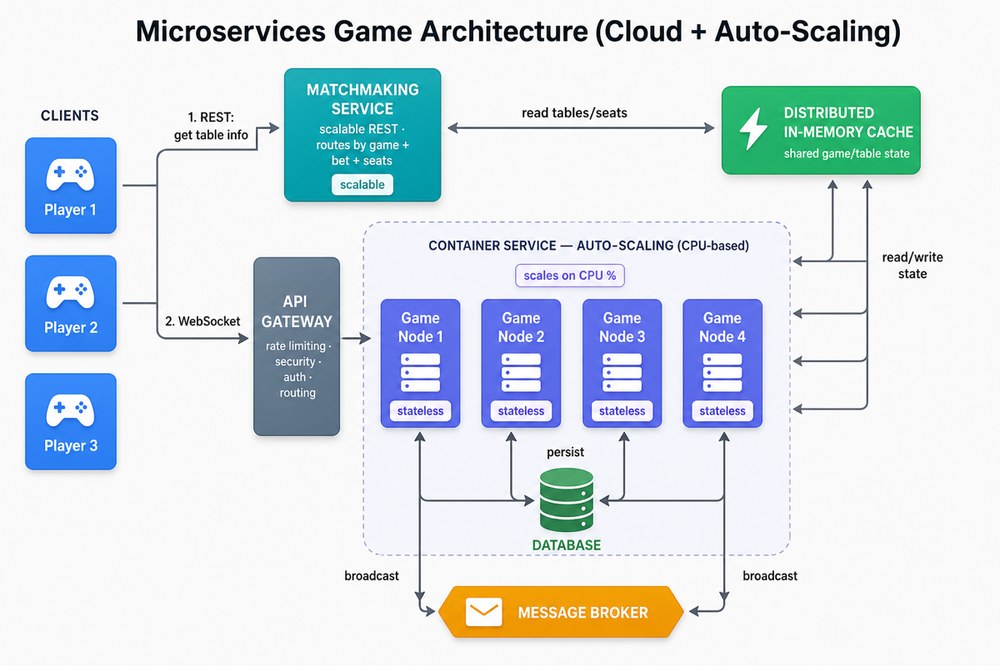
Auto-scaling — services scale up when traffic surges and scale back down when it fades, so we pay for what we actually use. We drove this with CPU-based scaling when a service’s CPU utilization crossed a threshold, the platform automatically added more containers, and removed them again once load eased.
Fault tolerance — if one container dies, it’s automatically replaced; a single failure no longer takes down the experience.
High availability — the platform stays up through deploys, spikes, and hardware hiccups, because no single instance is a point of failure.
This was the moment our “game server” stopped being a server at all. It became a living fleet of micro game servers — spinning up and winding down on their own, healing themselves, and absorbing 200,000 concurrent players as a matter of routine rather than a fire drill.
Step 1: Make the game engine stateless
Auto-scaling sounds great until you ask the hard question: if any container can be killed and replaced at any moment, where does the game state live?
In the old world, a game server held the table state in its own memory. That’s fine when a player is pinned to one server for the whole session — but it’s fatal for auto-scaling. If that one instance dies, the table dies with it. And you can’t freely add or remove nodes if each one is the only place its tables exist.
So the first and most important move was to separate game state from the game engine.
We pulled table state out of the engine’s local memory and into a distributed in-memory cache. State now lived in a fast, shared layer that every game node could read and write — not locked inside a single process.
With state externalized, the game engine itself became stateless.Any game node could now serve any player: it would simply pull the current table state from the cache, apply the move, write it back, and broadcast the update through the message broker to everyone at the table.
That one change unlocked everything else. Because no node “owned” a table anymore, we could add nodes, kill nodes, and reschedule containers freely— exactly what auto-scaling and fault tolerance require.
On top of that, we added a few more pieces to complete the picture:
A matchmaking service — a scalable REST service that the client calls first. Based on matchmaking rules (game type, bet type, seats available, and so on), it picks the right table and returns the game table info to the client. It reads the live picture of tables and seats from the cache to make that decision. Only after this does the client know where to play.
WebSockets for clients— we upgraded the client connections from raw sockets to WebSockets, a better fit for a modern, containerized, cloud-fronted platform.
An API gateway in front of the WebSockets — clients now connect through an API gateway rather than straight to a node. That let us lean on gateway features we’d otherwise have to build ourselves: rate limiting, security, authentication, and routing.
Game engines on a container service — the engine ran as containers on the cloud’s container platform, ready to be scaled and replaced on demand.
Put together, the flow became beautifully elastic. A player first calls the matchmaking REST service, which looks at the available tables in the cache and hands back the game table info. Armed with that, the client opens a WebSocket to the game services for that table, and any available game node can serve them — reading and writing state in the cache, persisting to the database, and fanning out updates through the broker. No node is special. No node is irreplaceable.
Step 2: The hybrid stateful redesign
The stateless design was elegant — but at our peak, elegance got expensive.
At full load we were processing roughly 300,000 (3 lakh) concurrent game events. Because the engine was fully stateless, every one of those events meant a round-trip to the cache and a broadcast through the message broker — and since players at the same table could land on different nodes, nodes had to chatter with each other to stay in sync. Two things started to hurt:
The message broker was spiking, straining under the sheer volume of events flowing through it.
The game engine burned resources on inter-node communication, coordinating state that lived everywhere and nowhere.
Pure statelessness, it turned out, had a cost of its own. So we went looking for a middle path – a hybrid design that kept the operational benefits of microservices but stopped paying the per-event tax.
The core idea: pin one game to one node.
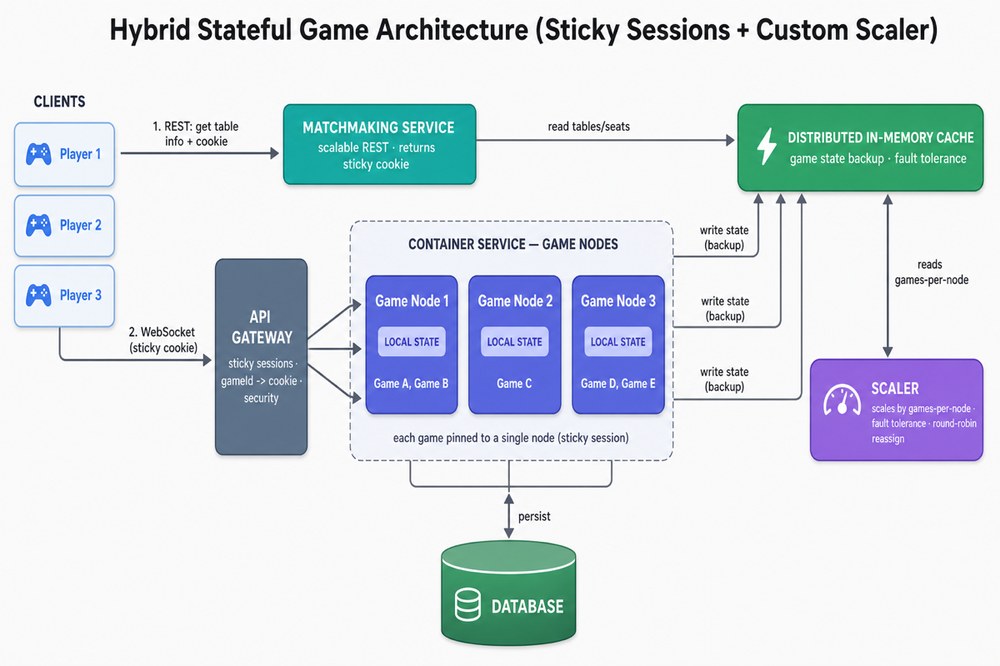
One game, one node. Each game runs entirely on a single game node, which keeps that game’s state in local memory.Gameplay reads and writes happen in-process — no cache round-trip, no cross-node coordination, per move.
Sticky sessions via the API gateway. We map each `gameId` to a gateway cookie, creating a sticky session that always routes a given game on a given node. One sticky session = one game on one node.
Matchmaking hands out the cookie. When the matchmaking service places a player at a table, it returns the cookie along with the table info. The client uses that cookie to connect — through the API gateway — to the same node hosting that game table, every time.
Because all the players of a table now share one node, the engine can use local state for live gameplay. That single change let us dramatically cut message-broker traffic and game-server resource usage the inter-node chatter and constant broadcasting largely went away.
But we didn’t abandon the cache. We still write game state to the distributed cache in the background. Local memory makes gameplay fast; the cache is our safety net – it’s what makes the system fault tolerant, because a game’s state can be recovered even if the node holding it disappears.
A custom scaler service
There was one more problem: CPU is the wrong signal for this workload.A node hosting many low-activity tables and a node hosting a few intense ones can show similar CPU, even though their real load — number of games — is very different. So we dropped CPU-based scaling and built our own.
We added a dedicated Scaler service that owns both scaling and fault tolerance, driven by a metric that actually matters for us: the number of games per node.
Scaling. Game nodes scale out and in based on how many games each node is hosting, not CPU. When games-per-node climbs past our threshold, the scaler adds nodes; when it falls, it removes them.
Fault tolerance. When a node crashes, the scaler spins up a replacement and redistributes the failed node’s games across the remaining nodes in round-robin — rehydrating each game’s state from the cache. Players are reconnected to a healthy node, and play continues.
This hybrid model gave us the best of both worlds: the speed of local state for 300,000 concurrent events, and the resilience and elasticity of microservices for 200,000 concurrent players —without melting the message broker in the process.
Wrapping up: what a decade of scaling taught me
When I look back at the journey — from a single socket server in a garage to a self-healing fleet of micro game servers serving 200,000 concurrent players — the most striking thing isn’t any one piece of technology. It’s that every stage was the right answer for its moment, and the wrong answer for the next one.
A few lessons stuck with me:
Start simple. Embarrassingly simple.That one monolithic socket server was the right call at 100 players. If we’d begun with microservices, sharding, and a custom scaler, we’d have drowned in complexity before we ever shipped. Architecture should match the problem you have, not the one you imagine.
Scale arrives because of the business, not the tech. Every rewrite was triggered by something outside engineering — smartphones, cheap data, 80 million users, a finance team watching the cloud bill. The best architecture decisions came from listening to where the business was heading.
Split by responsibility before you split by scale. Breaking the monolith into lobby, game, and transaction services bought us clarity and isolation long before sharding bought us raw throughput.
There is no “correct” answer on state. We went stateless to unlock auto-scaling, then deliberately walked back toward local state when statelessness got too expensive. Stateless vs. stateful isn’t a religion — it’s a trade-off you re-evaluate as load changes.
Measure what actually matters. CPU looked like a scaling signal until it lied to us. Switching to games-per-node a metric tied to real load made scaling and fault tolerance finally behave.
Decoupling is what lets you sleep. Message brokers, caches, sticky sessions, a dedicated scaler almost every hard-won improvement was really about making one part of the system fail without taking the rest down with it.
If you’re early in your own scaling journey, don’t try to leap straight to the final diagram. Build the thing that works today, watch where it hurts, and let the pain point you to the next architecture.That’s not a failure of planning — that’s how systems that handle hundreds of thousands of players actually get built.
We didn’t design our way to 200,000 concurrent players in one shot. We evolved there, one bottleneck at a time.