Category: System Design

  • Every Architecture Decision You Skip Recording, You Pay For Twice

    What missing ADRs cost when you build a Dynamic Real-Time Query Engine — not Slack archaeology

    When a new requirement lands, we open the Architecture Review Board (ARB).

    Someone says “buy another CRM tool.” Someone says batch is fine. Someone says “we already decided this.” Nobody can find where.

    That is not a tooling problem. It is a memory problem — and on a live gaming platform, forgotten decisions become production incidents, re-opened fights, and sprints that undo last year’s work.

    Architecture Decision Records (ADRs) are how you stop paying twice. Not bureaucracy. Insurance.

    This article is not “what is an ADR” from a textbook. It is a consequence map: decisions we made on a real gaming platform — Dynamic Real-Time Query Engine for CRM and ML, lobby and live tables, wallets, caches, fraud on the hot path — and what broke when we did not record them (or recorded them in Slack and lost them).
    ADR in one sentence (before the horror stories)

    An ADR is a short, durable note: what we decided, why, what we rejected, and what we will revisit. It lives in the repo or architecture wiki — not in a thread that scrolls away.

    You do not need one ADR per line of code. You need one per decision that will be fought again if nobody wrote it down.

    The decisions that deserved an ADR (gaming platform)

    On our platform, these were not “nice to have.” They were forks in the road:

    DecisionWhy it mattered
    RTQE as platform, not CRM patch (Cassandra + JSON DSL + shared API)Millisecond behavioral queries for CRM and ML — one live truth
    JSON DSL vs open SQL on RTQECRM self-serve segments without unbounded queries
    REST for lobby, WebSocket for live playDoor vs room — different conversation shapes
    Hazelcast for table state, Redis for leaderboardsCAP — coordination vs eventually-fresh reads
    One writer per ledgerNo duplicate wallet paths during strangler migration
    Fail-open vs fail-closed on fraudBlock play vs allow play when the engine is down
    Reuse Spark / buy EMR vs build segmentationCost and ownership on offline compute
    Strangler order: transactions before lobby splitPlateau sequence — not big-bang weekend

    Each of these showed up in ARB, stand-up, or a new squad’s first design doc. When we missed recording one, we paid a predictable price.

    If you miss the ADR — consequences (with examples)

    1. Dynamic Real-Time Query Engine — “let’s bolt another tool onto CRM”

    Decision: Build the Dynamic Real-Time Query Engine (RTQE) as shared platform infrastructure — not a one-team patch. Cassandra time-series (one table per event type), JSON DSL for behavioral segments, REST APIs for CRM, targeting, and the ML Service — millisecond queries while the player is still on screen.

    If you skip the ADR:

    CRM buys or builds a narrow segmentation tool; ML spins up a second live-events pipeline.

    Consequence: duplicate stores, segments that lag live play, engineering tickets for every new behavioral question — “real-time” becomes tomorrow’s batch.

    Symptom in prod: offer fires after the player left the table; CRM and ML disagree on the same player’s last hour.

    What the ADR should have said: Platform not patch. One engine, many consumers. Bounded JSON DSL — not open SQL. Cassandra model: player_id partition, time-series clustering, one table per event type.

    2. RTQE query model — “just expose SQL to CRM”

    Decision: JSON DSL with bounded query models (aggregates, time windows, expressions) — every query maps to a single-partition, time-bounded Cassandra read. Not open SQL to marketing tools.

    If you skip the ADR:

    Someone exposes read-only SQL “for flexibility.”

    Consequence: unbounded scans, hot partitions, on-call pages during a campaign launch — CRM “self-serve” becomes production roulette.

    Symptom in prod: segment job takes 30 seconds; player already churned; CRM blames “the real-time engine.”

    What the ADR should have said: DSL not SQL. Query bounds by construction. `searchTime` aligns with time-series clustering key.

    # ADR-001: Dynamic Real-Time Query Engine as shared platform (not CRM patch)
    
    Status: Accepted  
    Date: 02/15/2025
    Deciders: Architecture Board, CRM, Data Platform, ML, VP Engineering  
    
    Context
    
    CRM and marketing needed to understand live player behavior and act while the player is still on screen  not via nightly batch jobs. Existing CRM tools could not answer behavioral questions in milliseconds. The easy path was another point solution on the CRM stack; the harder path was shared platform infrastructure.
    
     Decision
    
    Build the Dynamic Real-Time Query Engine (RTQE) as a foundational building block:
    
     Apache Cassandra — one table per event type, time-series keyed by `player_id` + event timestamp
     JSON DSL — bounded behavioral queries (aggregates, time windows, expressions) — not open SQL
    Event ingest pipeline — decoupled producers into the engine (point-to-point queues)
     Java 21 + Spring Boot — REST APIs for CRM, targeting, and ML Service consumers
    Platform scope — same engine serves multiple consumers — not a single-team patch
    
    Consequences
    
    Positive: Millisecond segments on live play; CRM self-serve in JSON; ML gets real-time features from one pipeline; ~100K req/s headroom with virtual threads and horizontal scale.
    
    Negative: Custom DSL to maintain; Cassandra modeling discipline required; platform team owns SLAs for all consumers.
    
    Obligations: Query bounds by construction; one-table-per-event-type schema governance; document rejected “SQL over everything” and “CRM-only tool” paths.
    | Alternative | Why rejected |
    |-------------|--------------|
    | Bolt-on CRM segmentation tool | Solves one team;  duplicate pipelines for ML; batch mindset |
    | Expose raw SQL to CRM | Unbounded queries; safety and ops risk on hot path |
    | Single generic events table | Partition and query unpredictability; fights Cassandra strengths |
    | Nightly batch only | Misses the conversion window — player already left |


    3. REST lobby + WebSocket game — “let’s poll matchmaking from the socket”

    Decision: REST (or HTTP API) to Lobby — find and join a table. WebSocket to Game — live play, broadcast state.

    If you skip the ADR:

    Mobile team polls lobby state over the game socket every 500ms for simplicity.

    Consequence: socket fan-out load explodes; matchmaking logic bleeds into game shards; you cannot scale browse traffic separately from seated players.

    Symptom in prod: lobby spike during a tournament drags down live tables — the failure domain you split on purpose.

    What the ADR should have said:Door = REST. Room = WebSocket. Do not merge because one client library is easier.

    # ADR-002: REST for lobby (door), WebSocket for game (room)
    
    Status: Accepted  
    Date: Migration Plateau 2  
    Deciders: Mobile, Lobby, Game squads, ARB  
    
    Context
    
    Matchmaking is request/response: find table, seat player, return connection info. Live play is a long-lived session: broadcast state, play events, timers. Mixing both on one channel couples browse traffic to seated-player scale.
    
    ## Decision
    
    REST (HTTP API) to Lobby Service for matchmaking, presence, seat assignment.
    - WebSocket to Game Service for live table play after seat confirmed.
    - Session handoff: lobby returns game shard / token; client opens socket to game fleet.
    
    ## Consequences
    
    Positive: Scale lobby on browse traffic independently; clear failure domains; matches client mental model (door vs room).
    
    Negative: Two client integrations; handoff bugs if token/session contract drifts.
    
    Obligations: Document handoff flow in API spec; integration tests for seat → connect path.
    
     Alternatives considered
    
    | Alternative | Why rejected |
    |-------------|--------------|
    | WebSocket for lobby polling | Fan-out and unnecessary persistent connections for short requests |
    | REST for live play | Polling latency unacceptable for table state; wrong conversation shape |
    | Single monolith socket | Failure domain and scale coupling we were leaving |
    

    4. Hazelcast vs Redis — the annual CAP debate

    Decision: Hazelcast (remote cluster, sync backup, CP locks) for recoverable table state when a game node dies. Redis (cluster) for leaderboards where slightly stale ranks are acceptable.

    If you skip the ADR:

    Every new hire proposes Redis for everything or Hazelcast for “leaderboards too.”

    Consequence: quarters lost to benchmarks and slide decks; wrong tool on wrong workload; wallet or pot state in a cache that was never meant to be the ledger.

    Symptom in prod: failover restores the wrong pot; leaderboard shows ranks from before a partition.

    What the ADR should have said:HZ = coordination + recovery (lean C). Redis = high-read scores (lean A). Money still flows queue + DB.

    # ADR-003: Hazelcast for table recovery, Redis for leaderboards
    
    Status: Accepted  
    Date: Post modularization scale-up  
    Deciders: Platform ARB, Game squad  
    
     Context
    
    Game nodes are pinned per table with local active state. On node death, we must recover pot, seats, and turn without split-brain. Leaderboards are high-read, tolerate slight staleness, and do not need CP semantics for every rank update.
    
     Decision
    
    Remote Hazelcast cluster (six members, clients only from game/lobby services): `IMap` with sync backup for table snapshots; CP locks + fencing on failover.
    Redis cluster (three nodes) for leaderboards reads/writes — eventual consistency acceptable for ranks.
    Wallet ledger stays queue + database — not in either cache.
    
     Consequences
    
    Positive: Correct recovery for live money tables; leaderboard scale without HZ partition pressure on every rank tick.
    
    Negative: Two cache platforms; clear ownership required per workload.
    
    Obligations: Failover drills; monitor backup lag; no dual writers on game state.
    
    Alternatives considered
    
    | Alternative | Why rejected |
    |-------------|--------------|
    | Redis for table state | Wrong CAP fit for pot recovery without careful fencing; risk of split brain |
    | Hazelcast for leaderboards | Overkill; CP cost not justified for ranks |
    | Embedded HZ in game JVM | Blast radius; fleet churn reshapes grid |


    5. One writer per ledger — “we’ll dual-write during migration”

    Decision: During strangler migration, only Transaction Service writes the wallet ledger. Monolith wallet path must decommission, not linger “just in case.”

    If you skip the ADR:

    Plateau 1 ships with two writers — monolith and new service both mutate balance.

    Consequence: race conditions, support tickets (“where did my chips go?”), reconciliation nightmares, audit failure.

    Symptom in prod: player balance disagrees with ledger after a hand — the gap ArchiMate was supposed to close.

    What the ADR should have said:One writer per ledger. Coexistence duration named. Decommission rule in the same doc as the migration ADR.

     ADR-004: One writer per wallet ledger during strangler migration
    
    Status: Accepted  
    Date: Plateau 1 (transactions strangler)  
    Deciders: Transactions squad, Platform ARB, Risk  
    
     Context
    
    Extracting Transaction Service while the monolith still serves lobby and game creates a coexistence window. Dual wallet paths are tempting for “safety” but produce race conditions and audit gaps.
    
     Decision
    
    Transaction Service is the sole writer to the wallet ledger after cutover.
    Monolith in-process wallet mutation 
    decommissioned by named date — not left dormant. Coexistence: read paths may dual-serve briefly; writes do not.
    
     Consequences
    
    Positive: Auditable ledger; support can trust one source of truth; strangler gap closes cleanly.
    
    Negative: Requires feature flags and migration testing; rollback plan must be explicit.
    
    Obligations: ADR linked in ArchiMate gap P0→P1; reconciliation job until decommission complete.
    
    Alternatives considered
    
    | Alternative | Why rejected |
    |-------------|--------------|
    | Dual-write monolith + service | Race conditions; “where did my chips go?” tickets |
    | Big-bang cutover weekend | Unacceptable downtime risk for live tables |
    | Ledger in game cache | Violates money-off-hot-path principle |
    

    6. Fail-open vs fail-closed — fraud on the hot path

    Decision: On player-facing blocks, prefer explainable decisions and clear audit. On hot-path latency, define what happens when the fraud engine is unavailable — fail – open vs fail-closed is a business choice, not a default in the SDK.

    If you skip the ADR:

    On-call flips behavior under pressure without a recorded principle.

    Consequence: either legitimate players frozen at peak (revenue loss) or abuse runs unchecked during an outage (loss + trust hit).

    Symptom in prod: incident post-mortem says “we thought prod was fail-closed” — staging was fail-open.

    What the ADR should have said:Gameplay path: [X]. Wallet path: [Y]. Owner: Risk + Platform. Review when SLA changes.

    # ADR-005: Fail-open vs fail-closed on the fraud hot path
    
    Status: Accepted  
    Date: Fraud engine Phase D (Technology Architecture)  
    Deciders: Risk, Payments, Platform ARB, Game squad  
    
     Context
    
    The real-time fraud engine sits on game and payment hot paths. When the Decision API is slow or unavailable, someone must decide: block traffic (fail-closed) or allow traffic (fail-open) until recovery. That is not an SDK default — it is a business and compliance choice. Without a recorded policy, staging, prod, and on-call behave differently.
    
     Decision
    
    Define a policy matrix by path and transaction type — documented, tested, and owned by Risk + Platform:
    
    | Path | Default when engine unavailable | Rationale |
    |------|----------------------------------|-----------|
    | Gameplay / join table | Fail-open with rate limits + post-hoc review | Revenue and player experience at peak; friction on outage freezes live tables |
    | Wallet / buy-in / payout | Fail-closed (or queue + async settle with hold) | Money movement requires audit; abuse during outage is unacceptable |
    | High-value withdrawal | Fail-closed always | Chargeback and regulatory exposure |
    
    Cross-cutting rules:
    
    Explainable reason codes required for any player-facing block when engine is healthy  
    Shadow mode in migration — score beside legacy; do not enforce until false-positive SLA holds  
    Break-glass override with Risk RACI — not an undocumented on-call toggle  
    Same matrix in staging and prod — no silent drift  
    
     Consequences
    
    Positive: Incidents have a playbook; no “we thought prod was fail-closed”; ARB can govern Phase G against a written matrix.
    
    Negative: Fail-open on gameplay accepts temporary abuse risk — must pair with velocity caps, DLQ review, and post-incident replay.
    
    Obligations: Latency budgets measured; policy matrix in runbooks; ADR linked from Decision API config and ArchiMate technology constraints.
    
    Alternatives considered
    
    | Alternative | Why rejected |
    |-------------|--------------|
    | One global fail-closed | Legitimate players frozen at peak; revenue loss during engine blip |
    | One global fail-open | Wallet abuse during outage; audit and trust failure |
    | On-call decides per incident | Inconsistent behavior; post-mortem blame without policy |
    | Hard-code in payment service only | Game path undocumented; six squads, six truths |
    | Vendor SDK default | Business policy hidden in library; not governed by ARB |

    7. Build vs buy vs reuse — “let’s build our own Spark”

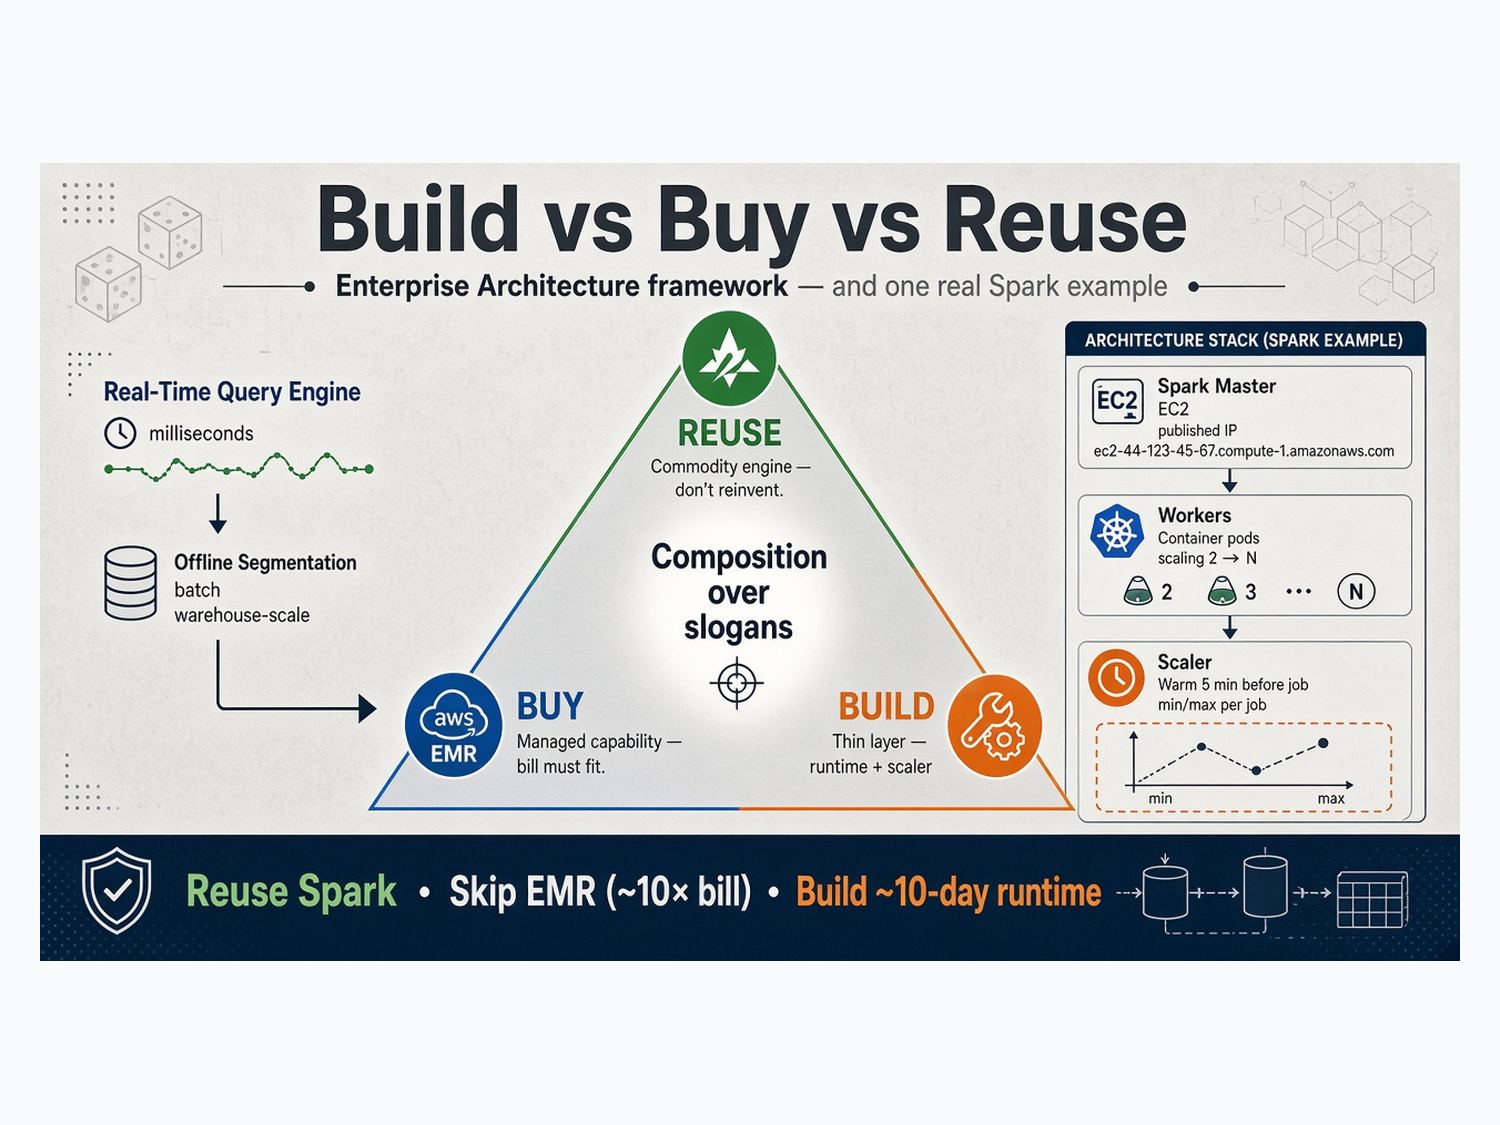
    Decision: Reuse Apache Spark for offline segmentation; buy managed EMR where the bill fit; build only the thin control plane (scheduling, tenancy, guardrails) — not a second distributed compute engine.

    If you skip the ADR:

    A squad starts a 10-month “lightweight batch engine” because EMR “felt expensive” on one slide.

    Consequence: duplicate platform, no hiring market, security review from scratch — savings illusion.

    Symptom in prod: two batch systems, neither owned; CRM segments diverge from real-time truth.

    What the ADR should have said:Reuse Spark. Buy EMR when TCO wins. Build only orchestration we cannot buy.

    # ADR-006: Build vs buy vs reuse for offline segmentation (Spark)
    
    Status: Accepted  
    Date: Phase E (Opportunities & Solutions) — after RTQE platform  
    Deciders: Platform ARB, Data Platform, CRM, Finance  
    
     Context
    
    CRM needed offline behavioral segments that aligned with the Dynamic Real-Time Query Engine — same player truth, batch scale for campaigns and analytics. The commodity capability is distributed batch compute. The enterprise question was not “Spark or not Spark” but reuse the engine, buy managed EMR, or build a custom runtime.
    
     Decision
    
    Compose — do not pick one label for everything:
    
    | Choice | What we chose | What it means |
    |--------|---------------|---------------|
    | Reuse | Apache Spark | Offline segmentation engine-  commodity distributed compute; do not reinvent |
    | Buy (evaluated) | Amazon EMR — not selected for this workload | EMR scales; for our utilization pattern the bill was ~10x a lean in-house runtime |
    | Build | Thin control plane only | Spark master on EC2 (published IP); worker pods autoscale; custom scaler (5‑min warm-up, min/max per job); ~10 days to deliver |
    
    Rules recorded:
    
    Reuse what is commodity (Spark). Buy when TCO and operating model both fit. Build only the layer that turns reuse into enterprise fit — not a second batch engine.
    Offline segments must trace to the same event semantics as RTQE — no shadow data estate for CRM.
    Owner: Data Platform operates runtime, scaler, and upgrades.
    
     Consequences
    
    Positive: ~10× lower ongoing cost vs EMR path for our pattern; delivery in ~10 days; CRM segments stay aligned with real-time truth.
    
    Negative: We own Spark master failover, scaler logic, and security patches — not EMR’s managed boundary.
    
    Obligations: Revisit EMR when utilization or compliance changes; document payback in ARB; no “build our own Spark” proposals without new context.
    
     Alternatives considered
    
    | Alternative | Why rejected |
    |-------------|--------------|
    | Buy EMR for this workload | Capability fit yes; cost fit no (~10× bill for our utilization) |
    | Build a new batch engine from scratch | Enterprise malpractice; no hiring market; years of maintenance |
    | CRM vendor segmentation module only | Duplicate pipeline; diverges from RTQE player truth |
    | Reuse Spark with no control plane | Could not meet warm-up, per-job limits, tenancy we needed |
    | Buy only — no reuse/build split | Treated “buy” as slogan; ignored thin-build payback |


    Strangler order — “let’s split lobby first, it’s easier”

    Decision: Transactions module first via broker — money off the monolith hot path. Lobby + game split in Plateau 2. Sequence documented in migration model and ADRs.

    If you skip the ADR:

    Product pushes lobby microservice first because the UI team is ready.

    Consequence: pretty services, money still in the monolith — the riskiest coupling untouched; false sense of “we migrated.”

    Symptom in prod: “we’re on microservices” but a stuck wallet call still kills live tables.

    What the ADR should have said:Plateau 1 = transactions strangler. Plateau 2 = REST lobby + WebSocket game. Link to ArchiMate gap.

    ADR-007: Strangler migration order — transactions before lobby split
    
    Status: Accepted  
    Date: ADM Phase F (Migration Planning)  
    Deciders: Platform ARB, Product, Game, Transactions, Lobby squads  
    
    Context
    
    Moving from a socket monolith (lobby + game + wallet in one deployable) to modular services tempts teams to split what is easiest first — often lobby/UI — while money stays in the monolith. That creates a false "we migrated” story and leaves the highest-risk coupling (gameplay tick + wallet) untouched. Migration order is an architecture decision, not a sprint convenience.
    
     Decision
    
    Strangler sequence — documented in ArchiMate plateaus and ADRs:
    
    | Plateau | Work package | What ships | Monolith still owns |
    |---------|--------------|------------|---------------------|
    | Plateau 0 | — | Baseline monolith | Lobby, game, wallet (all in one) |
    | Plateau 1 | WP1 — Extract transactions | Broker + Transaction Service; one ledger writer | Lobby + game |
    | Plateau 2 | WP2 — Split lobby and game | REST lobby + WebSocket game handoff | — (target modular) |
    | Later | WP3+ (optional) | Shard game fleet, containerize, autoscale | Per roadmap |
    
    Rules recorded:
    
    1. Plateau 1 = transactions strangler first — money off the gameplay hot path before cosmetic service splits.
    2. Plateau 2 = REST lobby + WebSocket game — only after Plateau 1 coexistence rules and ledger ADR (ADR-004) are met.
    3. No big-bang weekend — each plateau runs in production with named gaps and decommission dates.
    4. Product priority does not override sequence without new ARB context (supersede this ADR).
    
    Consequences
    
    Positive: Riskiest coupling addressed first; live tables keep running; board can recognize plateau transitions; aligns with ADM Phase F and Agile increments.
    Negative: Lobby/UI teams wait for Plateau 2; requires patience and visible migration model so squads do not fork private diagrams.
    
    Obligations: ArchiMate work packages link to ADR-004 (one writer) and this ADR; sprint reviews ask “which plateau does this close?”
    
     Alternatives considered
    
    | Alternative | Why rejected |
    |-------------|--------------|
    | Lobby microservice first (UI ready) | Money still in monolith; stuck wallet call still kills live tables |
    | Big-bang cutover | Unacceptable downtime; no coexistence learning |
    | Game split before transactions | Money path remains on hottest failure domain |
    | Target-state-only migration (skip Plateau 1) | Poster architecture; production never matches model |
    | Parallel all services at once | Six squads, three buses, no decommission plan |
    

    The pattern when ADRs are missing

    What you feelWhat is actually happening
    “We already decided this”Decision lived in Slack / a meeting / one senior’s head
    “Why did they build it that way?”No rejected-options trail — looks like incompetence, was often a tradeoff
    “New squad, same fight”Organizational amnesia — cheaper to write 1 page than rerun ARB
    “Rollback panic”Nobody remembers coexistence rules from migration
    “Architecture is slow”You are re-deciding instead of referencing

    ADRs do not slow you down. They buy back the quarters you lose re-fighting “batch CRM vs real-time platform” — or Hazelcast vs Redis.

    What to put in an ADR (minimum viable)

    1. Title — e.g. `ADR-001: Dynamic Real-Time Query Engine as shared platform (not CRM patch)`

    2. Status — Proposed | Accepted | Superseded

    3. Context — pressure, constraints, plateau you are in

    4. Decision — one clear paragraph

    5. Consequences — positive, negative, what we owe ops/security

    6. Alternatives considered — what you said no to and why

    Length: one to two screens. If it reads like a thesis, nobody will write the next one.

    Where it lives: `docs/adr/` in the repo, or wiki linked from the ArchiMate work package and the Jira epic. Same decision, three doors — one truth.

    ADRs × ADM × Agile × ArchiMate

    PracticeRole
    ADM Phase GGovernance — decisions are controlled, not oral tradition
    AgileADR per meaningful increment — not per sprint theater
    ArchiMateWork packages link to ADR IDs — gaps close with named decisions
    ARBAccept or reject ADRs; do not re-debate without new context

    Anti-patterns (ADR edition)

    Slack as ADR — searchable until it is not; context dies on scroll

    ADR after the outage — post-mortem theater, not architecture

    ADR per README paragraph — team stops writing them

    No “superseded”— two contradictory ADRs, both “accepted”

    ADR with no rejected options— future you cannot defend the call

    Architecture PDF instead of ADRs — pretty, disconnected from backlog

    Checklist: does this decision need an ADR?

    1. Will a new squad ask “why?” in six months?

    2. Did we reject something credible?

    3. Does it affect money, play, or compliance on the hot path?

    4. Does it sequence migration (plateau, coexistence, decommission)?

    5. Will ops need to know failover behavior?

    If yes to two or more — write the ADR before merge, not after the incident.

    Wrapping up

    On a live gaming platform, every architecture decision you skip recording, you pay for twice: once when you make it, again when someone unknowingly unmakes it.

    RTQE as platform. REST vs WebSocket. Hazelcast vs Redis. One writer per ledger. Fail-open vs fail-closed. Build vs buy vs reuse. Strangler order.

    None of those are secret wisdom. They are decisions — and decisions without ADRs become mysteries, then incidents, then quarters in ARB.

    Record the call. Name what you rejected. Link it to the plateau.

    That is EA doing its job: memory over slogans.

    Note on the sample ADRs in this article (ADR-001 through ADR-007 — RTQE platform, REST/WebSocket, Hazelcast/Redis, one ledger writer, fail-open/fail-closed, build vs buy vs reuse, strangler order): they are illustrative mocks — written in real ADR shape to show context, decision, rejected options, and consequences. They are not the literal records from our Architecture Review Board. In production, your ADRs live in your repo or wiki, carry your IDs, dates, deciders, and may differ in detail — use the samples as templates, not as copies of our internal governance pack.
  • Build vs Buy vs Reuse

    Build vs Buy vs Reuse

    Enterprise architecture is full of technology debates that are really ownership debates.

    Do we buy a managed capability? Reuse something that already exists (open source or internal)? Or build the missing piece ourselves?

    Treated as slogans, those words start culture wars. Treated as an EA decision framework, they become a repeatable way to protect cost, time, and differentiation.

    This article is that framework when to choose build, when to choose buy, when to choose reuse.

    I will ground it with one example an offline segmentation engine that followed our Dynamic Real-Time Query Engine work so the guidance is not abstract. That example is illustrative, not the whole story. The same questions apply whether you are deciding on compute, messaging, identity, CI, observability, or a data platform.

    The example is evidence. The decision pattern is the article.

    The EA triangle, without the mythology

    Choice What it means in EA terms

    Buy Pay a vendor for a managed capability (product, platform, or cloud service). You buy outcomes and operating leverage and you buy their constraints and bill shape.

    Reuse Adopt capability that already exists: open source, an internal platform, a shared service. You do not reinvent the commodity.

    Build Create what you cannot get (or cannot afford / cannot customize) from buy or reuse alone — ideally the thinnest layer that unlocks fit.

    Mature architecture almost never picks only one forever. The skilled move is composition .

    Reuse the commodity engine.

    Buy when the managed premium is rational.

    Build only the control plane, integration, or scaling policy that makes the commodity fit your enterprise.

    That composition is what good EA should sound like in an architecture board on Spark, or on anything else.

    When to choose REUSE

    Choose reuse when the capability is commodity, proven, and not where you win in the market.

    Reuse when:

    The problem is already solved well by open source or an internal shared platform

    Differentiating on a from-scratch rewrite would be vanity, not strategy

    Standards, community, and hiring markets already exist around the tool

    You can accept the core abstraction (APIs, execution model) and invest above it

    Do not confuse reuse with do nothing. Reuse still needs governance versions, security, support model, upgrade ownership.

    One example (segmentation) Apache Spark was reuse. Offline segmentation needed distributed batch compute. Spark already owned that problem. Building a new engine would have been enterprise malpractice.

    EA ruleReuse what is commodity. Put architecture energy above it, not underneath it.

    When to choose BUY

    Choose buy when a vendor’s managed service is the fastest, safest path and the total cost of ownership (money + risk + headcount) beats building.

    When to choose BUILD

    Choose build when reuse gives you the core, buy is too expensive or too rigid, and a small, justified build creates enterprise fit.

    Build when

    You need customization the managed product will fight (discovery, scheduling policy, tenancy, warm-up, per-job limits).

    Build time is short relative to the ongoing buy premium.

    Build cost is defensible in payback (engineering spike vs years of platform fees).

    The build surface is thin runtime, scaler, adapter, control plane not a rewrite of the commodity.

    The capability sits on a critical path where vendor constraints become business constraints.

    Do not build when

    You are bored and want to re-implement Spark / Kafka / Kubernetes.

    The only argument is “we are smart enough”.

    Nobody will own upgrades, security, and 2 a.m. failures.

    Buy is only slightly expensive and your team is already overloaded.

    One example (segmentation):We built the runtime around reused Spark not Spark itself.

    Spark master on one EC2, IP published to consumers.

    Slaves as autoscaling container pods, joining via master IP / props on spin-up.

    Baseline around 2 workers, scale to N with demand.

    A custom scaler warm capacity ~5 minutes before job start min/max nodes per job.

    Delivery in about 10 days

    Ongoing cost far below the EMR path (10× difference for us)

    EA rule : Build the thinnest layer that turns commodity reuse into enterprise fit and only when payback and ownership are real.

    An enterprise decision checklist (use this in architecture reviews)

    Before the board debates tools, answer these in order:

    1. Is this differentiating or commodity?

    Commodity → prefer reuse (or buy a managed wrapper). Differentiating → may justify build.

    2. What exactly are we buying / reusing / building?

    Force precision. The engine, the managed platform, and your scaler/adapter are three different decisions.

    3. What is the 12–36 month bill for buy at our utilization?

    Include idle, minimum footprint, support, and growth. Compare to reuse + thin build.

    4. Can the managed option scale?

    Assume yes until proven otherwise then judge cost and control, not myths.

    5. What customization do we actually need?

    List behaviors buy cannot give cleanly.

    6. What is the smallest useful build, and how long will it take?

    If the answer is months with unclear owners, buy may win. If the answer is days with clear ownership, build can win.

    7. Who operates it after launch?

    No owner → do not build. Buy or reuse through a platform team that already exists.

    8. What is the exit / change cost?

    Buy lock-in, reuse upgrade debt, build maintenance pick the debt you can service.

    If you cannot answer these, you are not ready to choose. You are ready to argue.

    This is one application of the framework useful because it shows reuse, buy evaluation, and build in the same decision. Your next board topic might be messaging, identity, or CI the questions stay the same.

    How we got here real-time first, then offline

    The story does not start with Spark. It starts with real-time.

    We had already built a Dynamic Real-Time Query Engine a platform so CRM and marketing could understand player behavior the instant an event happened and act while the player was still on screen. Milliseconds, not nightly batch. Live segments, live treatments, a shared real-time data and query layer instead of bolting another third-party point tool onto CRM.

    I wrote that journey separately the Architecture Board decision to build a platform, the stack, the trade-offs. The short version for this article we built real-time segmentation capability in-house because existing vendor tools could not do what we needed at that latency and because buying our way out of every CRM gap was the wrong enterprise pattern.

    Then management asked the next question.

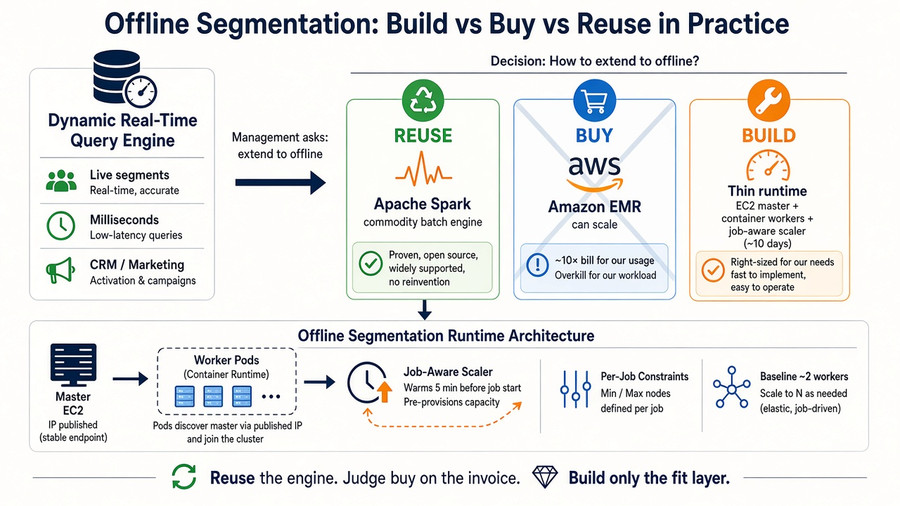
    Real-time covers the moment the player is on screen. The business also needed offline segmentation richer, heavier, historical, warehouse-scale segment computation that does not have to finish in milliseconds, but still has to be ours to operate and affordable to run. Campaigns, deeper behavioral cohorts, reconciliation-style and batch analytics workloads extend the segmentation story beyond the hot path.

    The pressure behind that ask was familiar to any EA review avoid huge cost from third-party vendors for yet another segmentation CDP-style capability we would rent forever. We had already proven we could own the real-time side. Extending to offline was the natural platform move if we chose build / buy / reuse correctly for batch compute, not by copying the real-time design blindly.

    So the sequence was deliberate:

    1. Build real-time(Dynamic Real-Time Query Engine) act in milliseconds stop depending on tools that were never designed for that window.

    2. Extend to offline management wants an offline segment engine for the work that is batch by nature.

    3. Apply build vs buy vs reuse on the offline runtime so we do not replace one vendor bill with another (or with EMR-scale spend) after we just escaped third-party lock-in on the real-time path.

    Offline was not a random Spark project. It was the batch half of a segmentation platform we were already committing to own.

    Context: what offline needed

    We needed an offline segmentation engine bursty batch work over historical and large-scale data, not live gameplay milliseconds. Spark was the right compute model for that half of the problem.

    Reuse

    Open-source Spark the engine. Commodity. Do not reinvent.

    Buy (evaluated)

    Amazon EMR managed Spark path. It can scale. For our usage, the billing model was ~10× a lean self-run option. That failed the EA cost test.

    Build (chosen for the thin layer)

    Built piece Why it was build, not buy

    Containerized Spark workers on a container service Control images, join. behavior, unit economics

    Master on EC2 with published IP(domain) Consumer discovery the way our enterprise clients needed

    Job-aware scaler |Warm ~5 mins before start; min/max nodes per job

    10-day delivery Build time low enough to justify vs ongoing EMR premium

    Outcome in EA language

    DecisionChoiceRationale
    Compute engineReuseSpark is commodity
    Managed Spark platformDo not buy (this case)Bill ~10× despite scaling capability
    Autoscaling runtime + scalerBuildCustomization + short build + cost payback

    How that built runtime worked

    1. Master on EC2 — stable control plane IP(domain) published to job submitters / consumers.

    2. Workers as containers— pods scale out on spin-up they receive master IP. Spark props and associate with the master.

    3. Scaler — warm workers 5 minutes before scheduled jobs each job declares min and max nodes.

    4. Economics — sit near a small floor (often 2 workers), rise to N when the job needs it.

    Build was scoped: runtime and policy, not a science project.

    The same triangle elsewhere (same rules, different topics)

    Once the framework is clear, you can map it onto other enterprise decisions without changing the logic:

    DomainTypical reuseTypical buy questionTypical thin build
    MessagingRabbitMQ / Kafka (OSS)Managed broker / streamingRouting policies, CDC bridges, consumer platforms
    Data / analyticsSpark, Flink, warehouse enginesEMR, serverless Spark, SaaS BIJob-aware scalers, governance adapters
    IdentityOIDC / standard protocolsIdP / IAM suitesEnterprise-specific policy and integration
    CI / deliveryJenkins / GitHub Actions runners patternsFully managed CIInternal pipelines and quality gates
    ObservabilityPrometheus / OpenTelemetryVendor APM suitesCardinality controls, standard labels, routing

    You will not always land on “reuse + thin build.” Sometimes buy wins cleanly. Sometimes pure reuse on an internal platform is enough. The point of EA is to decide deliberately, using one consistent test not to copy the Spark outcome onto every domain.

    Anti-patterns enterprise architecture should stop

    Buy everything— hides a bad bill behind a brand logo

    Build everything — confuses engineering pride with strategy

    Reuse means free — ignores upgrade, CVE, and ownership cost

    It can’t scale” as a buy dismissal — often false check the invoice instead

    Building the engine instead of the adapter — rewriting Spark/Kafka/K8s is rarely EA

    No payback math — if you cannot compare a short build to a long managed premium, you are guessing

    One example = one dogma a good Spark decision is not a mandate to avoid managed services forever

    Closing: the EA stance

    Reuse when it is commodity.

    Buy when the managed operating model and the bill fit.

    Build when a short, owned, thin layer unlocks customization and cost the vendor will not give you.

    One example made that tangible for us: after we built a real-time query / segmentation engine in-house, management wanted to extend to offline to avoid another wave of third-party vendor cost. For that offline segment engine we reused Spark, skipped EMR on a 10× bill (even though EMR can scale), and built a job-aware autoscaling fabric in 10 days with warm-up and per-job min/max.

    Use the example to understand the pattern. Use the checklist on the next decision whatever the domain.

    That is enterprise architecture doing its job: fit over fashion, composition over slogans, framework over single-story dogma.

    If you sit on an architecture board what question do you ask first differentiating vs commodity, or which logo is trending? Drop a comment.

  • Multithreading ≠ Concurrency

    Multithreading ≠ Concurrency

    A live game table explains the difference — and why “just add more threads” is not the answer

    Sometimes we can go back to basics.

    In interviews, design reviews, and late-night debugging, the same words get mixed up: concurrency, parallelism, multithreading. Someone says we need concurrency and the next sentence is “so we’ll make it multithreaded.” Someone else hears “concurrent users” and assumes the server must be full of threads. Another adds “virtual threads” because the JDK version made the slides.

    Those are not the same idea.

    Concurrency is about how you structure work that overlaps in time. Multithreading is one implementation tool. You can be highly concurrent with a single thread. You can run dozens of threads and still get races, starvation, and no real throughput win.

    In this article I separate the terms with a live game table example from high-scale gaming platforms we built — then bridge to the day thread starvation hit us at 100K requests/second on the  Dynamic Real-Time Query Engine and why virtual threads fixed a concurrency cost problem without magically fixing every other one.

    Core concepts. Clear vocabulary. A game you can picture.

    Three words people treat as one.

    TermPlain meaningNot the same as
    ConcurrencyMany tasks in progress — interleaved or overlapping in timeThe same as multithreading
    ParallelismWork truly running at the same time — e.g. multiple tables in the systemAlways being “concurrent by design”
    MultithreadingMultiple threads inside one process as a way to run workA guarantee of correctness or speed

    One line to keep: Concurrency is the problem shape. Parallelism is a performance mode. Multithreading is a mechanism. Don’t say one when you mean another.

    A useful mental model:

    Concurrency = one kitchen has many orders open at once (timers, players, wallets, heartbeats on a single table).

    Parallelism = many kitchens running at once — multiple tables in the system progressing at the same time.

    Multithreading = hiring more cooks for one kitchen — which only helps if they don’t fight over the same knife (shared pot / seats).

    Picture a live game table (or room): several players seated, a round in progress, money on the line, clients connected over a persistent channel.

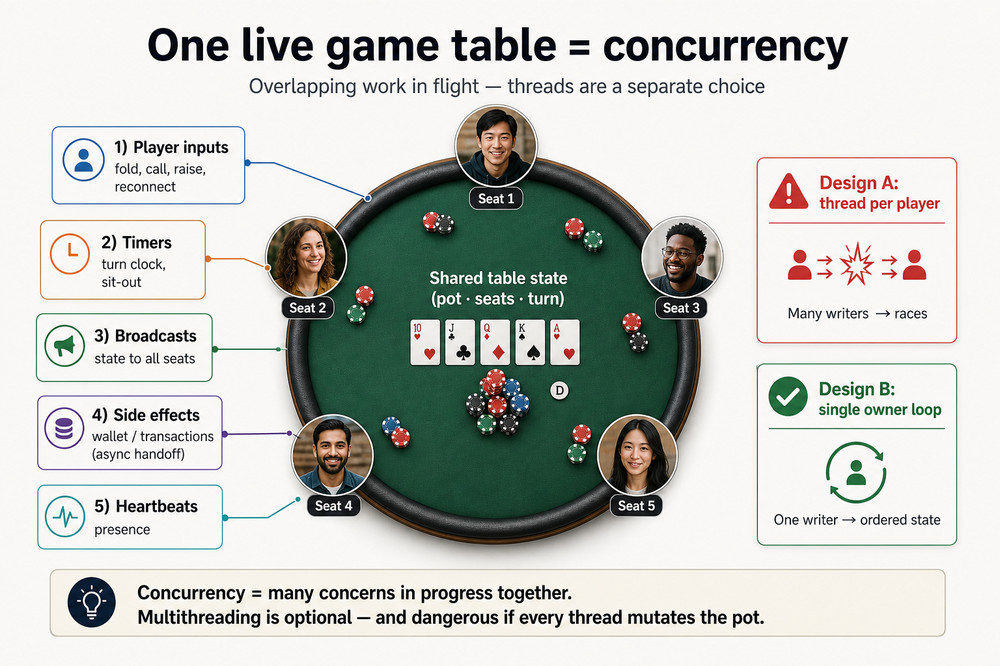
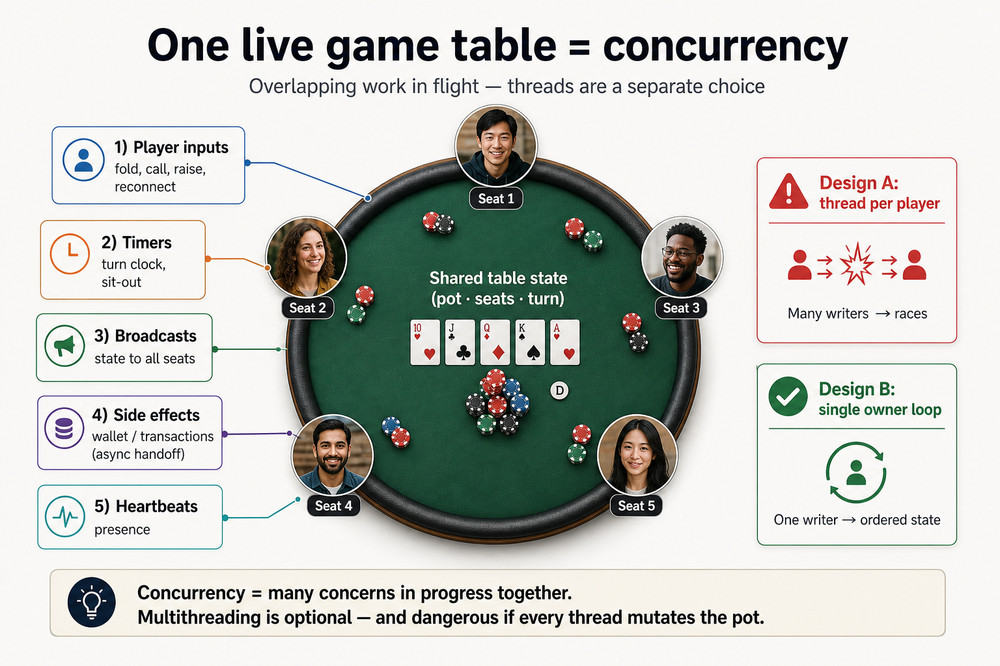
    One live game table = concurrency — overlapping player inputs, timers, broadcasts, side effects, and heartbeats around shared table state; Design A thread-per-player vs Design B single-owner

    At any moment the server is dealing with overlapping work:

    1. Player inputs — fold, call, raise, buy-in, emoji, reconnect

    2. Timers — turn clock, sit-out, reconnect grace

    3. Broadcasts — seat state, pot, winners to everyone at the table

    4. Side effects — wallet / transaction messages that must not block the game loop forever

    5. Heartbeats / presence — who is still here

    That list is concurrency. The table must make progress on many concerns that are “in flight” together. Whether you use one thread or twenty is a separate design choice.

    What goes wrong if you confuse the words

    Confused sentenceWhat actually happens
    “We need concurrency → add threads per player”Shared table state gets races; seats desync; money bugs
    “More threads = faster gameplay”Context switching + lock contention; latency worse
    “Single-threaded means not concurrent”A well-designed game loop is concurrent work, serialized safely
    “Virtual threads will fix our race conditions”They won’t — they change cost of blocking, not shared-memory safety

    So: use threads where the work is embarrassingly parallel or I/O-bound and isolated. Don’t recruit them as a substitute for a clear concurrency model on shared state.

    When “more classic threads” stopped scaling.

    On the  Dynamic Real-Time Query Engine, a behavioral query often touched multiple models. We mapped the work and ran a path per table with `CompletableFuture` so Cassandra reads overlapped — pay roughly the slowest read, not the sum.

    That is concurrency (many reads in flight) implemented with multithreading / async tasks.

    It worked until traffic climbed toward ~100K requests/second. Latency rose — not because Cassandra was dead, but because of thread starvation. Classic platform threads are scarce. Each concurrent table read wanted an OS thread from a bounded pool. The pool became the bottleneck.

    Java 21 virtual threads changed the cost model of that concurrency: many blocking reads could be in flight without tying up a scarce platform thread each. Starvation eased. Memory and GC pressure rose — we tuned with ZGC. Different problem, still real.

    What that night taught us:

    1. We already had concurrency.

    2. Multithreading (classic) was the implementation that hit a wall.

    3. Virtual threads were a better implementation of the same concurrent fan-out — not a synonym for “we finally added concurrency.”

    4. Measuring told us the bottleneck was the threading model, not “buy more database.”

    Cheat sheet

    If you hear…Ask…Often choose…
    “We need concurrency”What overlaps? What must stay ordered?Event loop / actor / queues or threads — by domain
    “Make it multithreaded”What shared state? Who owns writes?Isolate state; parallelize only independent work
    “Bigger thread pool”Are we CPU-bound, I/O-bound, or lock-bound?Fix contention / ownership first; then size pools
    “Virtual threads”Are we blocked on I/O with huge fan-out?Yes → strong candidate; races → still your problem
    “Single-threaded is slow”Slow where — one core saturated, or waiting on I/O?Measure; don’t assume

    Anti-patterns

    Thread per player mutating the same pot without a clear ownership model

    synchronized everywhere as architecture

    Equating concurrent users (product metric) with multithreading (implementation)

    Assuming more threads ⇒ lower latency under shared locks

    Treating virtual threads as a free pass on backpressure and memory

    Wrapping-Up

    Back to basics:

    Concurrency means many things are in progress — for a live table: inputs, timers, broadcasts, money side-effects.

    Parallelism means work truly runs at the same time — for example, running multiple tables in the system across cores or workers.

    Multithreading is one way to chase either — powerful when work is independent, dangerous when everyone writes the same seat map.

    Design the ownership of state first. Then pick the mechanism: single-threaded game loop, thread pool, actors, virtual threads, or a broker handoff. Name the drawbacks — races, starvation, GC, stalled table loops — so nobody is surprised in production.

    Don’t start with “we’ll multithread it.”

    Start with what must overlap, what must stay ordered, and who owns the write.

  • Dynamic Real – Time Query Engine

    Dynamic Real – Time Query Engine

    Every gaming company will tell you the same thing – the difference between a player who stays and a player who leaves is often decided in a matter of seconds. In that window, the right message, the right offer, or the right nudge can change the entire trajectory of a relationship. Miss it, and the moment is gone.

    For us, that window wasn’t seconds. It was milliseconds.

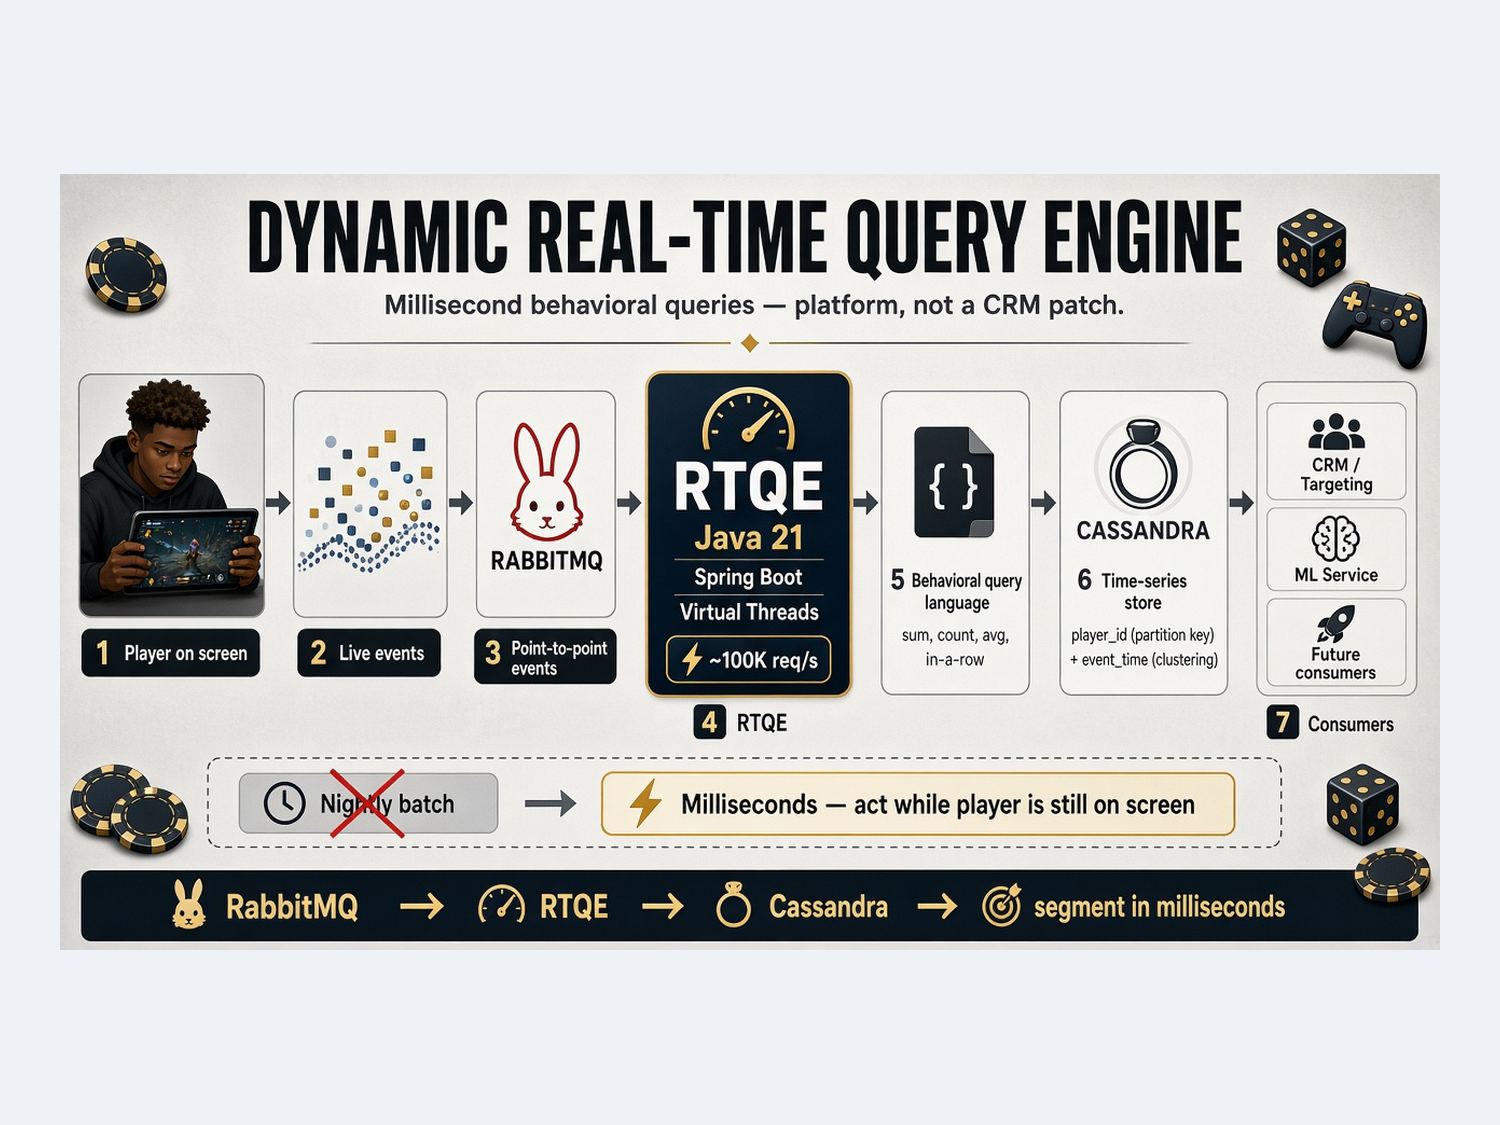
    In 2025, I led the architecture for a system we came to call the Dynamic Real-Time Query Real – Time Query Engine — a platform that lets our CRM and marketing teams understand a player’s behavior the instant an event happens and act on it while the player is still on screen. No nightly batch jobs. No “we’ll reach them tomorrow.” Just live behavior, computed and acted upon in real time.

    It started, as many good systems do, with a problem nobody could solve. Our CRM team had spent six months trying to make existing tools do something they were never designed for. When they hit a wall, the problem landed on the desk of the Architecture Board and that’s where my part of the story begins.

    This article is about how we got from “this is impossible with what we have” to a production system answering behavioral queries in milliseconds. I’ll walk through the problem, the architecture we designed, the trade-offs we wrestled with, and the lessons I took away from leading the effort — both the technical ones and the human ones this — the problem ones and the human ones.

    If you build real-time systems, work in data infrastructure, or care about CRM and marketing technology, I hope you’ll find something useful here.

    The Decision: Build a Platform, Not a Patch

    When my solution architects, the VP of Engineering, the CTO, and I sat down to brainstorm, the easy path would have been to bolt yet another point solution onto the CRM stack. We chose not to.

    The key realization in that room was this — the problem the CRM team brought us wasn’t really a CRM problem — it was a data problem. The CRM tools couldn’t act in milliseconds because nothing in our stack could answer questions about a player’s live behavior fast enough. Solve that, and we wouldn’t just unblock CRM – we’d unlock a whole class of real-time use cases.

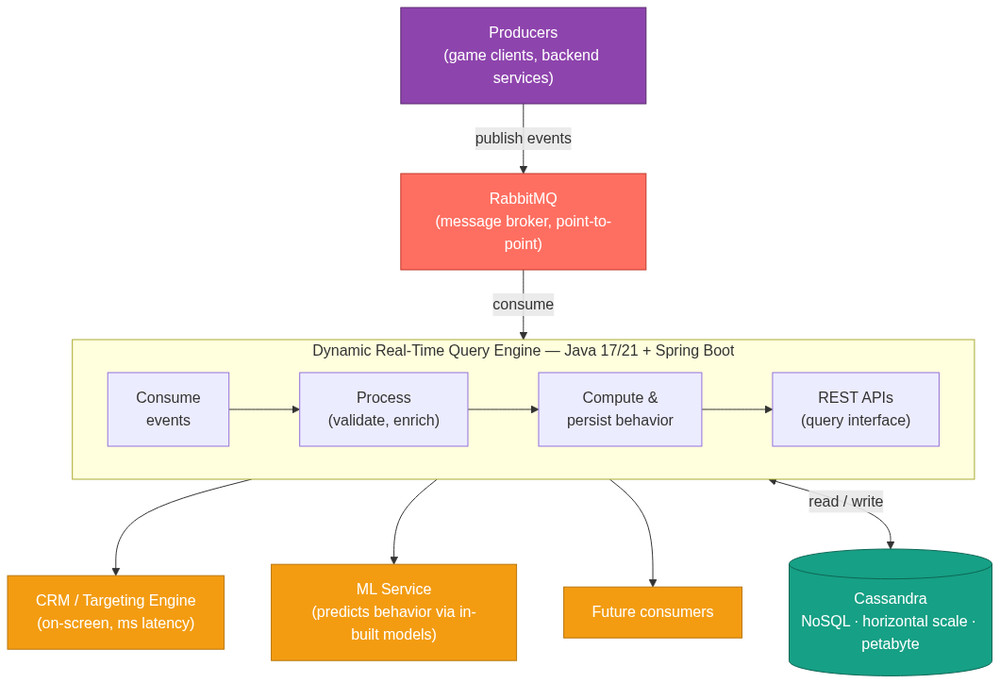
    So we decided to build the Dynamic Real-Time Query Engine as a foundational building block – a piece of platform infrastructure, not a feature. The same engine that resolved the CRM problem could serve several consumers at once:

    The CRM / targeting engine- segment players in real time and trigger on-screen treatments within milliseconds of an event.

    The ML Service- act as a real-time data provider, feeding live behavioral features into in-built ML models that predict what a player is likely to do next.

    Future consumers - any team that needs to ask fast questions about live player behavior, without building their own pipeline.

    This reframing changed everything. Instead of designing a narrow tool for one team, we were designing a shared real-time data and query layer that the whole business could build on. It raised the stakes and the scope – but it was the right call.

    The Tech Stack (and Why We Chose It)

    Architecture is ultimately a series of trade-offs, and the technology choices are where those trade-offs become concrete. Here’s what we picked and the reasoning behind each decision.

     Java 21 - the core language

    We built the engine on Java, running on Java 21. For a system that has to process a high volume of events concurrently while keeping latency low, Java was a natural fit:

    – It’s a mature, battle-tested language for large-scale backend systems, with a rich ecosystem and tooling.

    – Its multithreading and concurrency support is first-class - exactly what we needed to fan out work and squeeze every millisecond out of the hardware.

    Spring Boot - the application framework

    On top of Java, we used Spring Boot to build the service layer. It gave us:

    A fast path to production-grade REST APIs, so consumers (CRM, the ML Service, the targeting engine) could integrate over a clean, well-understood interface.

    Built-in support for the operational concerns that matter in production - configuration, dependency injection, metrics, health checks without reinventing the wheel.

    Cassandra - the storage engine

    For storage we chose Apache Cassandra, a distributed NoSQL database. Given our requirements, this was one of the most important decisions we made:

     Horizontal scalability. Cassandra scales out by simply adding nodes, with no single point of failure – essential for a system expected to grow with player volume.

    Petabyte scale capacity. It’s designed to store and serve enormous datasets, so we wouldn’t hit a ceiling as event volume exploded.

    Write and read-friendly at scale. Its architecture suits a high-ingest, high-query workload like ours, where events stream in constantly and consumers query live behavior just as constantly.

    A traditional relational database would have struggled with this combination of write throughput, data volume, and the need for predictable performance under load. NoSQL – specifically Cassandra was the right tool for the job.

     RabbitMQ - the message broker

    To move events from producers into the engine, we used RabbitMQ as our message broker, following a point-to-point communication model:

    A producer emits an event (a player action) onto a queue.

    The query engine consumes that event, processes it, and persists the result into Cassandra.

    This decoupling was important. The producer doesn’t need to know anything about how the engine works, how busy it is, or whether it’s momentarily slow – it just publishes. RabbitMQ buffers the events and hands them to the engine to consume at its own pace, which keeps the pipeline resilient under bursty load and gives us a clean seam between event production and event processing.

    The Data Model

    If the architecture is the skeleton, the data model is the heart of the engine. In Cassandra, your data model is your performance -you model around the queries you need to answer, not around some abstract notion of “clean” relational design. This is where we spent a disproportionate amount of our thinking, and it paid off.

     One table per event type, modeled as a time series

    We made two deliberate decisions:

    1. One Cassandra table per event type. Each kind of player event gets its own table, rather than cramming every event into a single generic table. This keeps each table’s schema tight, its partitions predictable, and its queries fast.

    2. Model every event table as a time series. Player behavior is inherently a sequence of events over time, so we leaned into Cassandra’s strength: time-series data keyed by entity.

    This time-series design plays a crucial role in how the engine performs. It lets us answer the question that matters most - what has this player been doing recently?” -  by reading a single, contiguous slice of one partition.

    The key design

    For each event table, the primary key is structured as:

    Partition key: `player_id` - all of a player’s events of a given type live together on the same node, so reading one player’s recent activity is a single-partition lookup (the fastest thing Cassandra can do).

    Clustering key: event timestamp- events are physically ordered by time within the partition, so “the last N events” or “events in the last X milliseconds/minutes/hours/days” is a cheap, sorted range scan.

    Remaining columns: the event’s attributes- whatever payload that event type carries.

    A representative table looks like this:

    CREATE TABLE game_result_events (
      player_id text,
      event_time timestamp,
      game_id text,
      rake double,
      winning_amt double,
      is_winner text,
      PRIMARY KEY ((player_id), event_time)
    ) WITH CLUSTERING ORDER BY (event_time DESC);

    A deliberate constraint: a small, fixed set of data types

    We made one more rule that surprised people: across the entire engine, we restricted attribute data types to a small, fixed set`double`, `text`, and `timestamp`.No nested collections, no exotic types - just the primitives we actually needed (whole numbers, monetary/decimal values, strings, and time).

    This was a conscious trade-off in favor of speed, simplicity, and predictability:

    A simpler, uniform schema is far easier to validate, serialize, and query consistently across hundreds of event tables.

    Predictable storage and parsing- a handful of primitive types means no surprises in how data is stored, indexed, or deserialized on the hot path.

    Fewer foot-guns- restricting types kept producers honest and prevented a long tail of edge cases that would have slowed the engine and complicated the code.

    Constraints like this are easy to undervalue, but in a system optimizing for millisecond latency, every bit of uniformity you can buy is latency you don’t have to fight for later.

    The Query Language: A JSON DSL for Behavior

    Here’s where the “query engine” really earns its name. Rather than forcing the CRM and marketing teams to write SQL – or worse, to file engineering tickets every time they wanted a new segment we built our own JSON-based query language.

    The goal was simple: let non-engineers (and other services) express rich behavioral questions as data, not code. A query is just JSON, so it can be created in a UI, stored, versioned, sent over an API, and evaluated by the engine in real time.

     What the language supports

    The DSL is small but expressive. It covers the operations that behavioral targeting actually needs:

    Aggregate functions:`sum`, `count`, `avg` (average), `max`, `min`, `uniqueCount`, and an in-a-row (consecutive streak) aggregate.

    Comparison conditions:`gt` (greater than), `gte` (greater-or-equal), `lt`, `lte`, `eq` (equals), `noteq` (not equals), and `eqic` (equals, ignore case).

    Logical / arithmetic operators: `and`, `or`, `nor`, and a `compare` operator for relating one computed value to another.

    A query is built from two parts:

    1. queryModels - one or more named sub-queries (`q1`, `q2`, …). Each model computes a single aggregate over a single event table, optionally filtered by a time window and `WHERE`- style conditions.

    2. expression- an optional layer that combines the results of those models with conditions and logical operators, turning several aggregates into one true/false segment decision.

     Anatomy of a query model

    Each model has a consistent shape:


    "q1": {
    "queryData": {
    "rake": {
    "value": "0",
    "cond": "gt",
    "function": "sum",
    "searchTime": {
    "cond": "days",
    "from": "600",
    "toDate": ""
    },
    "queryWhereEvent": [
    { "whereColumn": "game_type", "whereCond": "eqic", "whereValue": "Stake" },
    { "whereColumn": "server_type", "whereCond": "eqic", "whereValue": "Stake" },
    { "whereColumn": "bet", "whereCond": "gte", "whereValue": "10" }
    ]
    }
    },
    "tableName": "player_games"
    }

    In plain English, `q1` asks: “Over the last 600 days, for this player’s `player_games` events where `game_type` and `server_type` are ‘Stake’ (case-insensitive) and `bet >= 10`, is the sum of rake` greater than 0”

    Notice how much is packed into one declarative block: the table, the aggregate, the time window (which maps directly onto our time-series clustering key), and the row filters. The engine translates this into an efficient, single-partition, time-bounded scan over Cassandra.

     Composing models into a segment

    The real power shows up when you combine multiple models with an `expression`. Here’s a segment built from five sub-queries, all over a 7-day window:

    Each model produces a number; the `expression` block then thresholds and combines them. Read together, this query targets a specific kind of high-value player in the last 7 days:

    {
    "queryModels": {
    "q1": { "queryData": { "wagering": { "function": "sum", "cond": "gt", "value": "0", "searchTime": { "cond": "days", "from": "7" }, "queryWhereEvent": [] } }, "tableName": "rummy_game_dtls" },
    "q2": { "queryData": { "win_loss_status": { "function": "count", "cond": "eq", "value": "Won", "searchTime": { "cond": "days", "from": "7" }, "queryWhereEvent": [] } }, "tableName": "rummy_game_dtls" },
    "q3": { "queryData": { "bet": { "function": "count", "cond": "eq", "value": "500", "searchTime": { "cond": "days", "from": "7" }, "queryWhereEvent": [] } }, "tableName": "rummy_game_dtls" },
    "q4": { "queryData": { "deposit_amt": { "function": "sum", "cond": "gt", "value": "0", "searchTime": { "cond": "days", "from": "7" }, "queryWhereEvent": [] } }, "tableName": "add_cash_status" },
    "q5": { "queryData": { "redeemed_amt": { "function": "sum", "cond": "gt", "value": "0", "searchTime": { "cond": "days", "from": "7" }, "queryWhereEvent": [] } }, "tableName": "player_redeem_status" }
    },
    "expression": {
    "q1": { "cond": "gt", "value": "10000", "arthOperator": "and" },
    "q2": { "cond": "gte", "value": "1" },
    "q3": { "cond": "gte", "value": "1", "arthOperator": "and" },
    "q4": { "cond": "gte", "value": "5000" },
    "q5": { "cond": "gte", "value": "2500", "arthOperator": "and" }
    }
    }
    

     q1: total `wagering` > 10,000, and

     q2: won at least 1 game (`count` of `Won` ≥ 1), and

    q3: placed a bet of 500 at least once (`count` ≥ 1), and

    q4: deposited at least 5,000, and

    q5: redeemed at least 2,500.

    One JSON document, evaluated across three different event tables, becomes a precise, real-time audience definition the CRM team can act on instantly.

     Going further: comparing computed values

    The language can also relate values to each other, not just to constants, using the `compare` operator. For example:

    {
    "queryModels": {
    "q1": { "queryData": { "wagering": { "function": "avg", "cond": "gt", "value": "0", "searchTime": { "cond": "days", "from": "30" }, "queryWhereEvent": [] } }, "tableName": "rummy_game_dtls" },
    "q2": { "queryData": { "redeemed_amt": { "function": "sum", "cond": "gt", "value": "0", "searchTime": { "cond": "days", "from": "30" }, "queryWhereEvent": [] } }, "tableName": "player_redeem_status" }
    },
    "expression": {
    "q1": { "cond": "gt", "value": ["wallet_balance", "500"], "arthOperator": "compare" },
    "q2": { "cond": "gte", "value": ["q1"], "arthOperator": "compare" }
    }

    Here the `value` is an array, and `compare` lets the engine evaluate one quantity against another – comparing `q1` against a `wallet_balance` (and `500`), and then `q2` against the result of `q1`. This is what makes the language dynamic: expressions can reference other columns and even other query results, not just hard-coded numbers.

    Why build our own language?

    It’s a fair question - why not just expose SQL? A few reasons drove the decision:

    Safety and control. A constrained DSL can’t issue an unbounded or accidentally catastrophic query. Every model maps to a bounded, single-partition, time-windowed read by construction.

    It speaks the domain. “Sum of rake over 600 days where game_type is Stake” is closer to how the CRM team thinks than raw SQL joins.

    It’s portable data. Because a query is just JSON, it can be authored in a UI, stored, shared, A/B tested, and replayed by humans or by the ML Service.

    It maps cleanly onto our data model. The `searchTime` window lines up with the time-series clustering key, and `tableName` with our one-table-per-event-type design, so every query has an efficient execution path.

    Optimization: Parallelism, Thread Starvation, and Virtual Threads

    A query that touches one table is easy. But our real queries like the five – model segment earlier fan out across multiple tables, columns, and date ranges in a single request. Doing that one model at a time would have been far too slow for millisecond targeting. This is where the optimization work began.

    Step 1: Understand the query before you run it

    Before executing anything, the engine scans the incoming query first to segregate exactly what work needs to be done - the distinct tables, columns, and date ranges each model requires. Knowing the full shape of the work up front let us plan the reads intelligently instead of discovering them as we went.

    Step 2: Parallelize across tables

    With the work mapped out, we ran a separate thread for each table, using Java’s `CompletableFuture` to execute the model reads concurrently and then join all the results back together. Instead of paying the latency of each Cassandra read in series, we paid roughly the cost of the slowest one. Leveraging parallelism this way was the single biggest lever for keeping multi-model queries fast.

    Step 3: Hitting the wall - thread starvation at 100K req/s

    This worked beautifully… until it didn’t. As traffic climbed to around 100K requests per second, we started seeing query execution slow down - not because Cassandra was struggling, but because of thread starvation.

    The problem was structural. With classic platform threads, every concurrent table read consumed an OS thread from a bounded pool. At 100K req/s, each spawning multiple `CompletableFuture` tasks, the pool simply couldn’t keep up - requests queued waiting for a thread to free up, and latency spiked. We were starving for threads, not for CPU or database capacity.

     Step 4: Java 21 virtual threads

    This is where the move to Java 21 virtual threads paid off. Virtual threads are lightweight, JVM-managed threads that aren’t pinned 1:1 to OS threads, so you can have a very large number of them in flight at once. The blocking Cassandra reads that previously tied up scarce platform threads now ran on cheap virtual threads instead.

    The effect was dramatic: queries that had been backing up under thread starvation executed seamlessly, because thread availability was no longer the bottleneck. We got the simple, readable blocking-style concurrency model and the scalability to handle the load.

    Step 5: Taming the memory spike with ZGC

    Virtual threads solved the thread starvation, but they introduced a new symptom: with so many threads in flight at once, each holding its own stack and short-lived objects, we saw memory usage spike under heavy load. More concurrency meant more allocation pressure, and that put more work on the garbage collector.

    The fix was to switch to ZGC (the Z Garbage Collector). ZGC is a low-latency, concurrent collector designed to handle very large heaps while keeping pause times in the sub-millisecond range – it does most of its work concurrently with the application instead of stopping the world. Even when virtual threads pushed memory up, ZGC reclaimed it very fast and without the long GC pauses that would have eaten into our millisecond latency budget. Virtual threads gave us the concurrency; ZGC kept that concurrency from turning into latency.

    Step 6: Scale out, not just up

    Finally, the engine runs as a containerized service that autoscales. When request volume surges, more instances spin up to share the load; when it subsides, they scale back down. Combined with virtual threads handling concurrency within each instance, this gave us headroom both vertically (per instance) and horizontally (across instances).

    Tuning Cassandra for Real-Time Reads

    Parallelism and virtual threads got the application tier out of the way - but the engine is only as fast as the database underneath it. Getting Cassandra to serve recent player behavior with predictable, low latency took deliberate tuning.

    Caching the hot path: row cache and key cache

    Our access pattern is heavily skewed toward recent data most queries ask about what a player did in the last few minutes, hours, or days. That makes caching enormously effective:

    Key cache keeps partition-key locations in memory, so Cassandra can skip straight to the right data on disk instead of hunting for it.

    Row cache keeps the actual hot rows in memory, so repeated reads of a player’s latest events are served without touching disk at all.

    Together these dramatically speed up recent reads (and writes) exactly the rows our real-time queries hit most often. For a workload like ours, where the “last N events for this player” is asked over and over, the cache hit rate is high and the latency win is real.

     Compaction: time-window strategy + TTLs

    The second big lever was compaction strategy. Because every event table is a time series and we attach a TTL to events (they age out automatically once they’re no longer relevant), we chose a time-based / time-window compaction strategy rather than the default size-tiered approach.

    This pairing is a natural fit:

    Events written in the same time window are compacted together into the same SSTables.

    When those events expire via TTL, whole SSTables can be dropped at once, instead of expired data lingering and being repeatedly rewritten.

     That means far less wasted compaction work - and, crucially, less garbage-collection pressure on the JVM, which keeps latency steady and avoids GC pauses creeping into our millisecond budget.

    Results

    When the dust settled, the Dynamic Real-Time Query Engine delivered on the promise that started it all:

    Millisecond query latency. Behavioral questions that used to be impossible in real time are now answered in milliseconds, fast enough to act on a player while they’re still on screen.

    Scale we can grow into. After the move to Java 21 virtual threads, the engine sustains around 100K requests per second, with containerized autoscaling absorbing traffic spikes and Cassandra giving us horizontal, petabyte-scale headroom for event volume.

    One engine, many consumers. What began as a CRM problem became shared infrastructure – powering the CRM and targeting engine, and serving as a real-time data provider for the ML Service that predicts player behavior.

    Self-serve for the business. The CRM team now defines brand-new behavioral segments in JSON and puts them live in minutes, with no engineer in the loop.

    What I learned leading the architecture

    The technology was the fun part, but leading the effort taught me just as much.

    Reframe the problem before you solve it. The CRM team handed us a CRM problem. The moment we recognized it was really a data problem, the solution stopped being a patch and became a platform. The most valuable work happened in that reframing – in the room with the CTO and VP – before any code was written.

    Constraints are a feature. Restricting the type system, building a bounded JSON DSL instead of exposing raw SQL, modeling one table per event type – each of these removed options on purpose. Those constraints are exactly what kept the engine fast, safe, and predictable under load.

    Make the data model the first decision, not the last. In a real-time system, the partition key, clustering key, compaction strategy, and TTL aren’t tuning details you bolt on at the end – they’re the foundation the millisecond latency rests on.

    Your bottleneck is rarely where you think. At our peak load we assumed the database was the limit. It wasn’t – it was our threading model. Measuring carefully, rather than guessing, is what pointed us at virtual threads instead of throwing more Cassandra nodes at the problem.

    Raise the level of abstraction for the people you serve. The biggest win wasn’t any single optimization – it was handing the business a language to ask its own questions. Great infrastructure makes other teams faster without making them wait on you.

    Conclusion

    We set out to solve a problem nobody else could crack: understanding a player’s behavior the instant it happened and acting on it within milliseconds. What we built was bigger than the original ask – a Dynamic Real-Time Query Engine that turns live player events into answers fast enough to change outcomes in the moment.

    The pieces all reinforce one another. A time-series data model in Cassandra, keyed by player and ordered by time. A small, safe JSON query language that lets the business express rich behavioral questions as data. Parallel, virtual-thread-powered execution that scales to roughly 100K requests per second. Caching and time-window compaction that keep the hot path in memory and let old data evaporate cleanly. Every decision points in the same direction – toward predictable, low-latency answers at scale.

    But the real lesson is one that outlasts any particular stack: the best architecture doesn’t just solve the problem in front of you – it reframes that problem into a capability the whole business can build on. A CRM team’s six-month headache became a foundational platform that now powers targeting, machine learning, and whatever comes next.

    If you’re tackling something similar – real-time systems, behavioral data, or just the messy art of leading an architecture from a whiteboard to production – I’d love to compare notes.

    Wrapping Up

    To recap the journey in one place:

    The problem: a gaming CRM team needed to compute player behavior from a live event and act on the player, on screen, within milliseconds – something existing CRM tools couldn’t do.

    The decision: instead of patching CRM, we built the Dynamic Real-Time Query Engine as a shared platform building block that also feeds the ML Service and the targeting engine.

    The stack: Java 21 and Spring Boot for the engine, RabbitMQ for point-to-point event delivery, and Cassandra as a horizontally scalable, petabyte-scale NoSQL store.

    The data model: one table per event type, modeled as a time series with player_id as the partition key and event_time as the clustering key, using a small fixed set of data types.

    The query language: a JSON DSL with aggregates (sum, count, avg, max, min, uniqueCount, in-a-row), conditions (gt, gte, lt, lte, eq, noteq, eqic), and operators (and, or, nor, compare) – composed from queryModels and an expression.

    The performance: query-aware parallelism with CompletableFuture, Java 21 virtual threads to beat thread starvation at ~100K req/s, autoscaling containers, plus Cassandra row/key caching and time-window compaction with TTLs.

    The outcome: millisecond behavioral queries at scale, and a self-serve platform the business builds new segments on in minutes.

    If there’s one thing to take away: the best architecture doesn’t just solve today’s problem – it turns that problem into a capability the whole organization can build on.

  • Mama, How Would You Design PUBG and Call of Duty?

    Mama, How Would You Design PUBG and Call of Duty?

    One day my nephew asked me:

    Mama, you work on games, right? How would you design Call of Duty and PUBG–kind of games?”

    (In our family I am Mama— uncle.)

    He expected a short answer — maps, guns, graphics, maybe a cool explosion.

    I almost said “it’s complicated.” Then I realized he had asked the right question for an architect not how the game looks, but how the system is arranged so players can find a match, stay in sync, and not melt the servers when a whole country logs in after school.

    So I answered him the way I wish more design conversations started — with a map.

    Not Erangel. Not Verdansk.

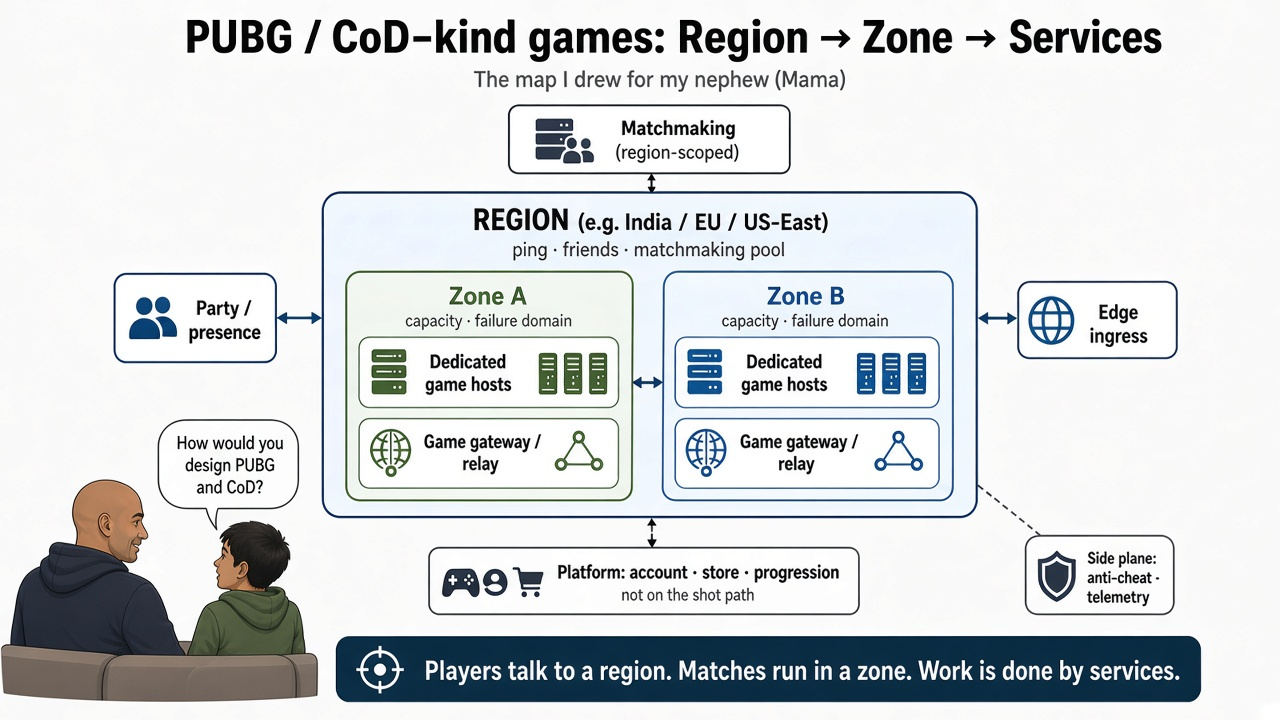
    A map of regions, zones, and services.

    This article is that answer. It is not a leak of PUBG’s or Activision’s private blueprints. Those backends are not fully public. It is how PUBG-like battle royale and Call of Duty–like multiplayer systems are typically shaped — the same vocabulary we use when we design high-scale live games: where the player lands, where the match runs, and which services do the work.


    Draw the map before you name a tool.

    LayerPlain meaningDesign rule
    RegionGeography for ping, friends, and often data rules (India, EU, US-East…)Matchmaking pools and “who can play with whom” are usually region-scoped
    ZoneCapacity and failure slice inside a region (AZ / cluster / pod group)A zone can die without killing the whole region; matches drain carefully
    ServiceA job the software must do (matchmaking, dedicated game host, store, anti-cheat)Put each job where latency and ownership demand — not where the slide looks busy

    Mama’s rule: Players don’t talk to “PUBG” or “CoD.” They talk to a region. Matches run in a zone. Work is done by services.

    If you cannot place a component on that map, you are not designing yet. You are collecting logos.

    Naming trap — three different “zones”

    Kids (and engineers) mix these up:

    1. Cloud / infra zone — failure domain and capacity (this article’s “Zone”)

    2. Map / safe zone — the shrinking circle in a battle royale

    3. Interest / AOI zone — which other players and objects your client needs to know about right now

    Same English word. Three layers. Keep them separate or the design review becomes comedy.

    Walk one player from the sofa to the victory screen.

    Here is the journey I walked with him — overlaid on the map.

    1. Launch / login → hits platform services (identity, entitlement). Often multi-region capable, with a home region.

    2. Lobby / party → region-aware presence: you queue with friends who share a sensible ping story.

    3. Matchmaking → region-scoped queues (skill, playlist, fill rules). Output: “here is your match” + where to connect.

    4. Connect to the match → client is steered to a dedicated game host (or relay path) sitting in a zone inside that region.

    5. In match → authoritative simulation ticks; state replication; interest management; voice often match- or region-local.

    6. Match end → results hand off to progression / inventory / battle pass (platform path — not on every bullet).

    7. Side planes (always on) → anti-cheat signals, telemetry, crash reports — async, must not block the tick.

    This is the same shape as systems I have lived with in live gaming

    matchmaking as a door (ask and get placed), then a live channel / dedicated path as the room (stay connected for the session). Different genre. Same map logic.

    What sits where — service placement.

    ServiceTypical place on the mapWhy
    Identity / accountPlatform (multi-region or hub + cache)Shared identity; not every shot
    Store / battle pass / inventoryPlatformMoney and catalog; after or beside the match
    Friends / party / presenceRegion-awareParties hate cross-ocean ping
    MatchmakingRegionPool quality + latency
    Dedicated game servers / match instancesZone inside regionBlast radius; capacity; drain on failure
    Real-time game gateway / relayEdge / regionLow latency into the match
    VoiceMatch- or region-localLatency and moderation scope
    Anti-cheat (client + server signals)Match-local collect → hub aggregateHot path light; intel can be global
    Telemetry / analyticsSide plane → lakeNever block the tick
    Content / config catalogHub + CDNVersioned rules, maps, playlists

    Hot path rule: bullets, movement, and tick authority stay near the player (region / zone). Store, heavy CRM, and batch analytics do not sit on the shot path — same lesson as handing wallet work off a live game loop.

    Same map — different match shape (PUBG-like vs CoD-like)

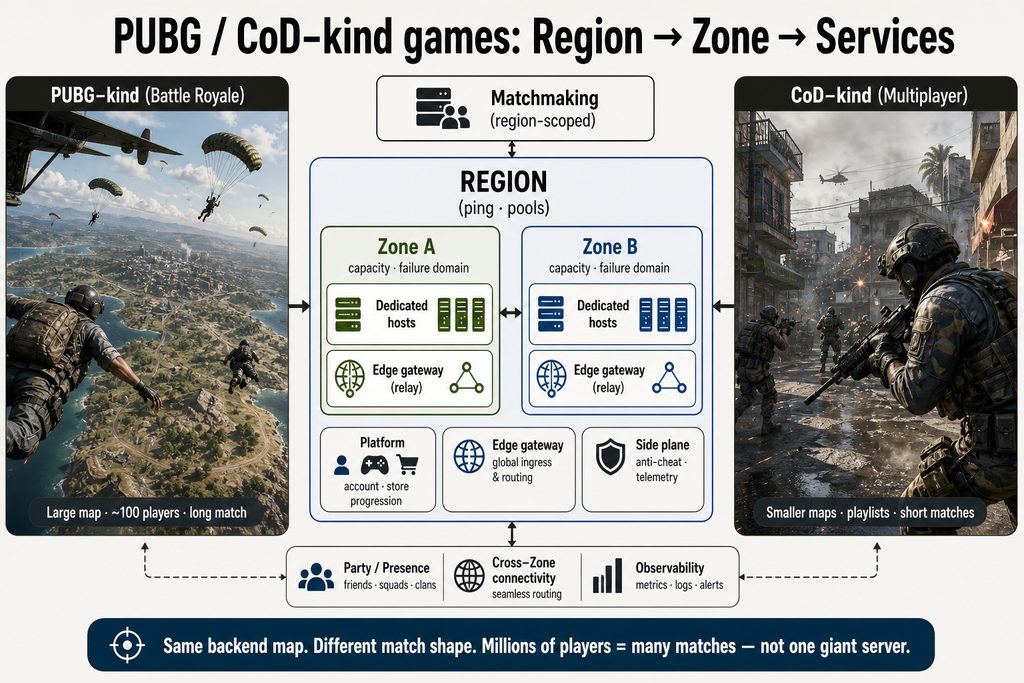
    I did not crown a winner. Both sit on Region → Zone → Services. The match they host looks different, so the fleet math changes.

    ConcernPUBG-like battle royaleCoD-like multiplayer modes
    Match shapeLarge map, many players, longer sessionSmaller maps, shorter matches, many playlists
    Dedicated fleetFewer, heavier matches per hostHigher match churn; faster spin-up / teardown
    In-match pressureWide map + vehicles + loot; strong AOI neededTighter spaces; higher tick / precision pressure
    Region pressureLaunch and country spikes; fill 80–100 seatsPlaylist and seasonal spikes; many small rooms
    What stays identicalRegion routing, zone isolation, platform vs game split, async side planesSame

    And, not vs: PUBG-kind and CoD-kind games are not rival architectures. They are two workloads on one map.

    Region design — what my nephew already understood as “ping”

    Ping budget decides who can share a match comfortably.

    Party constraints beat “perfect MMR” if the squad cannot hear each other in time.

    Empty lobby risk — a region that is too fine-grained never fills; too coarse and someone plays on 180 ms.

    Data and policy — some player data and commerce prefer staying in-region.

    Spill / overflow— when a region is on fire, you need a written rule (queue, wait, or rare cross-region with honesty about ping).

    Region is a product decision as much as a cloud dropdown.

    Zone design — why we don’t put every match in one basket

    Inside a region, zones exist so that:

    Hardware or AZ failure takes some capacity, not all evening matches

    You can drain live matches (finish or migrate carefully) instead of hard-killing everyone

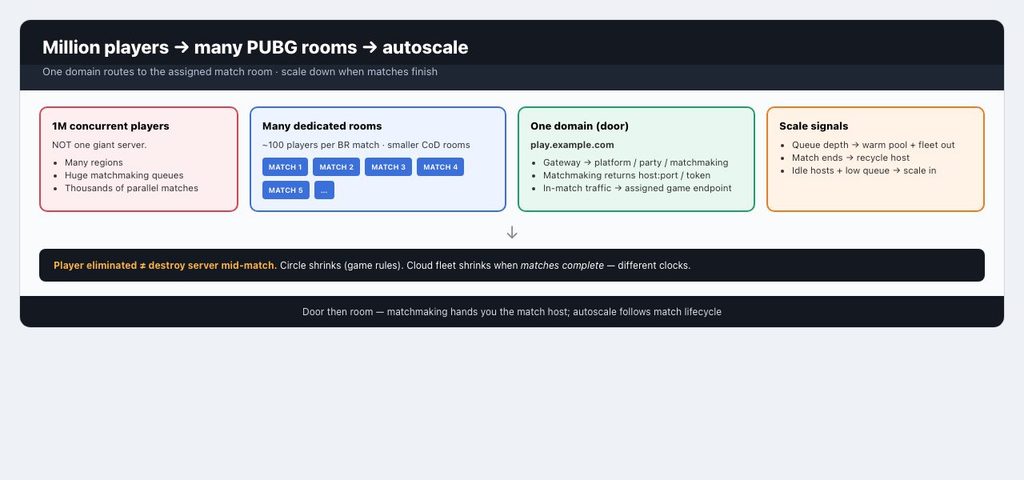
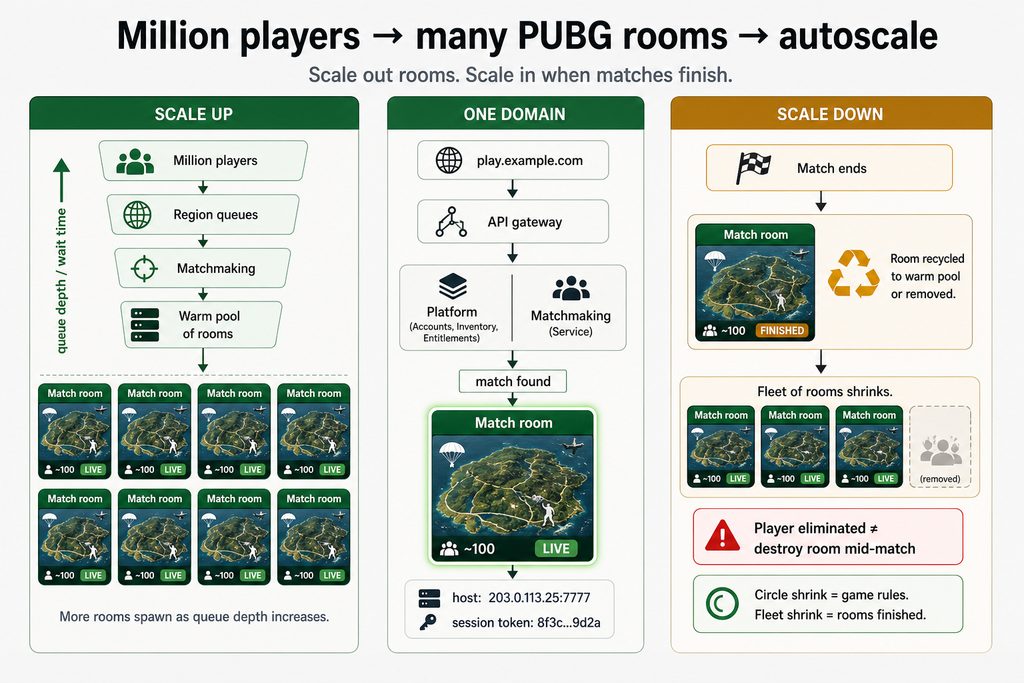
    You scale dedicated fleets in slices — warm pools, playlist packs, BR vs small-modes packing

    If matchmaking returns a host, that host’s zone is part of the placement decision — not an afterthought for Ops.

    In-match: who owns the truth

    For both genres, the dedicated (or authoritative) simulation owns match truth: positions, damage, win conditions. Clients predict for feel; server corrects for fairness.

    That is the same ownership lesson as a live game table :many concerns in flight (inputs, timers, broadcasts), but one clear writer of shared state beats “a thread per player mutating the pot.” Concurrency is required. Chaos is optional.

    Interest management (AOI) decides what to send whom — critical on a big BR map, still important in tight CoD lanes. That is game zoning, not your cloud zone.

    One contest, a million players” — how scale actually works

    This is the question my nephew asked next: if a big contest has millions of players, do you build one giant server? When people die, do servers shrink? How does one website send everyone to the right place?

    First correction — millions are not one match

    A PUBG-like battle royale match is on the order of 100 players (squads fill seats). A CoD-like mode is often fewer per room.

    A million concurrent players means roughly:

    many regions taking traffic

    huge matchmaking queues

    thousands / tens of thousands of matches in parallel

    each match on a dedicated host (or a packed host running N matches) inside a zone

    So the platform scales by creating many small rooms, not by stuffing a million people into one simulation. One match still has one authoritative world. Parallelism across the system is many matches at once the same idea as many live tables running together.

    Scale up — when the lobby catches fire

    Autoscaling is driven by signals, not vibes:

    SignalWhat scales up
    Login / store spikePlatform pods / gateway capacity
    Queue depth / wait timeMatchmaking workers + dedicated game fleet
    Assigned matches with no free hostWarm pool → cold start more game servers in the zone
    Telemetry / anti-cheat volumeSide-plane consumers (async)

    Typical dedicated-fleet pattern:

    1. Keep a warm pool of ready game hosts per region/zone (already loaded build, waiting).

    2. Matchmaking fills a lobby → allocates a host (or a match slot on a packed host) → returns connection info to clients.

    3. If warm pool is empty and queue is deep → scale out more hosts (VM/container/bare metal — product choice).

    4. Cap scale with max so a bug cannot bankrupt you; spill to “queue longer” rather than infinite machines.

    Platform and matchmaking scale on HTTP/API metrics. The game fleet scales on matches needing a home.

    Scale down — when the game finishes (not when one player dies)

    When a match ends:

    1. Dedicated host writes results → hands off to progression / rewards (platform).

    2. Players disconnect from that match path.

    3. Host is recycled (back to warm pool) or terminated if pool is fat.

    4. Autoscaler watches idle hosts + queue depth → scale in slowly (hysteresis), so a two-minute lull does not thrash.

    Important: when players are eliminated mid-match (“next circle, fewer alive”), you usually do not tear down or resize away the dedicated server. The match is still live until a winner (or draw) is declared. What can drop is work inside the match:

    fewer clients to replicate to

    lighter AOI / bandwidth

    fewer voice peers

    The map safe zone shrinks (game rules). The cloud zone fleet shrinks when matches complete and demand falls — different clocks.

    Eliminated players often return to lobby / spectate / platform that traffic moves back to lobby and platform services, while the match host keeps serving survivors.

    One domain — how everyone reaches the right service

    Players remember one name: `play.example.com` or the game client’s embedded API host. Behind that single domain:

    Client
      → DNS (often geo / latency aware) → regional edge
        → API gateway / load balancer
             ├─ /auth /store /profile     → Platform services
             ├─ /party /presence          → Region-aware social
             ├─ /matchmaking              → Matchmaking
             └─ after “match found”
                  → dedicated host or game gateway
                     (host:port / token / session from matchmaking — not the store URL)

    (host:port / token / session from matchmaking — not the store URL)

    So:

    One public front door (domain + gateway) for lobby and platform.

    Matchmaking is the redirector in product terms— it tells the client which game service/host owns this match.

    In-match traffic often goes straight to the assigned game endpoint (UDP/dedicated), not through the store cluster.

    Sticky cookies / tokens / session tickets bind “this player → this match host” for the life of the session.

    That is the same door then room idea: REST (or similar) to get placed; persistent/realtime path to play.

    What “services change” as the match levels up

    MomentWhat changes
    QueuingMatchmaking + platform busy; game fleet warming
    Match startOne host owns that match; clients leave matchmaking hot path
    Players eliminated / circle shrinksGame rules + AOI load change; dedicated host stays
    Match overHost frees; progression spikes briefly; fleet can scale down
    Contest evening endsQueue collapses → scale in matchmaking and game fleet toward baseline

    Services do not randomly morph mid-bullet. Ownership moves along the journey: platform → matchmaking → dedicated match → platform again. Autoscaling follows which layer is busy, match by match, region by region.

    What not to put on the map’s hot path

    Charging a card on every elimination

    Synchronous “call the data warehouse” mid-fight

    Treating matchmaking REST polls as the game loop

    One global region “because simpler”

    One mega-zone “because Kubernetes”

    Draw the map. Then pick UDP, dedicated hosts, queues, and stores into the boxes — not instead of the boxes.

    Wrapping-Up

    My nephew wanted guns and maps. I gave him regions, zones, and services.

    Region— where the player belongs for ping and pools.

    Zone — where this match’s capacity and failure story live.

    Services— the jobs: platform, matchmaking, dedicated simulation, edge, side planes.

    PUBG-kind and Call of Duty–kind games share that map. They differ in match shape and fleet churn, not in inventing a different physics of distributed systems.

    Mama’s rule: draw the map before you name the tool.

    Mama’s second rule: a million players means many matches and an autoscaler with a warm pool — not one infinite server that shrinks every time someone is eliminated.

    When someone asks how you would “design PUBG or CoD,” start with: Which region? Which zone? Which service owns this moment in the player’s journey? Then ask: What signal scales that service up — and what event lets it scale down?

    One honest caveat: this design is my assumption — a teaching map from how large multiplayer backends are typically shaped, and from patterns I have used in live gaming. It may not be the exact architecture the owners of PUBG or Call of Duty run in production. Their real systems will differ in topology, naming, vendors, and secrets we do not see. Use the map to think; do not treat it as a reverse-engineered blueprint.