Category: TOGAF

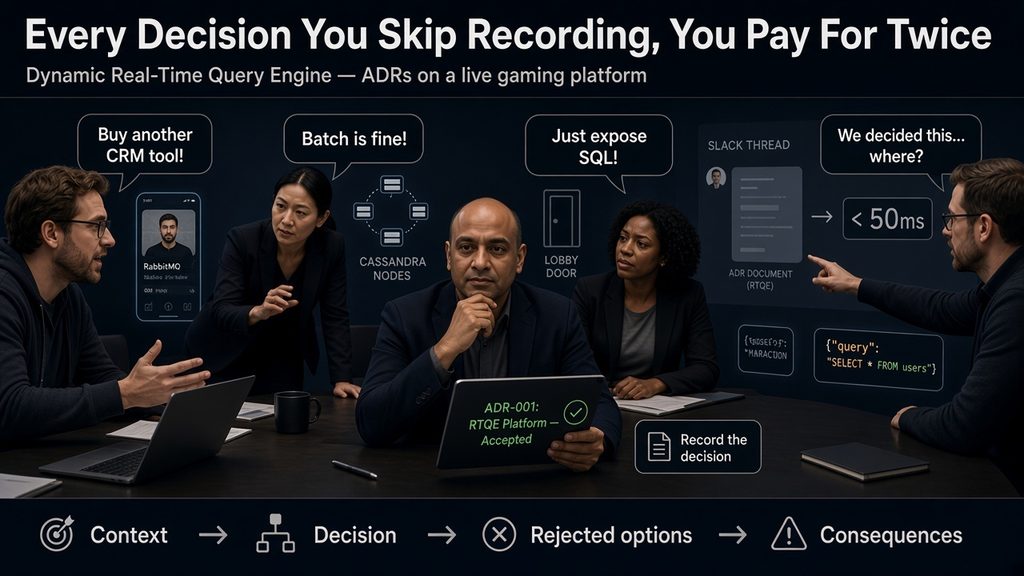
  • Every Architecture Decision You Skip Recording, You Pay For Twice

    What missing ADRs cost when you build a Dynamic Real-Time Query Engine — not Slack archaeology

    When a new requirement lands, we open the Architecture Review Board (ARB).

    Someone says “buy another CRM tool.” Someone says batch is fine. Someone says “we already decided this.” Nobody can find where.

    That is not a tooling problem. It is a memory problem — and on a live gaming platform, forgotten decisions become production incidents, re-opened fights, and sprints that undo last year’s work.

    Architecture Decision Records (ADRs) are how you stop paying twice. Not bureaucracy. Insurance.

    This article is not “what is an ADR” from a textbook. It is a consequence map: decisions we made on a real gaming platform — Dynamic Real-Time Query Engine for CRM and ML, lobby and live tables, wallets, caches, fraud on the hot path — and what broke when we did not record them (or recorded them in Slack and lost them).
    ADR in one sentence (before the horror stories)

    An ADR is a short, durable note: what we decided, why, what we rejected, and what we will revisit. It lives in the repo or architecture wiki — not in a thread that scrolls away.

    You do not need one ADR per line of code. You need one per decision that will be fought again if nobody wrote it down.

    The decisions that deserved an ADR (gaming platform)

    On our platform, these were not “nice to have.” They were forks in the road:

    DecisionWhy it mattered
    RTQE as platform, not CRM patch (Cassandra + JSON DSL + shared API)Millisecond behavioral queries for CRM and ML — one live truth
    JSON DSL vs open SQL on RTQECRM self-serve segments without unbounded queries
    REST for lobby, WebSocket for live playDoor vs room — different conversation shapes
    Hazelcast for table state, Redis for leaderboardsCAP — coordination vs eventually-fresh reads
    One writer per ledgerNo duplicate wallet paths during strangler migration
    Fail-open vs fail-closed on fraudBlock play vs allow play when the engine is down
    Reuse Spark / buy EMR vs build segmentationCost and ownership on offline compute
    Strangler order: transactions before lobby splitPlateau sequence — not big-bang weekend

    Each of these showed up in ARB, stand-up, or a new squad’s first design doc. When we missed recording one, we paid a predictable price.

    If you miss the ADR — consequences (with examples)

    1. Dynamic Real-Time Query Engine — “let’s bolt another tool onto CRM”

    Decision: Build the Dynamic Real-Time Query Engine (RTQE) as shared platform infrastructure — not a one-team patch. Cassandra time-series (one table per event type), JSON DSL for behavioral segments, REST APIs for CRM, targeting, and the ML Service — millisecond queries while the player is still on screen.

    If you skip the ADR:

    CRM buys or builds a narrow segmentation tool; ML spins up a second live-events pipeline.

    Consequence: duplicate stores, segments that lag live play, engineering tickets for every new behavioral question — “real-time” becomes tomorrow’s batch.

    Symptom in prod: offer fires after the player left the table; CRM and ML disagree on the same player’s last hour.

    What the ADR should have said: Platform not patch. One engine, many consumers. Bounded JSON DSL — not open SQL. Cassandra model: player_id partition, time-series clustering, one table per event type.

    2. RTQE query model — “just expose SQL to CRM”

    Decision: JSON DSL with bounded query models (aggregates, time windows, expressions) — every query maps to a single-partition, time-bounded Cassandra read. Not open SQL to marketing tools.

    If you skip the ADR:

    Someone exposes read-only SQL “for flexibility.”

    Consequence: unbounded scans, hot partitions, on-call pages during a campaign launch — CRM “self-serve” becomes production roulette.

    Symptom in prod: segment job takes 30 seconds; player already churned; CRM blames “the real-time engine.”

    What the ADR should have said: DSL not SQL. Query bounds by construction. `searchTime` aligns with time-series clustering key.

    # ADR-001: Dynamic Real-Time Query Engine as shared platform (not CRM patch)
    
    Status: Accepted  
    Date: 02/15/2025
    Deciders: Architecture Board, CRM, Data Platform, ML, VP Engineering  
    
    Context
    
    CRM and marketing needed to understand live player behavior and act while the player is still on screen  not via nightly batch jobs. Existing CRM tools could not answer behavioral questions in milliseconds. The easy path was another point solution on the CRM stack; the harder path was shared platform infrastructure.
    
     Decision
    
    Build the Dynamic Real-Time Query Engine (RTQE) as a foundational building block:
    
     Apache Cassandra — one table per event type, time-series keyed by `player_id` + event timestamp
     JSON DSL — bounded behavioral queries (aggregates, time windows, expressions) — not open SQL
    Event ingest pipeline — decoupled producers into the engine (point-to-point queues)
     Java 21 + Spring Boot — REST APIs for CRM, targeting, and ML Service consumers
    Platform scope — same engine serves multiple consumers — not a single-team patch
    
    Consequences
    
    Positive: Millisecond segments on live play; CRM self-serve in JSON; ML gets real-time features from one pipeline; ~100K req/s headroom with virtual threads and horizontal scale.
    
    Negative: Custom DSL to maintain; Cassandra modeling discipline required; platform team owns SLAs for all consumers.
    
    Obligations: Query bounds by construction; one-table-per-event-type schema governance; document rejected “SQL over everything” and “CRM-only tool” paths.
    | Alternative | Why rejected |
    |-------------|--------------|
    | Bolt-on CRM segmentation tool | Solves one team;  duplicate pipelines for ML; batch mindset |
    | Expose raw SQL to CRM | Unbounded queries; safety and ops risk on hot path |
    | Single generic events table | Partition and query unpredictability; fights Cassandra strengths |
    | Nightly batch only | Misses the conversion window — player already left |


    3. REST lobby + WebSocket game — “let’s poll matchmaking from the socket”

    Decision: REST (or HTTP API) to Lobby — find and join a table. WebSocket to Game — live play, broadcast state.

    If you skip the ADR:

    Mobile team polls lobby state over the game socket every 500ms for simplicity.

    Consequence: socket fan-out load explodes; matchmaking logic bleeds into game shards; you cannot scale browse traffic separately from seated players.

    Symptom in prod: lobby spike during a tournament drags down live tables — the failure domain you split on purpose.

    What the ADR should have said:Door = REST. Room = WebSocket. Do not merge because one client library is easier.

    # ADR-002: REST for lobby (door), WebSocket for game (room)
    
    Status: Accepted  
    Date: Migration Plateau 2  
    Deciders: Mobile, Lobby, Game squads, ARB  
    
    Context
    
    Matchmaking is request/response: find table, seat player, return connection info. Live play is a long-lived session: broadcast state, play events, timers. Mixing both on one channel couples browse traffic to seated-player scale.
    
    ## Decision
    
    REST (HTTP API) to Lobby Service for matchmaking, presence, seat assignment.
    - WebSocket to Game Service for live table play after seat confirmed.
    - Session handoff: lobby returns game shard / token; client opens socket to game fleet.
    
    ## Consequences
    
    Positive: Scale lobby on browse traffic independently; clear failure domains; matches client mental model (door vs room).
    
    Negative: Two client integrations; handoff bugs if token/session contract drifts.
    
    Obligations: Document handoff flow in API spec; integration tests for seat → connect path.
    
     Alternatives considered
    
    | Alternative | Why rejected |
    |-------------|--------------|
    | WebSocket for lobby polling | Fan-out and unnecessary persistent connections for short requests |
    | REST for live play | Polling latency unacceptable for table state; wrong conversation shape |
    | Single monolith socket | Failure domain and scale coupling we were leaving |
    

    4. Hazelcast vs Redis — the annual CAP debate

    Decision: Hazelcast (remote cluster, sync backup, CP locks) for recoverable table state when a game node dies. Redis (cluster) for leaderboards where slightly stale ranks are acceptable.

    If you skip the ADR:

    Every new hire proposes Redis for everything or Hazelcast for “leaderboards too.”

    Consequence: quarters lost to benchmarks and slide decks; wrong tool on wrong workload; wallet or pot state in a cache that was never meant to be the ledger.

    Symptom in prod: failover restores the wrong pot; leaderboard shows ranks from before a partition.

    What the ADR should have said:HZ = coordination + recovery (lean C). Redis = high-read scores (lean A). Money still flows queue + DB.

    # ADR-003: Hazelcast for table recovery, Redis for leaderboards
    
    Status: Accepted  
    Date: Post modularization scale-up  
    Deciders: Platform ARB, Game squad  
    
     Context
    
    Game nodes are pinned per table with local active state. On node death, we must recover pot, seats, and turn without split-brain. Leaderboards are high-read, tolerate slight staleness, and do not need CP semantics for every rank update.
    
     Decision
    
    Remote Hazelcast cluster (six members, clients only from game/lobby services): `IMap` with sync backup for table snapshots; CP locks + fencing on failover.
    Redis cluster (three nodes) for leaderboards reads/writes — eventual consistency acceptable for ranks.
    Wallet ledger stays queue + database — not in either cache.
    
     Consequences
    
    Positive: Correct recovery for live money tables; leaderboard scale without HZ partition pressure on every rank tick.
    
    Negative: Two cache platforms; clear ownership required per workload.
    
    Obligations: Failover drills; monitor backup lag; no dual writers on game state.
    
    Alternatives considered
    
    | Alternative | Why rejected |
    |-------------|--------------|
    | Redis for table state | Wrong CAP fit for pot recovery without careful fencing; risk of split brain |
    | Hazelcast for leaderboards | Overkill; CP cost not justified for ranks |
    | Embedded HZ in game JVM | Blast radius; fleet churn reshapes grid |


    5. One writer per ledger — “we’ll dual-write during migration”

    Decision: During strangler migration, only Transaction Service writes the wallet ledger. Monolith wallet path must decommission, not linger “just in case.”

    If you skip the ADR:

    Plateau 1 ships with two writers — monolith and new service both mutate balance.

    Consequence: race conditions, support tickets (“where did my chips go?”), reconciliation nightmares, audit failure.

    Symptom in prod: player balance disagrees with ledger after a hand — the gap ArchiMate was supposed to close.

    What the ADR should have said:One writer per ledger. Coexistence duration named. Decommission rule in the same doc as the migration ADR.

     ADR-004: One writer per wallet ledger during strangler migration
    
    Status: Accepted  
    Date: Plateau 1 (transactions strangler)  
    Deciders: Transactions squad, Platform ARB, Risk  
    
     Context
    
    Extracting Transaction Service while the monolith still serves lobby and game creates a coexistence window. Dual wallet paths are tempting for “safety” but produce race conditions and audit gaps.
    
     Decision
    
    Transaction Service is the sole writer to the wallet ledger after cutover.
    Monolith in-process wallet mutation 
    decommissioned by named date — not left dormant. Coexistence: read paths may dual-serve briefly; writes do not.
    
     Consequences
    
    Positive: Auditable ledger; support can trust one source of truth; strangler gap closes cleanly.
    
    Negative: Requires feature flags and migration testing; rollback plan must be explicit.
    
    Obligations: ADR linked in ArchiMate gap P0→P1; reconciliation job until decommission complete.
    
    Alternatives considered
    
    | Alternative | Why rejected |
    |-------------|--------------|
    | Dual-write monolith + service | Race conditions; “where did my chips go?” tickets |
    | Big-bang cutover weekend | Unacceptable downtime risk for live tables |
    | Ledger in game cache | Violates money-off-hot-path principle |
    

    6. Fail-open vs fail-closed — fraud on the hot path

    Decision: On player-facing blocks, prefer explainable decisions and clear audit. On hot-path latency, define what happens when the fraud engine is unavailable — fail – open vs fail-closed is a business choice, not a default in the SDK.

    If you skip the ADR:

    On-call flips behavior under pressure without a recorded principle.

    Consequence: either legitimate players frozen at peak (revenue loss) or abuse runs unchecked during an outage (loss + trust hit).

    Symptom in prod: incident post-mortem says “we thought prod was fail-closed” — staging was fail-open.

    What the ADR should have said:Gameplay path: [X]. Wallet path: [Y]. Owner: Risk + Platform. Review when SLA changes.

    # ADR-005: Fail-open vs fail-closed on the fraud hot path
    
    Status: Accepted  
    Date: Fraud engine Phase D (Technology Architecture)  
    Deciders: Risk, Payments, Platform ARB, Game squad  
    
     Context
    
    The real-time fraud engine sits on game and payment hot paths. When the Decision API is slow or unavailable, someone must decide: block traffic (fail-closed) or allow traffic (fail-open) until recovery. That is not an SDK default — it is a business and compliance choice. Without a recorded policy, staging, prod, and on-call behave differently.
    
     Decision
    
    Define a policy matrix by path and transaction type — documented, tested, and owned by Risk + Platform:
    
    | Path | Default when engine unavailable | Rationale |
    |------|----------------------------------|-----------|
    | Gameplay / join table | Fail-open with rate limits + post-hoc review | Revenue and player experience at peak; friction on outage freezes live tables |
    | Wallet / buy-in / payout | Fail-closed (or queue + async settle with hold) | Money movement requires audit; abuse during outage is unacceptable |
    | High-value withdrawal | Fail-closed always | Chargeback and regulatory exposure |
    
    Cross-cutting rules:
    
    Explainable reason codes required for any player-facing block when engine is healthy  
    Shadow mode in migration — score beside legacy; do not enforce until false-positive SLA holds  
    Break-glass override with Risk RACI — not an undocumented on-call toggle  
    Same matrix in staging and prod — no silent drift  
    
     Consequences
    
    Positive: Incidents have a playbook; no “we thought prod was fail-closed”; ARB can govern Phase G against a written matrix.
    
    Negative: Fail-open on gameplay accepts temporary abuse risk — must pair with velocity caps, DLQ review, and post-incident replay.
    
    Obligations: Latency budgets measured; policy matrix in runbooks; ADR linked from Decision API config and ArchiMate technology constraints.
    
    Alternatives considered
    
    | Alternative | Why rejected |
    |-------------|--------------|
    | One global fail-closed | Legitimate players frozen at peak; revenue loss during engine blip |
    | One global fail-open | Wallet abuse during outage; audit and trust failure |
    | On-call decides per incident | Inconsistent behavior; post-mortem blame without policy |
    | Hard-code in payment service only | Game path undocumented; six squads, six truths |
    | Vendor SDK default | Business policy hidden in library; not governed by ARB |

    7. Build vs buy vs reuse — “let’s build our own Spark”

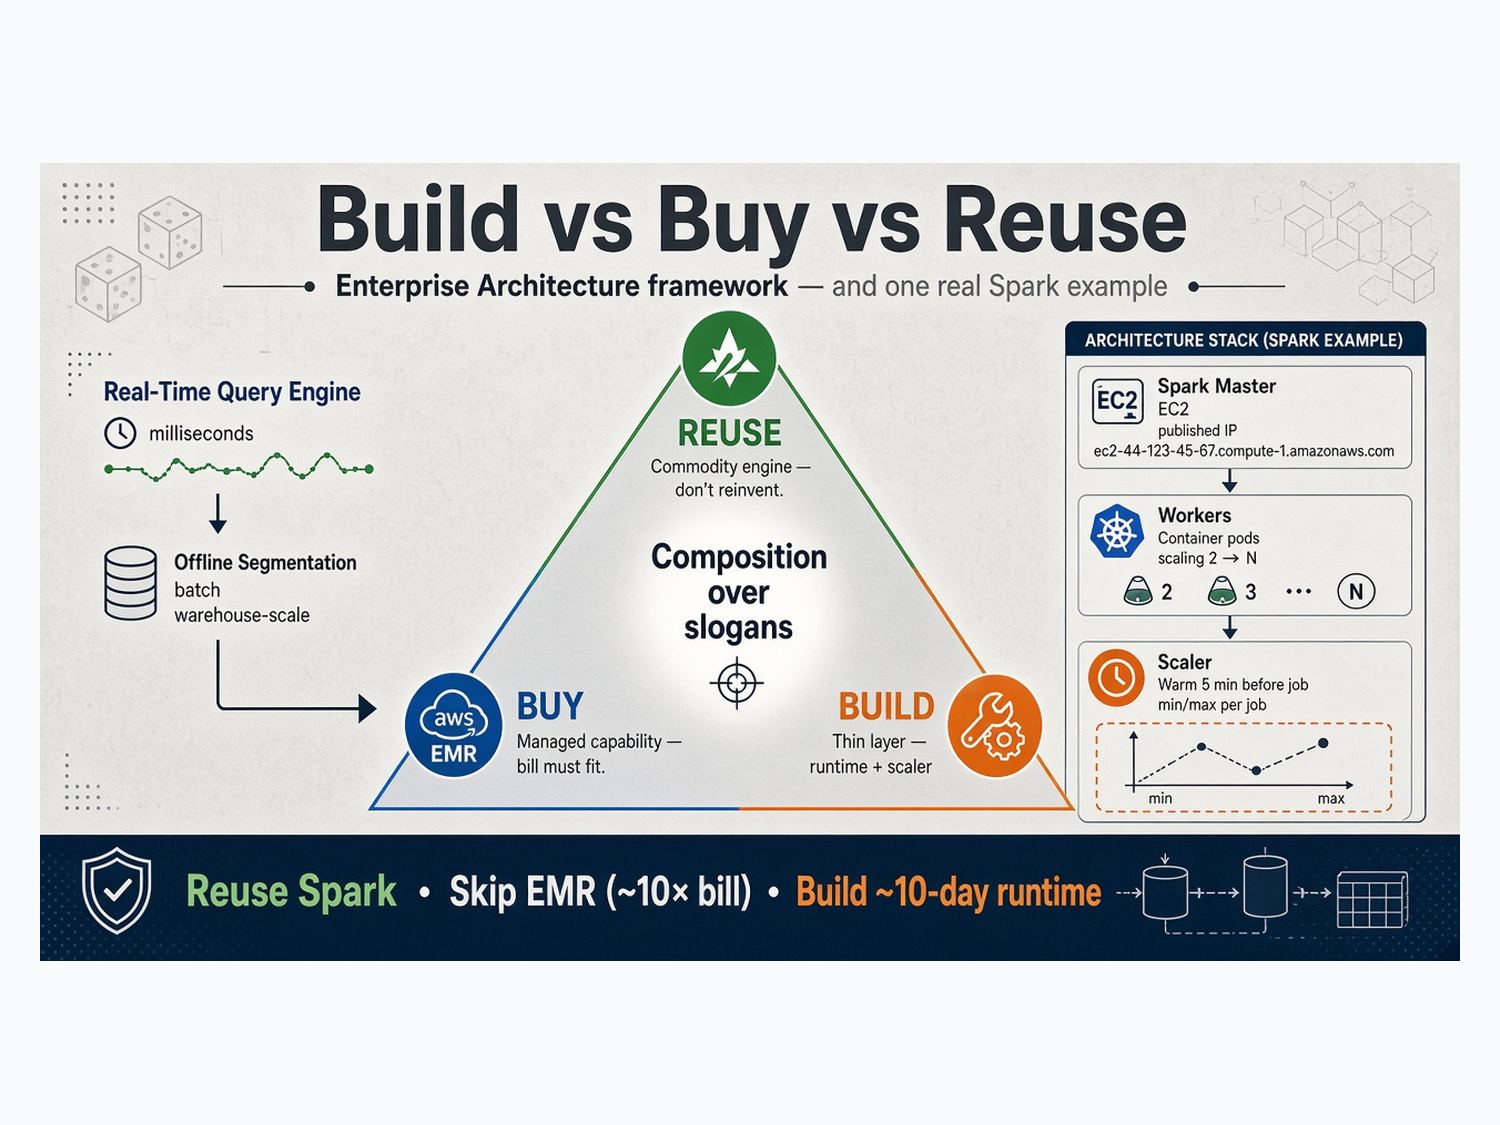
    Decision: Reuse Apache Spark for offline segmentation; buy managed EMR where the bill fit; build only the thin control plane (scheduling, tenancy, guardrails) — not a second distributed compute engine.

    If you skip the ADR:

    A squad starts a 10-month “lightweight batch engine” because EMR “felt expensive” on one slide.

    Consequence: duplicate platform, no hiring market, security review from scratch — savings illusion.

    Symptom in prod: two batch systems, neither owned; CRM segments diverge from real-time truth.

    What the ADR should have said:Reuse Spark. Buy EMR when TCO wins. Build only orchestration we cannot buy.

    # ADR-006: Build vs buy vs reuse for offline segmentation (Spark)
    
    Status: Accepted  
    Date: Phase E (Opportunities & Solutions) — after RTQE platform  
    Deciders: Platform ARB, Data Platform, CRM, Finance  
    
     Context
    
    CRM needed offline behavioral segments that aligned with the Dynamic Real-Time Query Engine — same player truth, batch scale for campaigns and analytics. The commodity capability is distributed batch compute. The enterprise question was not “Spark or not Spark” but reuse the engine, buy managed EMR, or build a custom runtime.
    
     Decision
    
    Compose — do not pick one label for everything:
    
    | Choice | What we chose | What it means |
    |--------|---------------|---------------|
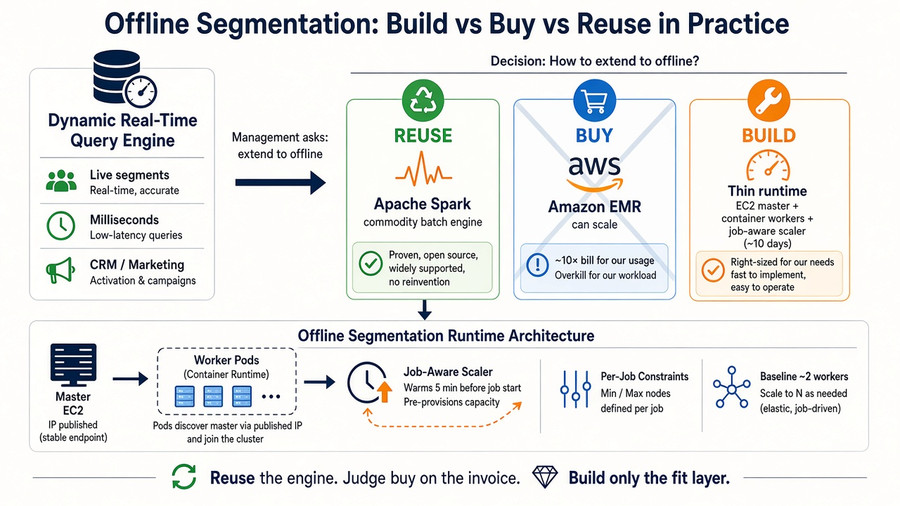
    | Reuse | Apache Spark | Offline segmentation engine-  commodity distributed compute; do not reinvent |
    | Buy (evaluated) | Amazon EMR — not selected for this workload | EMR scales; for our utilization pattern the bill was ~10x a lean in-house runtime |
    | Build | Thin control plane only | Spark master on EC2 (published IP); worker pods autoscale; custom scaler (5‑min warm-up, min/max per job); ~10 days to deliver |
    
    Rules recorded:
    
    Reuse what is commodity (Spark). Buy when TCO and operating model both fit. Build only the layer that turns reuse into enterprise fit — not a second batch engine.
    Offline segments must trace to the same event semantics as RTQE — no shadow data estate for CRM.
    Owner: Data Platform operates runtime, scaler, and upgrades.
    
     Consequences
    
    Positive: ~10× lower ongoing cost vs EMR path for our pattern; delivery in ~10 days; CRM segments stay aligned with real-time truth.
    
    Negative: We own Spark master failover, scaler logic, and security patches — not EMR’s managed boundary.
    
    Obligations: Revisit EMR when utilization or compliance changes; document payback in ARB; no “build our own Spark” proposals without new context.
    
     Alternatives considered
    
    | Alternative | Why rejected |
    |-------------|--------------|
    | Buy EMR for this workload | Capability fit yes; cost fit no (~10× bill for our utilization) |
    | Build a new batch engine from scratch | Enterprise malpractice; no hiring market; years of maintenance |
    | CRM vendor segmentation module only | Duplicate pipeline; diverges from RTQE player truth |
    | Reuse Spark with no control plane | Could not meet warm-up, per-job limits, tenancy we needed |
    | Buy only — no reuse/build split | Treated “buy” as slogan; ignored thin-build payback |


    Strangler order — “let’s split lobby first, it’s easier”

    Decision: Transactions module first via broker — money off the monolith hot path. Lobby + game split in Plateau 2. Sequence documented in migration model and ADRs.

    If you skip the ADR:

    Product pushes lobby microservice first because the UI team is ready.

    Consequence: pretty services, money still in the monolith — the riskiest coupling untouched; false sense of “we migrated.”

    Symptom in prod: “we’re on microservices” but a stuck wallet call still kills live tables.

    What the ADR should have said:Plateau 1 = transactions strangler. Plateau 2 = REST lobby + WebSocket game. Link to ArchiMate gap.

    ADR-007: Strangler migration order — transactions before lobby split
    
    Status: Accepted  
    Date: ADM Phase F (Migration Planning)  
    Deciders: Platform ARB, Product, Game, Transactions, Lobby squads  
    
    Context
    
    Moving from a socket monolith (lobby + game + wallet in one deployable) to modular services tempts teams to split what is easiest first — often lobby/UI — while money stays in the monolith. That creates a false "we migrated” story and leaves the highest-risk coupling (gameplay tick + wallet) untouched. Migration order is an architecture decision, not a sprint convenience.
    
     Decision
    
    Strangler sequence — documented in ArchiMate plateaus and ADRs:
    
    | Plateau | Work package | What ships | Monolith still owns |
    |---------|--------------|------------|---------------------|
    | Plateau 0 | — | Baseline monolith | Lobby, game, wallet (all in one) |
    | Plateau 1 | WP1 — Extract transactions | Broker + Transaction Service; one ledger writer | Lobby + game |
    | Plateau 2 | WP2 — Split lobby and game | REST lobby + WebSocket game handoff | — (target modular) |
    | Later | WP3+ (optional) | Shard game fleet, containerize, autoscale | Per roadmap |
    
    Rules recorded:
    
    1. Plateau 1 = transactions strangler first — money off the gameplay hot path before cosmetic service splits.
    2. Plateau 2 = REST lobby + WebSocket game — only after Plateau 1 coexistence rules and ledger ADR (ADR-004) are met.
    3. No big-bang weekend — each plateau runs in production with named gaps and decommission dates.
    4. Product priority does not override sequence without new ARB context (supersede this ADR).
    
    Consequences
    
    Positive: Riskiest coupling addressed first; live tables keep running; board can recognize plateau transitions; aligns with ADM Phase F and Agile increments.
    Negative: Lobby/UI teams wait for Plateau 2; requires patience and visible migration model so squads do not fork private diagrams.
    
    Obligations: ArchiMate work packages link to ADR-004 (one writer) and this ADR; sprint reviews ask “which plateau does this close?”
    
     Alternatives considered
    
    | Alternative | Why rejected |
    |-------------|--------------|
    | Lobby microservice first (UI ready) | Money still in monolith; stuck wallet call still kills live tables |
    | Big-bang cutover | Unacceptable downtime; no coexistence learning |
    | Game split before transactions | Money path remains on hottest failure domain |
    | Target-state-only migration (skip Plateau 1) | Poster architecture; production never matches model |
    | Parallel all services at once | Six squads, three buses, no decommission plan |
    

    The pattern when ADRs are missing

    What you feelWhat is actually happening
    “We already decided this”Decision lived in Slack / a meeting / one senior’s head
    “Why did they build it that way?”No rejected-options trail — looks like incompetence, was often a tradeoff
    “New squad, same fight”Organizational amnesia — cheaper to write 1 page than rerun ARB
    “Rollback panic”Nobody remembers coexistence rules from migration
    “Architecture is slow”You are re-deciding instead of referencing

    ADRs do not slow you down. They buy back the quarters you lose re-fighting “batch CRM vs real-time platform” — or Hazelcast vs Redis.

    What to put in an ADR (minimum viable)

    1. Title — e.g. `ADR-001: Dynamic Real-Time Query Engine as shared platform (not CRM patch)`

    2. Status — Proposed | Accepted | Superseded

    3. Context — pressure, constraints, plateau you are in

    4. Decision — one clear paragraph

    5. Consequences — positive, negative, what we owe ops/security

    6. Alternatives considered — what you said no to and why

    Length: one to two screens. If it reads like a thesis, nobody will write the next one.

    Where it lives: `docs/adr/` in the repo, or wiki linked from the ArchiMate work package and the Jira epic. Same decision, three doors — one truth.

    ADRs × ADM × Agile × ArchiMate

    PracticeRole
    ADM Phase GGovernance — decisions are controlled, not oral tradition
    AgileADR per meaningful increment — not per sprint theater
    ArchiMateWork packages link to ADR IDs — gaps close with named decisions
    ARBAccept or reject ADRs; do not re-debate without new context

    Anti-patterns (ADR edition)

    Slack as ADR — searchable until it is not; context dies on scroll

    ADR after the outage — post-mortem theater, not architecture

    ADR per README paragraph — team stops writing them

    No “superseded”— two contradictory ADRs, both “accepted”

    ADR with no rejected options— future you cannot defend the call

    Architecture PDF instead of ADRs — pretty, disconnected from backlog

    Checklist: does this decision need an ADR?

    1. Will a new squad ask “why?” in six months?

    2. Did we reject something credible?

    3. Does it affect money, play, or compliance on the hot path?

    4. Does it sequence migration (plateau, coexistence, decommission)?

    5. Will ops need to know failover behavior?

    If yes to two or more — write the ADR before merge, not after the incident.

    Wrapping up

    On a live gaming platform, every architecture decision you skip recording, you pay for twice: once when you make it, again when someone unknowingly unmakes it.

    RTQE as platform. REST vs WebSocket. Hazelcast vs Redis. One writer per ledger. Fail-open vs fail-closed. Build vs buy vs reuse. Strangler order.

    None of those are secret wisdom. They are decisions — and decisions without ADRs become mysteries, then incidents, then quarters in ARB.

    Record the call. Name what you rejected. Link it to the plateau.

    That is EA doing its job: memory over slogans.

    Note on the sample ADRs in this article (ADR-001 through ADR-007 — RTQE platform, REST/WebSocket, Hazelcast/Redis, one ledger writer, fail-open/fail-closed, build vs buy vs reuse, strangler order): they are illustrative mocks — written in real ADR shape to show context, decision, rejected options, and consequences. They are not the literal records from our Architecture Review Board. In production, your ADRs live in your repo or wiki, carry your IDs, dates, deciders, and may differ in detail — use the samples as templates, not as copies of our internal governance pack.
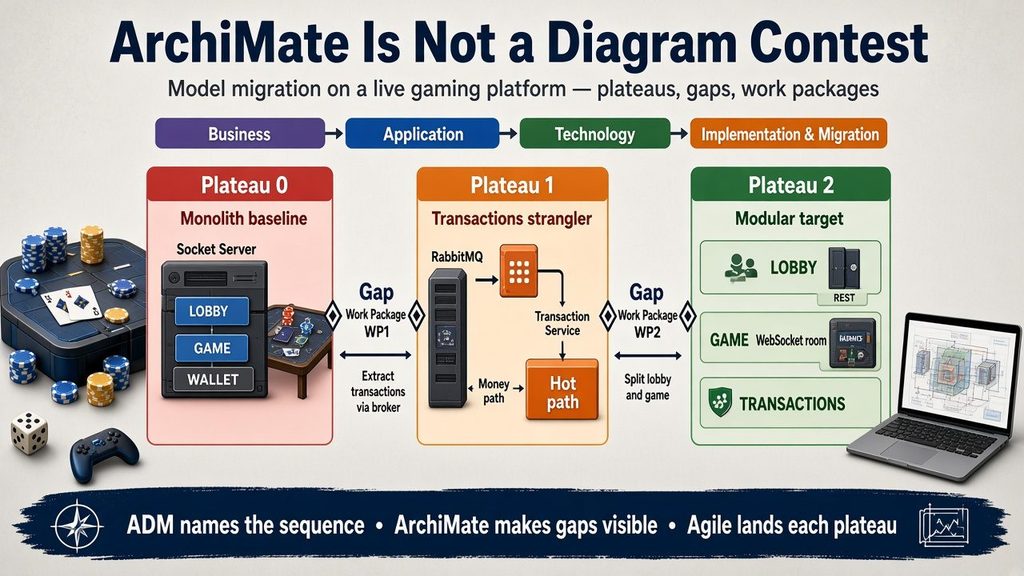
  • ArchiMate  Is  Not  a  Diagram Contest

    ArchiMate Is Not a Diagram Contest

    Model migration so every squad sees the same map — a live gaming platform example

    ArchiMate gets dismissed the same way TOGAF sometimes does: too theoretical, too many boxes, nobody reads it.

    That is fair — when ArchiMate is used as wallpaper.

    It becomes valuable when you are in the middle of a migration and six squads are drawing six different pictures of the monolith we are leaving and “the platform we are building.” Lobby thinks matchmaking is already separate. Transactions thinks money moved last quarter. Platform thinks RabbitMQ is “temporary.” Product thinks the cutover is next sprint.

    At that moment, ArchiMate is not ceremony. It is a shared language for baseline, target, gaps, and plateaus – the same story ADM Phase F asks for, but visible to engineers, product, and the architecture board.

    This article shows how to model a real migration on a live gaming platform: monolith → modular services (lobby, game, transactions) with a message broker on the money path and strangler increments — not every ArchiMate element, only the ones that stop migration arguments.

    Why migration is the right ArchiMate proving ground

    Migrations fail in predictable ways:

    Invisible dependencies — “we extracted transactions” but the monolith still writes wallet state

    Fake target states — microservices on a slide, monolith in production

    Big-bang fantasy — no plateaus, no coexistence rules

    Squad-local truth — each team’s diagram stops at its repo boundary

    ArchiMate does not fix those by itself. It fixes them when you model what exists, what must exist, what changes between plateaus, and who delivers each slice.

    If ArchiMate only works on greenfield data-center refresh decks, it is not Enterprise Architecture. Strangler migration on a live game platform is the stress test.

    ArchiMate in one sentence (before we draw anything)

    ArchiMate is a standard notation for describing enterprise architecture across business, application, and technology — and for showing how you move from today to tomorrow without pretending tomorrow arrives in one weekend.

    You do not need every viewpoint. You need the right viewpoint for the decision in the room.

    ViewpointUse it when…
    LayeredExplaining structure — what serves what
    Implementation & MigrationPlanning strangler moves, plateaus, work packages
    MotivationLinking business drivers to migration scope (optional but powerful in Phase A)

    ADM tells you to plan migration (Phase F). ArchiMate shows what you are migrating in which order.

    The example: baseline monolith on a gaming platform

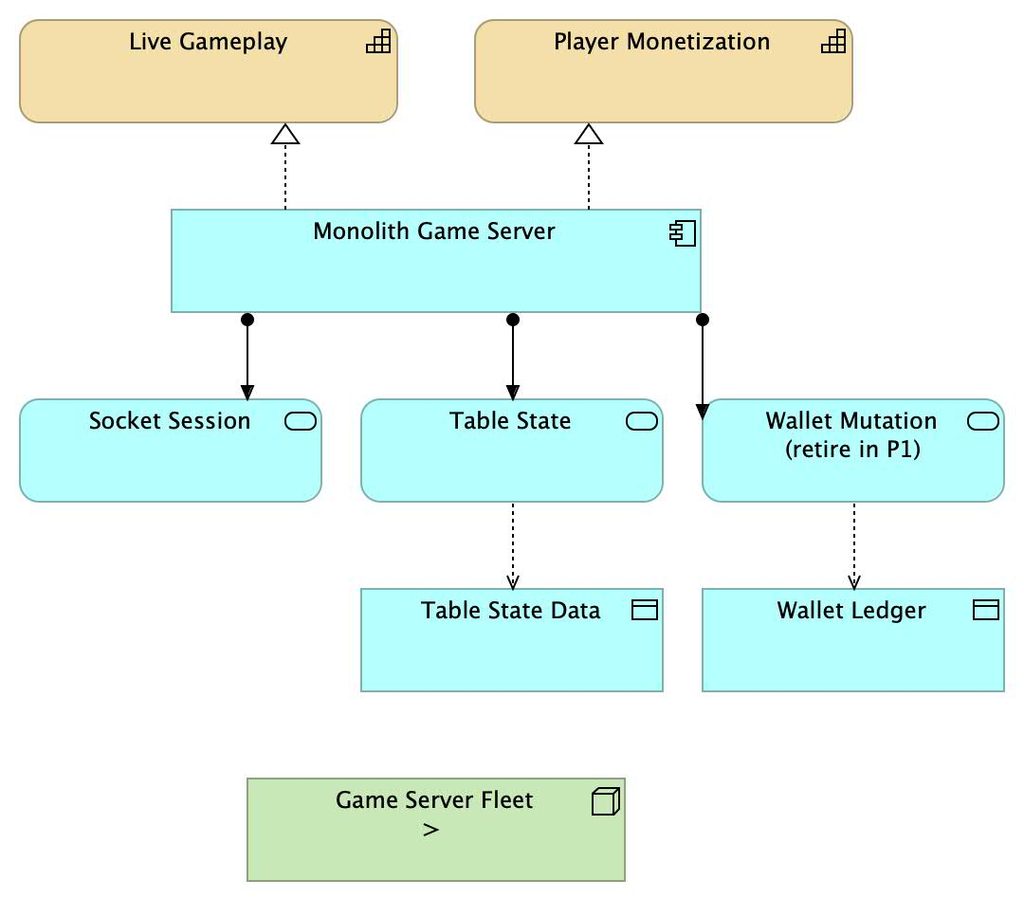
    Baseline (Plateau 0): one application component does too much.

    ArchiMate elementExample on the platform
    Business capabilityLive gameplay, Player monetization
    Business processJoin table → play hand → settle wallet
    Application componentMonolith Game Server
    Application serviceSocket session, Table state, Wallet mutation (all in one deployable)
    Data objectPlayer profile, Table state, Wallet ledger
    Technology nodeSingle JVM / process fleet behind a load balancer
    Artifactgame-server.jar (one binary, many responsibilities)

    The pain in EA language: gameplay hot path and money path share process, deployment, and failure domain. A spike in lobby traffic or a stuck wallet call can drag down live tables.

    This is not a drawing exercise. It is the baseline plateau every squad must agree on before “we already migrated” conversations start.

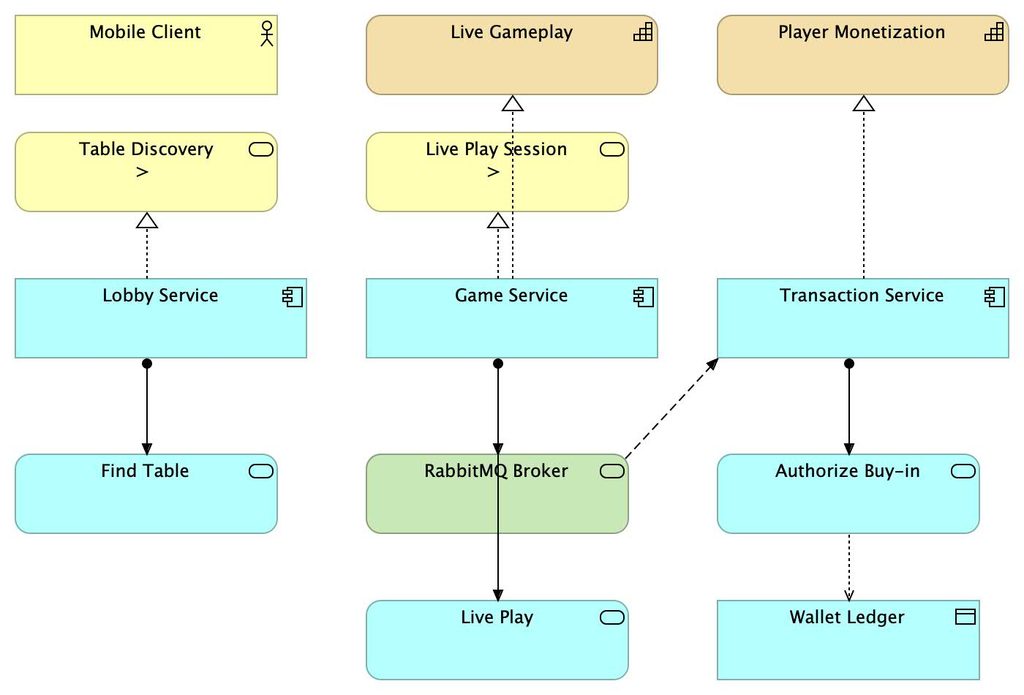
    Target: separate capabilities into application components with clear serving relationships — clients and other apps call services, not “the server.”

    Application componentOwnsApplication services (examples)
    Lobby ServiceMatchmaking, presenceFind table, Seat player
    Game ServiceLive session, table statePlay event, Broadcast state
    Transaction ServiceWallets, buy-in, payoutAuthorize buy-in, Settle hand
    Message Broker (infra)Async handoffPayment command queue

    Client pattern (from the real journey):

    REST (or HTTP API) to Lobby — door: find and join a table

    WebSocket to Game — room live play

    Broker between Game and Transactions — money off the gameplay hot path

    ArchiMate relationships to model explicitly:

    RelationshipMeaning in the migration
    ServingLobby Service serves Find table to the mobile client
    FlowGame events move between client and Game Service
    TriggeringBuy-in requested triggers a payment command
    AccessGame Service accesses table state; Transaction Service accesses ledger
    RealizationGame Service realizes Live gameplay capability

    The part people skip: plateaus and gaps

    Migration is not binary. ArchiMate’s Implementation & Migration viewpoint exists because Plateau 1 is where production actually lives.

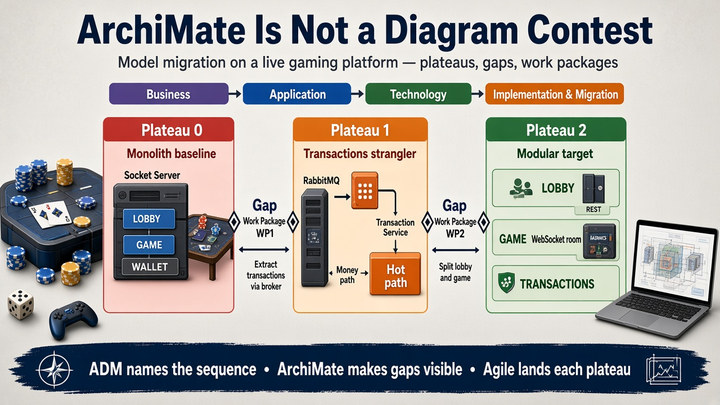
    Plateau 0 — Monolith (baseline)

    Everything in one component. Money and play in one failure domain.

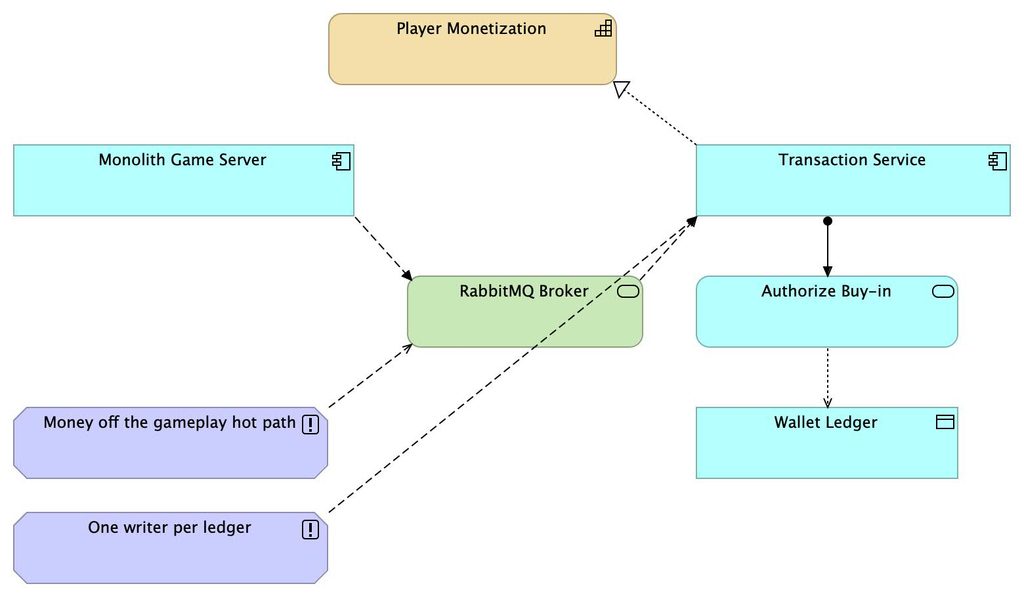
    Plateau 1 — Strangler: transactions extracted, monolith still plays

    Work package: Extract transaction module; route wallet commands via broker.

    What changesArchiMate modeling note
    New Transaction Service component appearsTarget element in Plateau 1
    Monolith loses wallet mutationGap: retire in-process wallet behavior
    RabbitMQ (or similar) as Technology serviceNew Flow between Game and Transactions
    Coexistence ruleMonolith still owns lobby + game; transactions own ledger writes

    Gap (Plateau 0 → 1):

    Duplicate wallet path — monolith code path must be decommissioned, not left “just in case”

    Data ownership — one writer to ledger (record in model + ADR)

    Operational owner ship — who runs the broker, queues, and DLQ

    This is the increment ADM + Agile articles describe transactions module first, live tables keep running.

    Plateau 2 — Lobby and game separated

    Work package: Split lobby matchmaking from game session; REST door + WebSocket room.

    GapWhy it matters
    Session handoffLobby assigns table; Game owns socket room
    Identity / session tokenModel Flow of “seat confirmed → connect to game shard”
    Scale independenceLobby scales on browse traffic; game scales on seated players

    Plateau 3 — Shard game fleet, containerize (optional further plateau)

    Aligns with the 200K concurrent journey: stateless game engines, externalized state, autoscale – another plateau, not a surprise Phase F slide.

    EA rule:Model every plateau you will actually run in production — not only baseline and dream target.

    What to put on the diagram (and what to leave off)

    Model these for migration

    Application components you will deploy separately

    Application services other teams call

    Flows that cross team boundaries (especially money)

    Plateaus with dates or release trains

    Gaps with named work packages and owners

    Principles as constraints (one writer per ledger, money off hot path)

    Do not model these (yet)

    Every class or microservice repo

    Every MQ topic name

    Full cloud networking on day one

    A perfect enterprise map that updates never

    ArchiMate should be just detailed enough that a squad can answer: Does my sprint fit the current plateau?

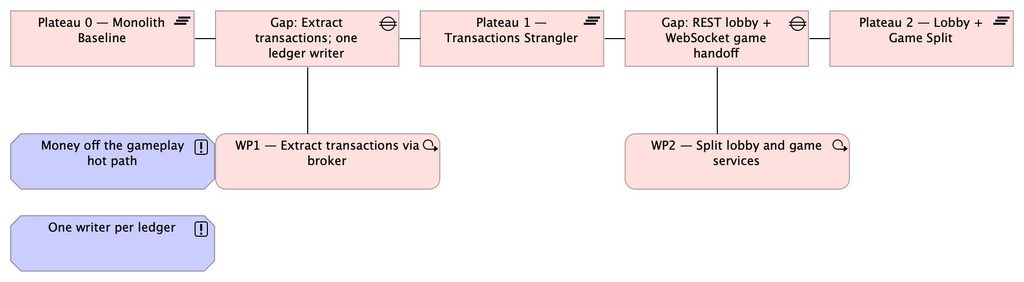
    Migration roadmap (Archi view 4)

    The implementation & Migration viewpoint is where ArchiMate earns its keep: Plateaus, Gaps, and Work Packages on one diagram — not a second poster that ignores today.

    ElementIn this model
    Plateau 0Monolith baseline
    Gap P0→P1Extract transactions; one ledger writer
    Work Package 1Broker + Transaction Service; retire in-process wallet
    Plateau 1Monolith (lobby+game) + Transaction Service
    Gap P1→P2REST lobby + WebSocket game handoff
    Work Package 2Split Lobby and Game services
    Plateau 2Lobby + Game + Transactions (target modular)

    In Archi (or BiZZdesign, Sparx), attach deliverables, stakeholders, and ADR links to each work package. The notation is standard the discipline is yours.

    ArchiMate × ADM × Agile (one line each)

    MethodRole in migration
    ADM Phase FNames migration planning as a first-class outcome
    ArchiMateMakes baseline / target / plateaus / gaps visible and debatable
    AgileDelivers one work package per increment with a demonstrable plateau

    Without ArchiMate (or an equivalent shared model), Agile ships features; with it, Agile ships plateau transitions the board can recognize.
    Anti-patterns ArchiMate should kill in migration reviews

    Target-state-only diagram — pretty future, lying about today

    Component per developer — boxes follow org chart, not behavior

    Missing broker — money path drawn as synchronous REST because it is easier to draw

    No gap — “we’ll switch over Friday” with no coexistence rules

    Plateau without owner — work package on a slide, nobody on-call

    ArchiMate as PDF export — model not connected to backlog or ADRs

    Rewriting the whole model every sprint — model plateaus, refine incrementally

    Migration modeling checklist (use in architecture reviews)

    1. Is baseline agreed? One monolith box is not enough — name services, data writers, and hot paths.

    2. Is target a plateau or a fantasy? Target without Plateau 1 is a poster.

    3. What is the next work package? One strangler slice — who owns it?

    4. What gap closes when it ships? Name behavior you stop doing in the old component.

    5. Where does money flow? If it is not on the diagram, it is still in the monolith.

    6. What is coexistence? Two paths may run briefly — model duration and decommission rule.

    7. Which capabilities are realized where? Gameplay vs monetization separation is strategic — show it.

    8. Does the squad’s sprint map to a plateau element? If not, why are we building it?

    If you can not answer these from the model, you are not ready to migrate. You are ready to argue in stand-up.

    Wrapping up

    ArchiMate is not a diagram contest. It is how Enterprise Architecture makes migration legible: baseline monolith, target modular platform, plateaus in between, gaps that close with real work packages.

    On a live gaming platform, that looked like:

    Plateau 0 — socket monolith: play, lobby, money in one place

    Plateau 1 — transactions strangler via broker; one writer to the ledger

    Plateau 2 — REST lobby + WebSocket game; money still off the hot path

    Later plateaus — shard, containerize, autoscale — same model, new gaps

    Use ArchiMate to stop six squads from drawing six truths. Use ADM to justify why migration is phased. Use Agile to land each plateau while players are still at the table.

    That is EA doing its job: map over slogans, plateaus over big-bang, shared model over private diagrams.

  • Build vs Buy vs Reuse

    Build vs Buy vs Reuse

    Enterprise architecture is full of technology debates that are really ownership debates.

    Do we buy a managed capability? Reuse something that already exists (open source or internal)? Or build the missing piece ourselves?

    Treated as slogans, those words start culture wars. Treated as an EA decision framework, they become a repeatable way to protect cost, time, and differentiation.

    This article is that framework when to choose build, when to choose buy, when to choose reuse.

    I will ground it with one example an offline segmentation engine that followed our Dynamic Real-Time Query Engine work so the guidance is not abstract. That example is illustrative, not the whole story. The same questions apply whether you are deciding on compute, messaging, identity, CI, observability, or a data platform.

    The example is evidence. The decision pattern is the article.

    The EA triangle, without the mythology

    Choice What it means in EA terms

    Buy Pay a vendor for a managed capability (product, platform, or cloud service). You buy outcomes and operating leverage and you buy their constraints and bill shape.

    Reuse Adopt capability that already exists: open source, an internal platform, a shared service. You do not reinvent the commodity.

    Build Create what you cannot get (or cannot afford / cannot customize) from buy or reuse alone — ideally the thinnest layer that unlocks fit.

    Mature architecture almost never picks only one forever. The skilled move is composition .

    Reuse the commodity engine.

    Buy when the managed premium is rational.

    Build only the control plane, integration, or scaling policy that makes the commodity fit your enterprise.

    That composition is what good EA should sound like in an architecture board on Spark, or on anything else.

    When to choose REUSE

    Choose reuse when the capability is commodity, proven, and not where you win in the market.

    Reuse when:

    The problem is already solved well by open source or an internal shared platform

    Differentiating on a from-scratch rewrite would be vanity, not strategy

    Standards, community, and hiring markets already exist around the tool

    You can accept the core abstraction (APIs, execution model) and invest above it

    Do not confuse reuse with do nothing. Reuse still needs governance versions, security, support model, upgrade ownership.

    One example (segmentation) Apache Spark was reuse. Offline segmentation needed distributed batch compute. Spark already owned that problem. Building a new engine would have been enterprise malpractice.

    EA ruleReuse what is commodity. Put architecture energy above it, not underneath it.

    When to choose BUY

    Choose buy when a vendor’s managed service is the fastest, safest path and the total cost of ownership (money + risk + headcount) beats building.

    When to choose BUILD

    Choose build when reuse gives you the core, buy is too expensive or too rigid, and a small, justified build creates enterprise fit.

    Build when

    You need customization the managed product will fight (discovery, scheduling policy, tenancy, warm-up, per-job limits).

    Build time is short relative to the ongoing buy premium.

    Build cost is defensible in payback (engineering spike vs years of platform fees).

    The build surface is thin runtime, scaler, adapter, control plane not a rewrite of the commodity.

    The capability sits on a critical path where vendor constraints become business constraints.

    Do not build when

    You are bored and want to re-implement Spark / Kafka / Kubernetes.

    The only argument is “we are smart enough”.

    Nobody will own upgrades, security, and 2 a.m. failures.

    Buy is only slightly expensive and your team is already overloaded.

    One example (segmentation):We built the runtime around reused Spark not Spark itself.

    Spark master on one EC2, IP published to consumers.

    Slaves as autoscaling container pods, joining via master IP / props on spin-up.

    Baseline around 2 workers, scale to N with demand.

    A custom scaler warm capacity ~5 minutes before job start min/max nodes per job.

    Delivery in about 10 days

    Ongoing cost far below the EMR path (10× difference for us)

    EA rule : Build the thinnest layer that turns commodity reuse into enterprise fit and only when payback and ownership are real.

    An enterprise decision checklist (use this in architecture reviews)

    Before the board debates tools, answer these in order:

    1. Is this differentiating or commodity?

    Commodity → prefer reuse (or buy a managed wrapper). Differentiating → may justify build.

    2. What exactly are we buying / reusing / building?

    Force precision. The engine, the managed platform, and your scaler/adapter are three different decisions.

    3. What is the 12–36 month bill for buy at our utilization?

    Include idle, minimum footprint, support, and growth. Compare to reuse + thin build.

    4. Can the managed option scale?

    Assume yes until proven otherwise then judge cost and control, not myths.

    5. What customization do we actually need?

    List behaviors buy cannot give cleanly.

    6. What is the smallest useful build, and how long will it take?

    If the answer is months with unclear owners, buy may win. If the answer is days with clear ownership, build can win.

    7. Who operates it after launch?

    No owner → do not build. Buy or reuse through a platform team that already exists.

    8. What is the exit / change cost?

    Buy lock-in, reuse upgrade debt, build maintenance pick the debt you can service.

    If you cannot answer these, you are not ready to choose. You are ready to argue.

    This is one application of the framework useful because it shows reuse, buy evaluation, and build in the same decision. Your next board topic might be messaging, identity, or CI the questions stay the same.

    How we got here real-time first, then offline

    The story does not start with Spark. It starts with real-time.

    We had already built a Dynamic Real-Time Query Engine a platform so CRM and marketing could understand player behavior the instant an event happened and act while the player was still on screen. Milliseconds, not nightly batch. Live segments, live treatments, a shared real-time data and query layer instead of bolting another third-party point tool onto CRM.

    I wrote that journey separately the Architecture Board decision to build a platform, the stack, the trade-offs. The short version for this article we built real-time segmentation capability in-house because existing vendor tools could not do what we needed at that latency and because buying our way out of every CRM gap was the wrong enterprise pattern.

    Then management asked the next question.

    Real-time covers the moment the player is on screen. The business also needed offline segmentation richer, heavier, historical, warehouse-scale segment computation that does not have to finish in milliseconds, but still has to be ours to operate and affordable to run. Campaigns, deeper behavioral cohorts, reconciliation-style and batch analytics workloads extend the segmentation story beyond the hot path.

    The pressure behind that ask was familiar to any EA review avoid huge cost from third-party vendors for yet another segmentation CDP-style capability we would rent forever. We had already proven we could own the real-time side. Extending to offline was the natural platform move if we chose build / buy / reuse correctly for batch compute, not by copying the real-time design blindly.

    So the sequence was deliberate:

    1. Build real-time(Dynamic Real-Time Query Engine) act in milliseconds stop depending on tools that were never designed for that window.

    2. Extend to offline management wants an offline segment engine for the work that is batch by nature.

    3. Apply build vs buy vs reuse on the offline runtime so we do not replace one vendor bill with another (or with EMR-scale spend) after we just escaped third-party lock-in on the real-time path.

    Offline was not a random Spark project. It was the batch half of a segmentation platform we were already committing to own.

    Context: what offline needed

    We needed an offline segmentation engine bursty batch work over historical and large-scale data, not live gameplay milliseconds. Spark was the right compute model for that half of the problem.

    Reuse

    Open-source Spark the engine. Commodity. Do not reinvent.

    Buy (evaluated)

    Amazon EMR managed Spark path. It can scale. For our usage, the billing model was ~10× a lean self-run option. That failed the EA cost test.

    Build (chosen for the thin layer)

    Built piece Why it was build, not buy

    Containerized Spark workers on a container service Control images, join. behavior, unit economics

    Master on EC2 with published IP(domain) Consumer discovery the way our enterprise clients needed

    Job-aware scaler |Warm ~5 mins before start; min/max nodes per job

    10-day delivery Build time low enough to justify vs ongoing EMR premium

    Outcome in EA language

    DecisionChoiceRationale
    Compute engineReuseSpark is commodity
    Managed Spark platformDo not buy (this case)Bill ~10× despite scaling capability
    Autoscaling runtime + scalerBuildCustomization + short build + cost payback

    How that built runtime worked

    1. Master on EC2 — stable control plane IP(domain) published to job submitters / consumers.

    2. Workers as containers— pods scale out on spin-up they receive master IP. Spark props and associate with the master.

    3. Scaler — warm workers 5 minutes before scheduled jobs each job declares min and max nodes.

    4. Economics — sit near a small floor (often 2 workers), rise to N when the job needs it.

    Build was scoped: runtime and policy, not a science project.

    The same triangle elsewhere (same rules, different topics)

    Once the framework is clear, you can map it onto other enterprise decisions without changing the logic:

    DomainTypical reuseTypical buy questionTypical thin build
    MessagingRabbitMQ / Kafka (OSS)Managed broker / streamingRouting policies, CDC bridges, consumer platforms
    Data / analyticsSpark, Flink, warehouse enginesEMR, serverless Spark, SaaS BIJob-aware scalers, governance adapters
    IdentityOIDC / standard protocolsIdP / IAM suitesEnterprise-specific policy and integration
    CI / deliveryJenkins / GitHub Actions runners patternsFully managed CIInternal pipelines and quality gates
    ObservabilityPrometheus / OpenTelemetryVendor APM suitesCardinality controls, standard labels, routing

    You will not always land on “reuse + thin build.” Sometimes buy wins cleanly. Sometimes pure reuse on an internal platform is enough. The point of EA is to decide deliberately, using one consistent test not to copy the Spark outcome onto every domain.

    Anti-patterns enterprise architecture should stop

    Buy everything— hides a bad bill behind a brand logo

    Build everything — confuses engineering pride with strategy

    Reuse means free — ignores upgrade, CVE, and ownership cost

    It can’t scale” as a buy dismissal — often false check the invoice instead

    Building the engine instead of the adapter — rewriting Spark/Kafka/K8s is rarely EA

    No payback math — if you cannot compare a short build to a long managed premium, you are guessing

    One example = one dogma a good Spark decision is not a mandate to avoid managed services forever

    Closing: the EA stance

    Reuse when it is commodity.

    Buy when the managed operating model and the bill fit.

    Build when a short, owned, thin layer unlocks customization and cost the vendor will not give you.

    One example made that tangible for us: after we built a real-time query / segmentation engine in-house, management wanted to extend to offline to avoid another wave of third-party vendor cost. For that offline segment engine we reused Spark, skipped EMR on a 10× bill (even though EMR can scale), and built a job-aware autoscaling fabric in 10 days with warm-up and per-job min/max.

    Use the example to understand the pattern. Use the checklist on the next decision whatever the domain.

    That is enterprise architecture doing its job: fit over fashion, composition over slogans, framework over single-story dogma.

    If you sit on an architecture board what question do you ask first differentiating vs commodity, or which logo is trending? Drop a comment.