Enterprise architecture is full of technology debates that are really ownership debates.
Do we buy a managed capability? Reuse something that already exists (open source or internal)? Or build the missing piece ourselves?
Treated as slogans, those words start culture wars. Treated as an EA decision framework, they become a repeatable way to protect cost, time, and differentiation.
This article is that framework when to choose build, when to choose buy, when to choose reuse.
I will ground it with one example an offline segmentation engine that followed our Dynamic Real-Time Query Engine work so the guidance is not abstract. That example is illustrative, not the whole story. The same questions apply whether you are deciding on compute, messaging, identity, CI, observability, or a data platform.
The example is evidence. The decision pattern is the article.
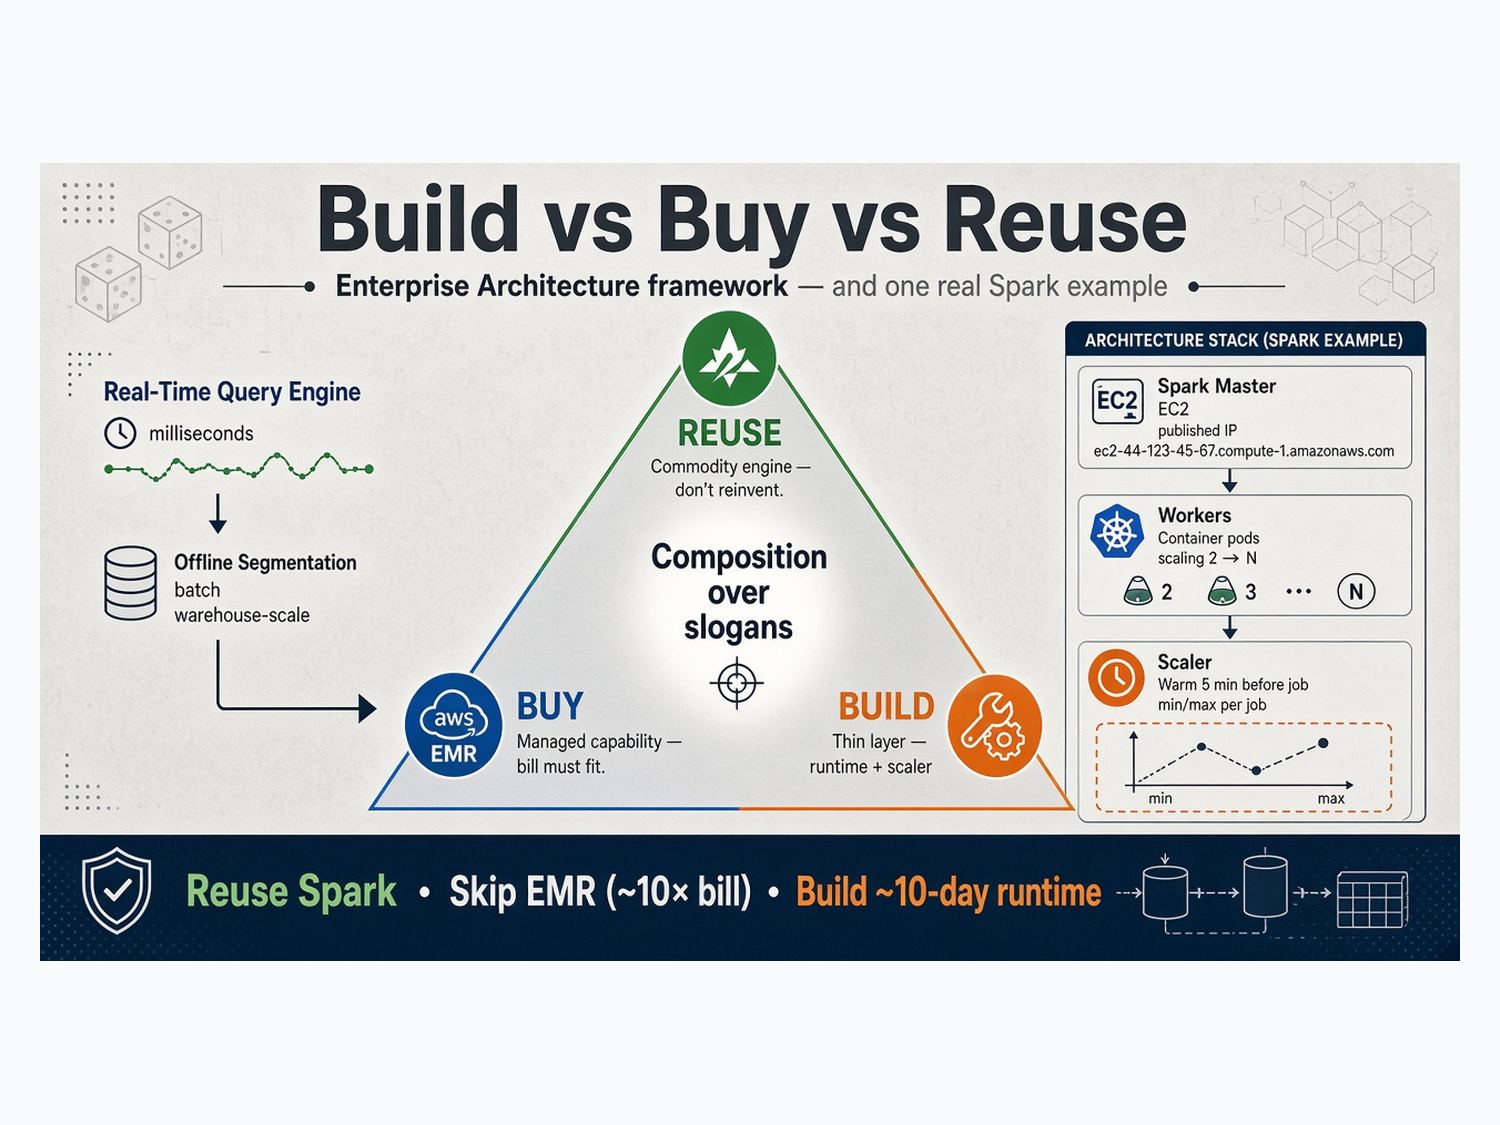
The EA triangle, without the mythology
Choice What it means in EA terms
Buy Pay a vendor for a managed capability (product, platform, or cloud service). You buy outcomes and operating leverage and you buy their constraints and bill shape.
Reuse Adopt capability that already exists: open source, an internal platform, a shared service. You do not reinvent the commodity.
Build Create what you cannot get (or cannot afford / cannot customize) from buy or reuse alone — ideally the thinnest layer that unlocks fit.
Mature architecture almost never picks only one forever. The skilled move is composition .
Reuse the commodity engine.
Buy when the managed premium is rational.
Build only the control plane, integration, or scaling policy that makes the commodity fit your enterprise.
That composition is what good EA should sound like in an architecture board on Spark, or on anything else.
When to choose REUSE
Choose reuse when the capability is commodity, proven, and not where you win in the market.
Reuse when:
The problem is already solved well by open source or an internal shared platform
Differentiating on a from-scratch rewrite would be vanity, not strategy
Standards, community, and hiring markets already exist around the tool
You can accept the core abstraction (APIs, execution model) and invest above it
Do not confuse reuse with do nothing. Reuse still needs governance versions, security, support model, upgrade ownership.
One example (segmentation) Apache Spark was reuse. Offline segmentation needed distributed batch compute. Spark already owned that problem. Building a new engine would have been enterprise malpractice.
EA rule: Reuse what is commodity. Put architecture energy above it, not underneath it.
When to choose BUY
Choose buy when a vendor’s managed service is the fastest, safest path and the total cost of ownership (money + risk + headcount) beats building.
When to choose BUILD
Choose build when reuse gives you the core, buy is too expensive or too rigid, and a small, justified build creates enterprise fit.
Build when
You need customization the managed product will fight (discovery, scheduling policy, tenancy, warm-up, per-job limits).
Build time is short relative to the ongoing buy premium.
Build cost is defensible in payback (engineering spike vs years of platform fees).
The build surface is thin runtime, scaler, adapter, control plane not a rewrite of the commodity.
The capability sits on a critical path where vendor constraints become business constraints.
Do not build when
You are bored and want to re-implement Spark / Kafka / Kubernetes.
The only argument is “we are smart enough”.
Nobody will own upgrades, security, and 2 a.m. failures.
Buy is only slightly expensive and your team is already overloaded.
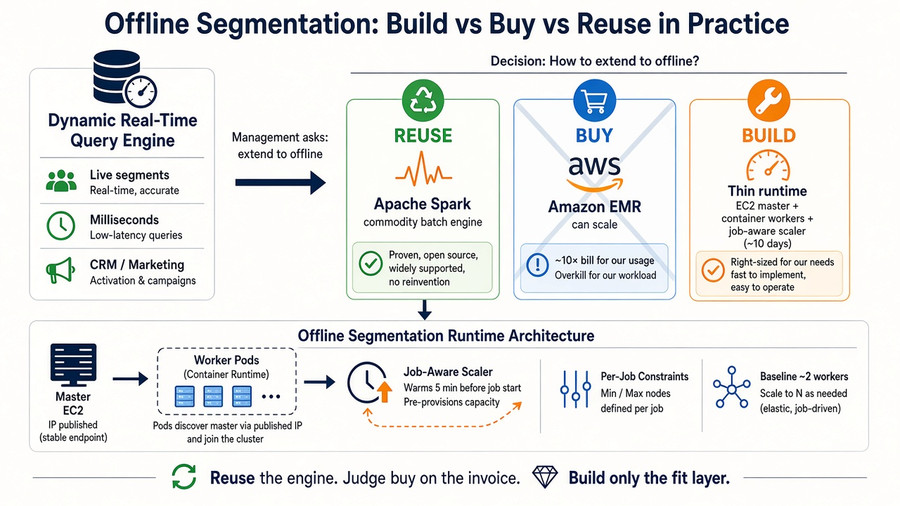
One example (segmentation):We built the runtime around reused Spark not Spark itself.
Spark master on one EC2, IP published to consumers.
Slaves as autoscaling container pods, joining via master IP / props on spin-up.
Baseline around 2 workers, scale to N with demand.
A custom scaler warm capacity ~5 minutes before job start min/max nodes per job.
Delivery in about 10 days
Ongoing cost far below the EMR path (10× difference for us)
EA rule : Build the thinnest layer that turns commodity reuse into enterprise fit and only when payback and ownership are real.
An enterprise decision checklist (use this in architecture reviews)
Before the board debates tools, answer these in order:
1. Is this differentiating or commodity?
Commodity → prefer reuse (or buy a managed wrapper). Differentiating → may justify build.
2. What exactly are we buying / reusing / building?
Force precision. The engine, the managed platform, and your scaler/adapter are three different decisions.
3. What is the 12–36 month bill for buy at our utilization?
Include idle, minimum footprint, support, and growth. Compare to reuse + thin build.
4. Can the managed option scale?
Assume yes until proven otherwise then judge cost and control, not myths.
5. What customization do we actually need?
List behaviors buy cannot give cleanly.
6. What is the smallest useful build, and how long will it take?
If the answer is months with unclear owners, buy may win. If the answer is days with clear ownership, build can win.
7. Who operates it after launch?
No owner → do not build. Buy or reuse through a platform team that already exists.
8. What is the exit / change cost?
Buy lock-in, reuse upgrade debt, build maintenance pick the debt you can service.
If you cannot answer these, you are not ready to choose. You are ready to argue.
This is one application of the framework useful because it shows reuse, buy evaluation, and build in the same decision. Your next board topic might be messaging, identity, or CI the questions stay the same.
How we got here real-time first, then offline
The story does not start with Spark. It starts with real-time.
We had already built a Dynamic Real-Time Query Engine a platform so CRM and marketing could understand player behavior the instant an event happened and act while the player was still on screen. Milliseconds, not nightly batch. Live segments, live treatments, a shared real-time data and query layer instead of bolting another third-party point tool onto CRM.
I wrote that journey separately the Architecture Board decision to build a platform, the stack, the trade-offs. The short version for this article we built real-time segmentation capability in-house because existing vendor tools could not do what we needed at that latency and because buying our way out of every CRM gap was the wrong enterprise pattern.
Then management asked the next question.
Real-time covers the moment the player is on screen. The business also needed offline segmentation richer, heavier, historical, warehouse-scale segment computation that does not have to finish in milliseconds, but still has to be ours to operate and affordable to run. Campaigns, deeper behavioral cohorts, reconciliation-style and batch analytics workloads extend the segmentation story beyond the hot path.
The pressure behind that ask was familiar to any EA review avoid huge cost from third-party vendors for yet another segmentation CDP-style capability we would rent forever. We had already proven we could own the real-time side. Extending to offline was the natural platform move if we chose build / buy / reuse correctly for batch compute, not by copying the real-time design blindly.
So the sequence was deliberate:
1. Build real-time(Dynamic Real-Time Query Engine) act in milliseconds stop depending on tools that were never designed for that window.
2. Extend to offline management wants an offline segment engine for the work that is batch by nature.
3. Apply build vs buy vs reuse on the offline runtime so we do not replace one vendor bill with another (or with EMR-scale spend) after we just escaped third-party lock-in on the real-time path.
Offline was not a random Spark project. It was the batch half of a segmentation platform we were already committing to own.
Context: what offline needed
We needed an offline segmentation engine bursty batch work over historical and large-scale data, not live gameplay milliseconds. Spark was the right compute model for that half of the problem.
Reuse
Open-source Spark the engine. Commodity. Do not reinvent.
Buy (evaluated)
Amazon EMR managed Spark path. It can scale. For our usage, the billing model was ~10× a lean self-run option. That failed the EA cost test.
Build (chosen for the thin layer)
Built piece Why it was build, not buy
Containerized Spark workers on a container service Control images, join. behavior, unit economics
Master on EC2 with published IP(domain) Consumer discovery the way our enterprise clients needed
Job-aware scaler |Warm ~5 mins before start; min/max nodes per job
10-day delivery Build time low enough to justify vs ongoing EMR premium
Outcome in EA language
| Decision | Choice | Rationale |
|---|---|---|
| Compute engine | Reuse | Spark is commodity |
| Managed Spark platform | Do not buy (this case) | Bill ~10× despite scaling capability |
| Autoscaling runtime + scaler | Build | Customization + short build + cost payback |
How that built runtime worked
1. Master on EC2 — stable control plane IP(domain) published to job submitters / consumers.
2. Workers as containers— pods scale out on spin-up they receive master IP. Spark props and associate with the master.
3. Scaler — warm workers 5 minutes before scheduled jobs each job declares min and max nodes.
4. Economics — sit near a small floor (often 2 workers), rise to N when the job needs it.
Build was scoped: runtime and policy, not a science project.
The same triangle elsewhere (same rules, different topics)
Once the framework is clear, you can map it onto other enterprise decisions without changing the logic:
| Domain | Typical reuse | Typical buy question | Typical thin build |
|---|---|---|---|
| Messaging | RabbitMQ / Kafka (OSS) | Managed broker / streaming | Routing policies, CDC bridges, consumer platforms |
| Data / analytics | Spark, Flink, warehouse engines | EMR, serverless Spark, SaaS BI | Job-aware scalers, governance adapters |
| Identity | OIDC / standard protocols | IdP / IAM suites | Enterprise-specific policy and integration |
| CI / delivery | Jenkins / GitHub Actions runners patterns | Fully managed CI | Internal pipelines and quality gates |
| Observability | Prometheus / OpenTelemetry | Vendor APM suites | Cardinality controls, standard labels, routing |
You will not always land on “reuse + thin build.” Sometimes buy wins cleanly. Sometimes pure reuse on an internal platform is enough. The point of EA is to decide deliberately, using one consistent test not to copy the Spark outcome onto every domain.
Anti-patterns enterprise architecture should stop
Buy everything— hides a bad bill behind a brand logo
Build everything — confuses engineering pride with strategy
Reuse means free — ignores upgrade, CVE, and ownership cost
It can’t scale” as a buy dismissal — often false check the invoice instead
Building the engine instead of the adapter — rewriting Spark/Kafka/K8s is rarely EA
No payback math — if you cannot compare a short build to a long managed premium, you are guessing
One example = one dogma a good Spark decision is not a mandate to avoid managed services forever
Closing: the EA stance
Reuse when it is commodity.
Buy when the managed operating model and the bill fit.
Build when a short, owned, thin layer unlocks customization and cost the vendor will not give you.
One example made that tangible for us: after we built a real-time query / segmentation engine in-house, management wanted to extend to offline to avoid another wave of third-party vendor cost. For that offline segment engine we reused Spark, skipped EMR on a 10× bill (even though EMR can scale), and built a job-aware autoscaling fabric in 10 days with warm-up and per-job min/max.
Use the example to understand the pattern. Use the checklist on the next decision whatever the domain.
That is enterprise architecture doing its job: fit over fashion, composition over slogans, framework over single-story dogma.
If you sit on an architecture board what question do you ask first differentiating vs commodity, or which logo is trending? Drop a comment.