Enterprise Architecture for a multi-source investigation assistant — back office, Grafana logs, and transaction summaries
Support, fraud ops, and back office do not ask questions in SQL.
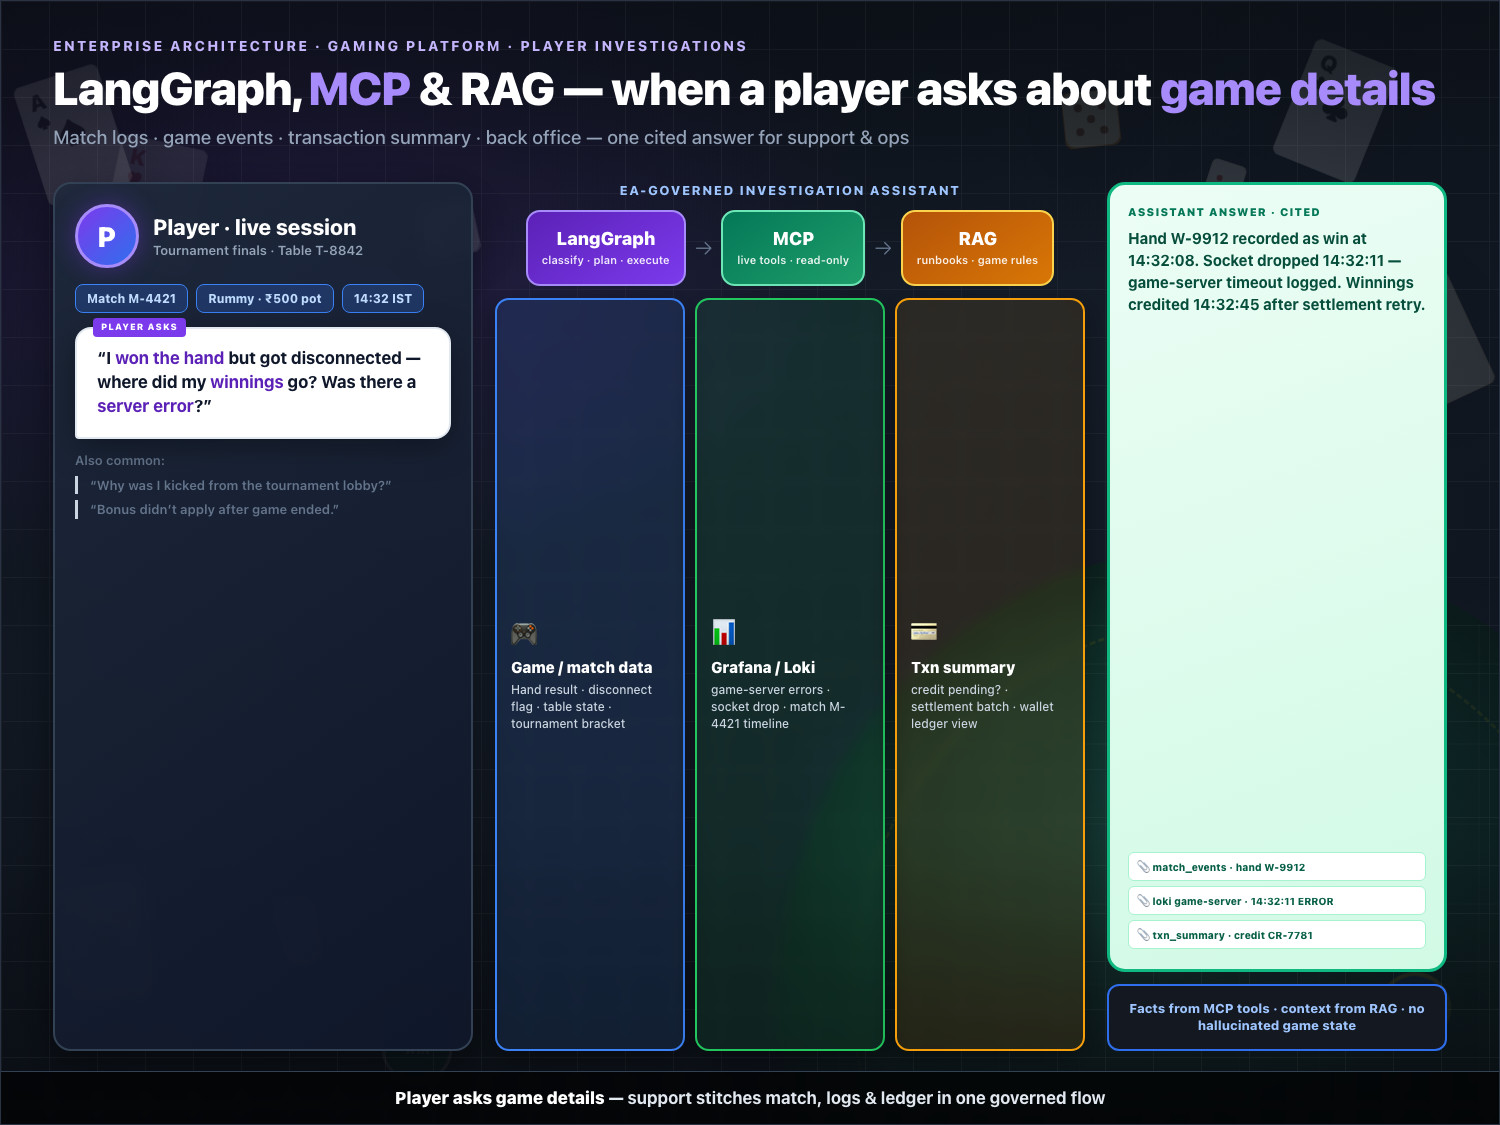
They ask: “Player had a failed withdrawal after a win — what happened?”
That answer lives in three places at once: a transaction summary in the database, error and payment logs in Grafana, and account flags in back office.
Before we built anything, the workflow was three tabs, three teams, twenty minutes — and sometimes a wrong conclusion because nobody stitched the timeline together.
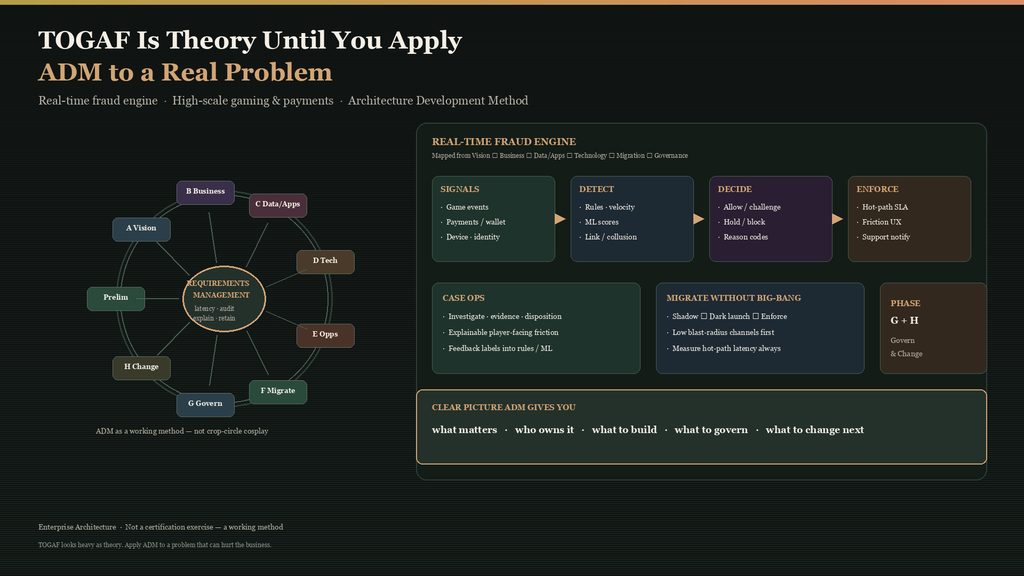
This article maps how we designed a player investigation assistant using LangGraph (orchestration), MCP (tool boundaries to enterprise systems), and RAG (context, not truth) — through Enterprise Architecture and the Architecture Development Method (ADM).
It is not a tutorial on “hello world RAG.” It is how an EA team decides what the model may know, what it must prove via tools, and what must never leave your boundary.
Why this is an EA problem, not a “chatbot” project
Most LLM demos collapse three different concerns into one prompt:
| Concern | Who cares | EA question |
|---|---|---|
| Facts | Finance, fraud, compliance | Where is the system of record? |
| Evidence | SRE, ops, investigators | What did the platform log at time T? |
| Meaning | Support, new analysts | What does status FAILED vs HELD imply? |
If you let the model invent facts, you fail audit.
If you force analysts to write joins across Grafana and OLTP, you fail operations.
If you embed live transactions in a vector DB, you fail security and freshness.
Enterprise Architecture’s job here is to draw the seams: orchestration, tools, retrieval, governance — before anyone picks a model vendor.
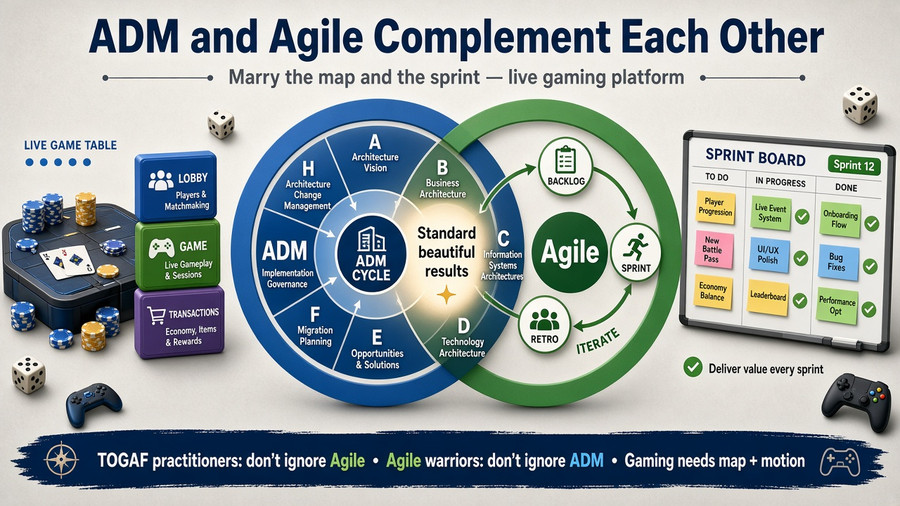
ADM in one sentence (before we use it)
ADM moves from “why are we changing? to “what must be true in business, data, applications, and technology?” to “how do we deliver and govern?”
For a player-query assistant, the phases below are the ones that mattered. You do not need every TOGAF artifact. You need every phase question answered well enough to decide.
Preliminary Phase — principles before prompts
ADM question:What rules does this capability obey, regardless of model?
We fixed these up front:
Facts from tools, not from embeddings — balances, txn states, and log lines come from MCP tools with audit trails.
Read-only by default — no assistant-driven writes to wallet or account state on v1.
PII minimization — mask in answers; log tool calls, not full payloads, where policy requires.
Latency budget — internal ops tool, not player-facing; still cap total round-trips (parallel tools where safe).
Single player context — ambiguous `player_id` → clarify or fail closed; never guess across accounts.
Reuse enterprise sources — transaction summary DB, existing Grafana/Loki, back-office APIs — no shadow “assistant database” of player truth.
Without Preliminary, you get a clever demo that compliance will shut down in week two.
Phase A — Architecture Vision: the pain in business language
ADM question: What problem are we solving, for whom, and what does success look like?
Drivers
Investigation time for payment and gameplay issues — too many handoffs
Inconsistent answers when support, fraud, and back office each query different systems
Peak load on senior staff — “only Maria knows which Grafana dashboard”
Regulatory and audit pressure — explainable answers with source citations
Vision (shape we aligned on)
An internal assistant that answers player investigation questions by orchestrating read-only access to transaction summaries, observability logs, and back-office context — with cited sources, bounded tools, and human escalation when confidence is low.
Stakeholders
| Stakeholder | Primary concern |
|---|---|
| Support / CS | Faster resolution; plain-language answers; escalation path |
| Fraud ops | Cited evidence; no hallucinated txn states; audit trail |
| Back office | Correct account flags; scoped fields; no bulk export |
| SRE / Platform | Log query limits; label discipline; no Grafana overload |
| Finance / Payments | Txn summary as SoR; read-only; reconciliation-friendly |
| EA / Risk / Legal | PII boundaries; model governance; build vs buy clarity |
Phase A succeeds when stakeholders argue about workflow and risk, not about “which LLM is coolest.”
Phase B — Business Architecture: what “investigation” actually means
ADM question: What capabilities must exist?
| Capability | Owner | Notes |
|---|---|---|
| Intent understanding | Platform / EA-governed | Classify: payment, gameplay, bonus, KYC, generic |
| Evidence retrieval | SRE + data platform | Time-bounded log queries via Grafana/Loki |
| Financial facts | Payments / data | Transaction summary — parameterized queries only |
| Account context | Back office | Status, flags, eligibility — scoped API |
| Synthesis | Assistant layer | Timeline + plain language + citations |
| Escalation | Human queue | Low confidence, conflicting tools, policy edge cases |
The business capability is investigation throughput with auditability — not “chat.”
Phase C — Data Architecture: three truths, one timeline
ADM question: What data may the assistant use, and how fresh must it be?
Systems of record (tools only)
1. Transaction summary store — deposits, withdrawals, bets, settlements; aggregated for investigation (not raw ledger replay on every question).
2. Observability stack — Grafana → Loki (or equivalent); service labels, trace IDs, payment pipeline errors.
3. Back office — player profile, verification state, bonus blocks, responsible-gaming flags.
RAG corpus (context only)
Embed and retrieve:
-Schema and enum docs — what `WITHDRAWAL_FAILED` means vs `PENDING_REVIEW`
Runbooks — “if withdrawal failed, check payment gateway logs then settlement batch”
Playbooks — escalation paths, jurisdiction notes
ADR snippets — e.g. one-writer-per-ledger, fail-open vs fail-closed boundaries
Do not RAG: live rows, full log streams, or exports of player PII.
| RAG (context) | MCP tools (truth) | Never embed |
|---|---|---|
| Column meanings; status enums | Live txn rows from summary views | Full log streams |
| Investigation runbooks | Grafana/Loki query results | PII exports for retrieval |
| ADR / policy snippets | Back-office API responses | Credentials or raw SQL access |
That split is the most important data decision in the whole system.
Phase D — Technology Architecture: LangGraph, MCP, RAG roles
ADM question: How do components interact under load and governance?
LangGraph — orchestration, not magic
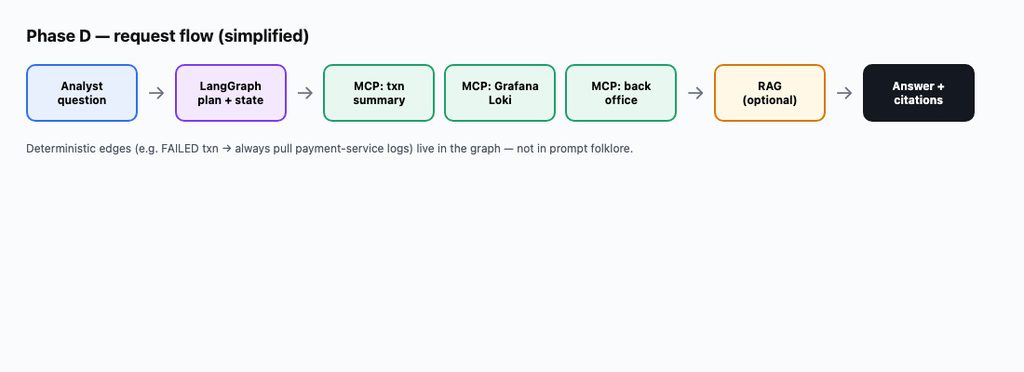
LangGraph models investigation as a state machine, not one-shot completion:
User question
  → classify intent + extract entities (player_id, time window, txn id)
  → plan tools (which sources, in what order)
  → execute tools (parallel where independent)
  → reconcile (timeline merge, conflict detection)
  → answer (cited) OR escalate
Why graph, not chain: investigations branch. A failed withdrawal triggers log pull ±5 minutes and txn lookup and back-office hold flags. Some paths are deterministic (“if txn status = FAILED, always query payment-service logs”) — encoded as edges, not left to model improvisation.
Why LangGraph? (the ARB decision)
Player investigations are stateful, branching, and audit-sensitive. We needed orchestration we could diagram, test, and govern — not a chatbot improvising across money, match state, and logs.
| Reason | What it buys you in production |
|---|---|
| Explicit state | player_id, time window, tool results, confidence — in graph state, not buried in chat history |
| Branching flows | Payment vs gameplay vs bonus → different tool paths without prompt folklore |
| Deterministic edges | “FAILED txn → always query payment-service logs ±5m” — code in the graph, not model guesswork |
| Parallel tools | Txn summary + Grafana + back office at once, with a hard cap (e.g. 3 concurrent MCP calls) |
| Debuggable | “Why did it escalate?” → trace nodes and tool outputs, not decode a 40k-token prompt |
| Governance-friendly | ARB reviews a flow diagram; Phase H versions edges when payment rails or log labels change |
| Human-in-the-loop | Natural escalation node when tools conflict or confidence is low |
What we rejected:
| Alternative | Why not |
|---|---|
| Single LLM + mega-prompt | Hallucinated txn state; no audit trail; ungovernable |
| Linear chain (A → B → C) | Cannot branch; hard to encode conditional investigation playbooks |
| Fully autonomous agent | Unacceptable risk on wallet / account paths for v1 |
| Vendor “AI ops” suite only | Poor fit to game events, custom back office, Grafana label discipline |
| Dashboards only | Visibility without synthesis and citations across three systems |
EA one-liner: LangGraph and deterministic playbooks — not fully autonomous agents on money paths. LangGraph orchestrates when to call tools; MCP defines how; RAG supplies context — not truth.
MCP — one protocol, many enterprise boundaries
Model Context Protocol gives each data source a tool server with a narrow contract:
| MCP server | Responsibility | Guardrails |
|---|---|---|
| transaction_summary | Parameterized reads on summary tables / views | Read-only role; row limits; timeouts |
| grafana_loki | LogQL with enforced labels | Max time range; service allowlist |
| back_office | REST for player context | Field-level auth; no bulk export |
MCP is EA-friendly: it is integration with boundaries — the same conversation you would have about REST vs event bus, but oriented to agent tool access.
Rejected alternative: one mega-prompt with DB credentials — fast to demo, impossible to govern.
RAG — explains; tools prove
RAG answers: “What should an analyst check next?”
MCP answers: What actually happened to player X at 14:32?”
Mixing them -e.g. embedding yesterday’s txn export — creates stale truth. ADM Phase C exists to prevent that.
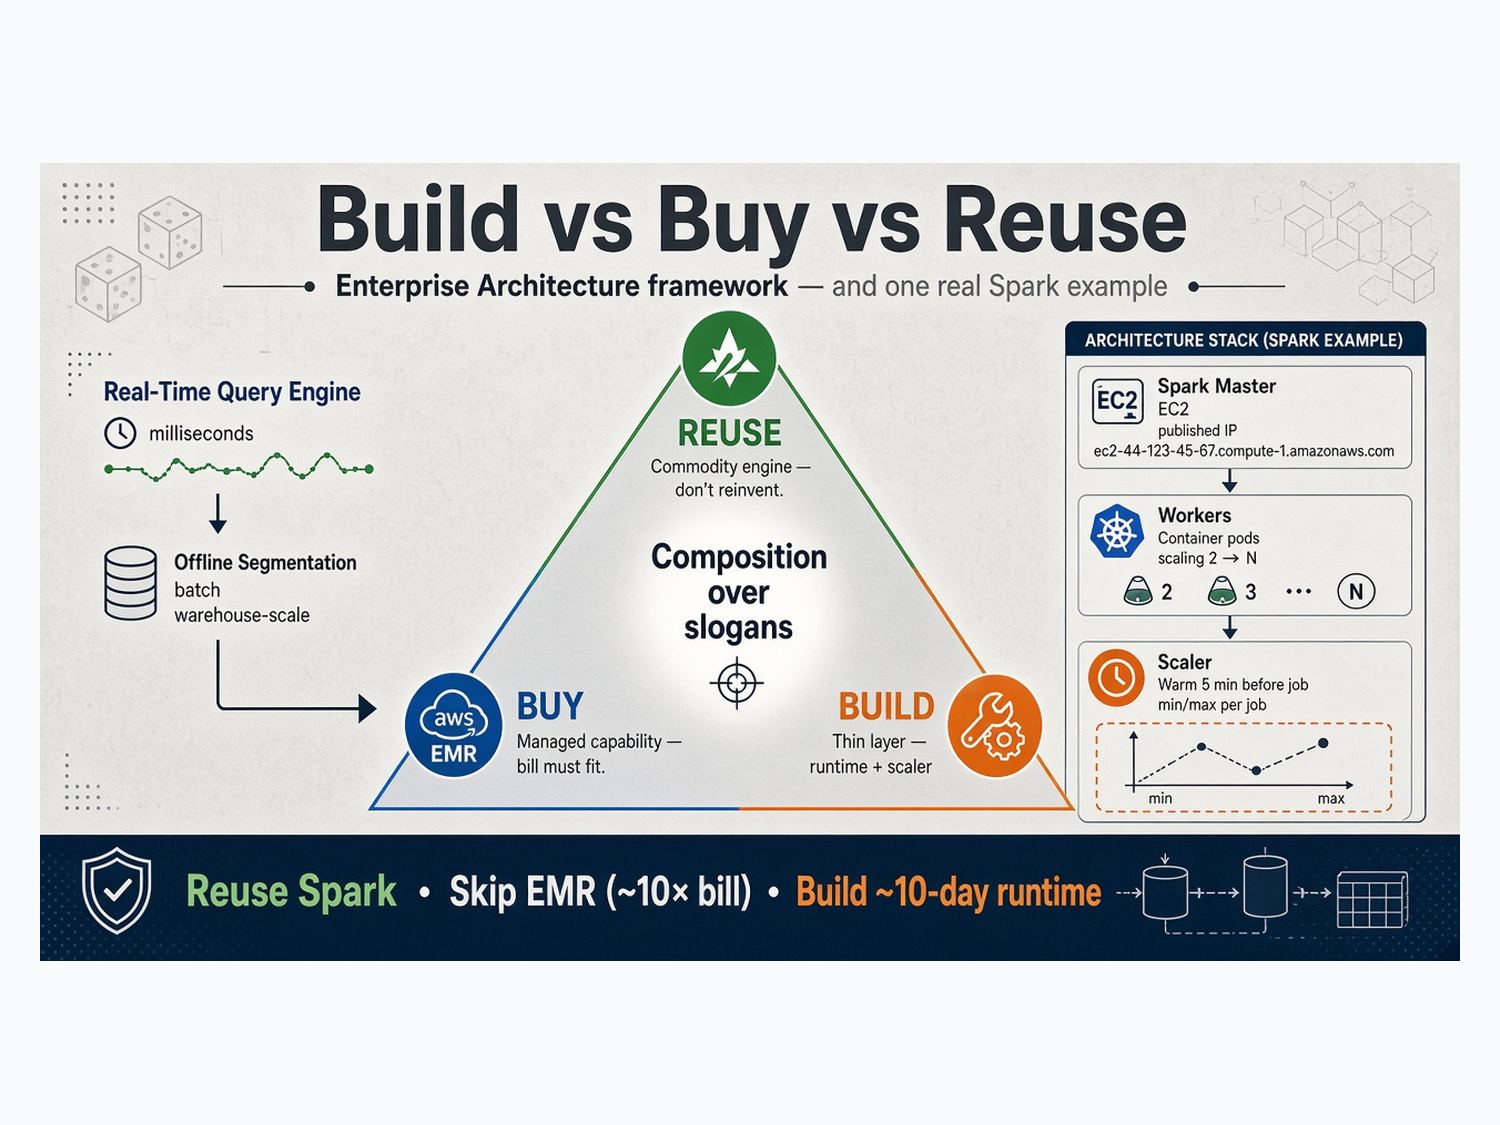
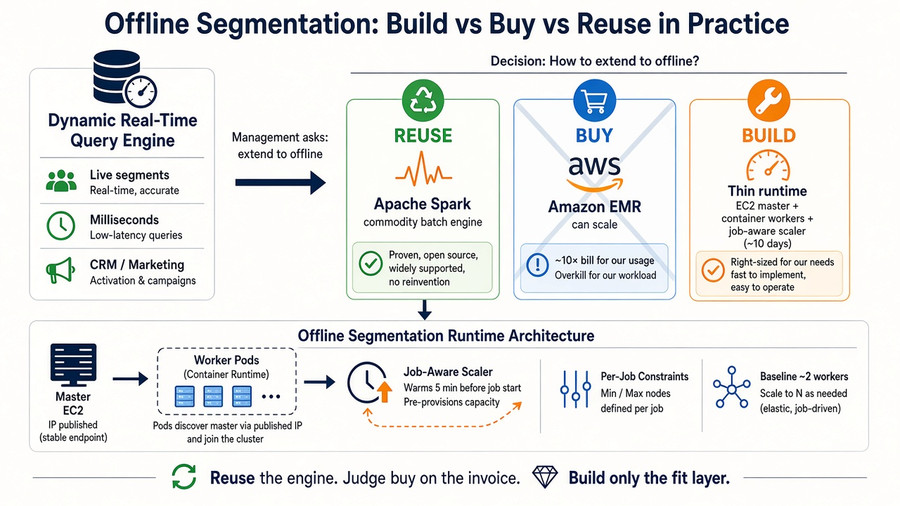
Phase E — Opportunities & Solutions: build vs buy vs reuse
| Layer | Choice | Rationale |
|---|---|---|
| LLM | Buy (API) or reuse (enterprise gateway) | Commodity; govern via gateway, keys, logging |
| Orchestration | Reuse LangGraph | Explicit state; debuggable flows |
| Tool wire-up | Reuse MCP | Standard tool surface; per-system servers |
| Vector store | Reuse (managed or internal) | Only for docs/runbooks — small corpus |
| Investigation UX | Build thin | Slack/Teams or internal portal; your audit hooks |
| Txn / logs / back office | Reuse existing | Never duplicate player truth for the assistant |
EA rule: Build the control plane and investigation workflow. Reuse every system of record.
This mirrors how we treated RTQE (platform, not CRM patch) and offline segmentation (Spark reuse, thin control plane) — same triangle, new surface.
Phase F — Migration: pilot without betting the bank
ADM question: How do we land safely?
1. Read-only pilot — support tier-2 only; predefined question templates + free text
2. Golden questions — 50 real (anonymized) investigations with expected citations
3. Shadow mode — assistant suggests; human executes until accuracy threshold
4. Expand intents— payment → bonus → gameplay → KYC
5. Metrics — time-to-resolution, escalation rate, tool error rate, citation coverage
No big-bang “replace every dashboard.” Strangler fig on workflow, not infrastructure.
Phase G — Implementation governance: ARB decisions that stuck
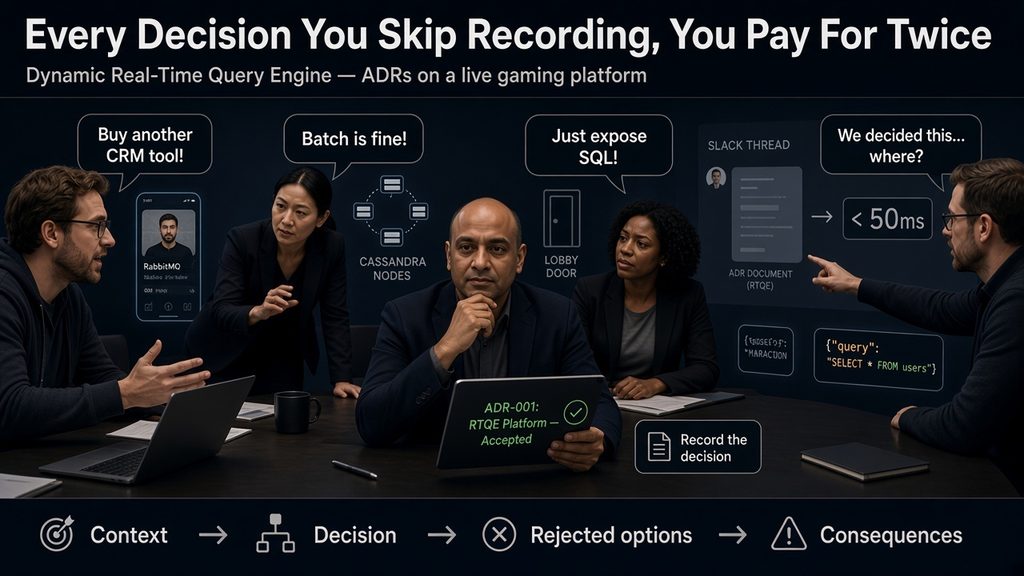
ADR-008: Player investigation assistant — LangGraph  orchestration, MCP tools, RAG for context only

Status: Accepted
Date: 03/01/2026
Deciders: Architecture Board, Support Ops, Fraud, Payments, SRE, Data Platform, Risk

Context

Support, fraud ops, and back office investigate player issues by manually querying transaction summaries, Grafana/Loki logs, and back-office APIs. Answers are slow, inconsistent, and hard to audit. A generic “chat with your data” approach risks hallucinated financial facts and unbounded database access.

Decision

Build an internal player investigation assistant:

 LangGraph— stateful orchestration (classify → plan → execute tools → reconcile → answer or escalate). Chosen over linear chains and one-shot prompts because investigations branch (payment vs gameplay vs bonus), require explicit state for audit, and need deterministic edges (e.g. FAILED txn → always pull payment-service logs) that ARB can diagram and version in Phase H
MCP servers — one bounded tool surface per system of record:
 `transaction_summary` — read-only parameterized queries on summary views
  `grafana_loki` — time-bounded LogQL with service allowlist
  `back_office` — scoped REST for account flags and context
RAG — embed docs only (schema, enums, runbooks, ADR snippets); never live txn rows or log streams
Citations required — factual claims must reference tool output ids
Fail closed on ambiguous `player_id` or conflicting tool results

Consequences

Positive: Faster investigations; consistent citations; reusable MCP servers for future automations; clear security boundary (tools vs retrieval).

Negative: LangGraph flow maintenance; MCP server ownership per domain team; golden-question regression suite required on model changes.

Obligations: No free-form SQL from the model; quarterly access review; version MCP schemas when summary views change; shadow mode before full rollout.

 Alternatives considered

| Alternative | Why rejected |
|-------------|--------------|
| Single prompt with DB + Grafana credentials | Ungovernable; audit nightmare |
| RAG over exported txn/log snapshots | Stale truth; PII surface area |
| Buy vendor “AI ops” suite only | Poor fit to gaming txn + custom back office; lock-in |
| Dashboards only | Solves visibility, not synthesis and audit trail |
| Autonomous agent with write tools | Unacceptable risk on wallet/account paths for v1 |
1. No free-form SQL from the model — only named queries / views behind MCP
2. Citations required — every factual claim links to tool output id
3. Parallel tool cap — e.g. max 3 concurrent MCP calls per request
4. Log query ceiling — e.g. 24h default window; wider requires role
5. Conflict rule — if txn says SUCCESS and logs show ERROR, answer reports conflict and escalates
6. Synthesize→ timeline paragraph + bullet citations + “escalate if dispute” not
Phase H — Change management: models drift; policies do not
ADM question: How does this stay correct as systems and abuse patterns change?
Version MCP tool schemas when txn summary views change
Re-embed runbooks when payment rail changes
Re-run golden questions after model upgrades
Quarterly access review — who can ask what across back office fields
Incident retro— when the assistant was wrong, fix the graph edge or tool, not only the prompt
Phase H is where EA earns trust. Chatbots without change governance become folklore.
What we learned (the “and not vs” section)
LangGraph and deterministic playbooks — not fully autonomous agents on money paths
MCP and strict tool contracts — not credentials in the prompt
RAG and live queries — retrieval for meaning, tools for truth
Speed and auditability — parallel tools help; citations are non-negotiable
The assistant did not replace RTQE (millisecond behavioral queries for CRM/ML) or the fraud engine (hot-path decisioning). It complements them — human-speed investigation across systems that were never one join.
When not to build this
Skip or defer if:
You do not yet have clean transaction summaries — fix data architecture first
Grafana labels cannot reliably scope player or payment correlation
Legal has not signed off on LLM-generated text near player data
The real problem is missing dashboards, not missing synthesis — cheaper fixes exist
EA honesty: sometimes the right ADM outcome is better Grafana boards and a runbook, not an agent.
Wrapping up
A player-query assistant sounds like an AI story. Underneath, it is the same EA work: stakeholders, systems of record, integration boundaries, build vs reuse, and governance on production paths.
LangGraph gives you orchestration you can diagram. MCP gives you enterprise seams your security team can reason about. RAG gives context — if you refuse to let it become a second database of player truth.
If you are standing up something similar: decide Phase C first. Everything else is implementation.